Add pre-commit CI actions (#4982)
* define pre-commit

* add CI code

* configure

* apply pre-commit

* fstring

* apply MD

* pre-commit

* Update torch_utils.py

* Update print strings

* notes

* Cleanup code-format.yml

* Update setup.cfg

* Update .pre-commit-config.yaml

Co-authored-by: Glenn Jocher <glenn.jocher@ultralytics.com>
This commit is contained in:
 Jirka BorovecandGlenn Jocher authored and GitHub committed
1 parent
a4fece8c14
commit
ed887b5976
30 files changed
+273
-113
No files matched your search
@@ -61,10 +61,10 @@ You can leverage W&B artifacts and Tables integration to easily visualize and ma
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
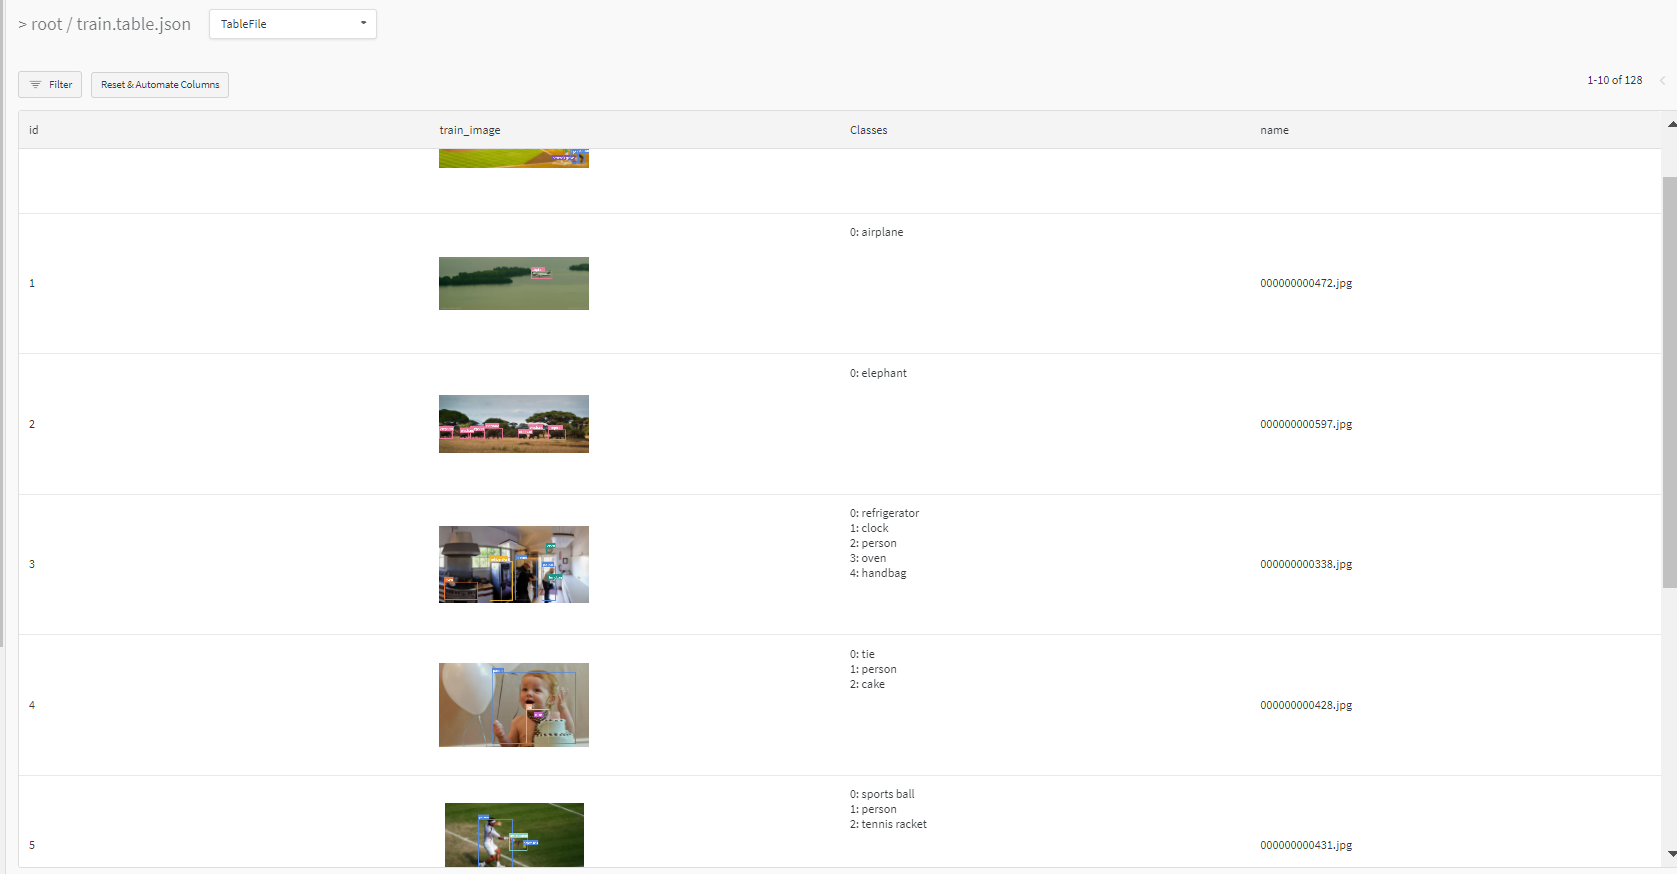
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --project ... --name ... --data .. </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> 2: Train and Log Evaluation simultaneousy </h3>
|
||||
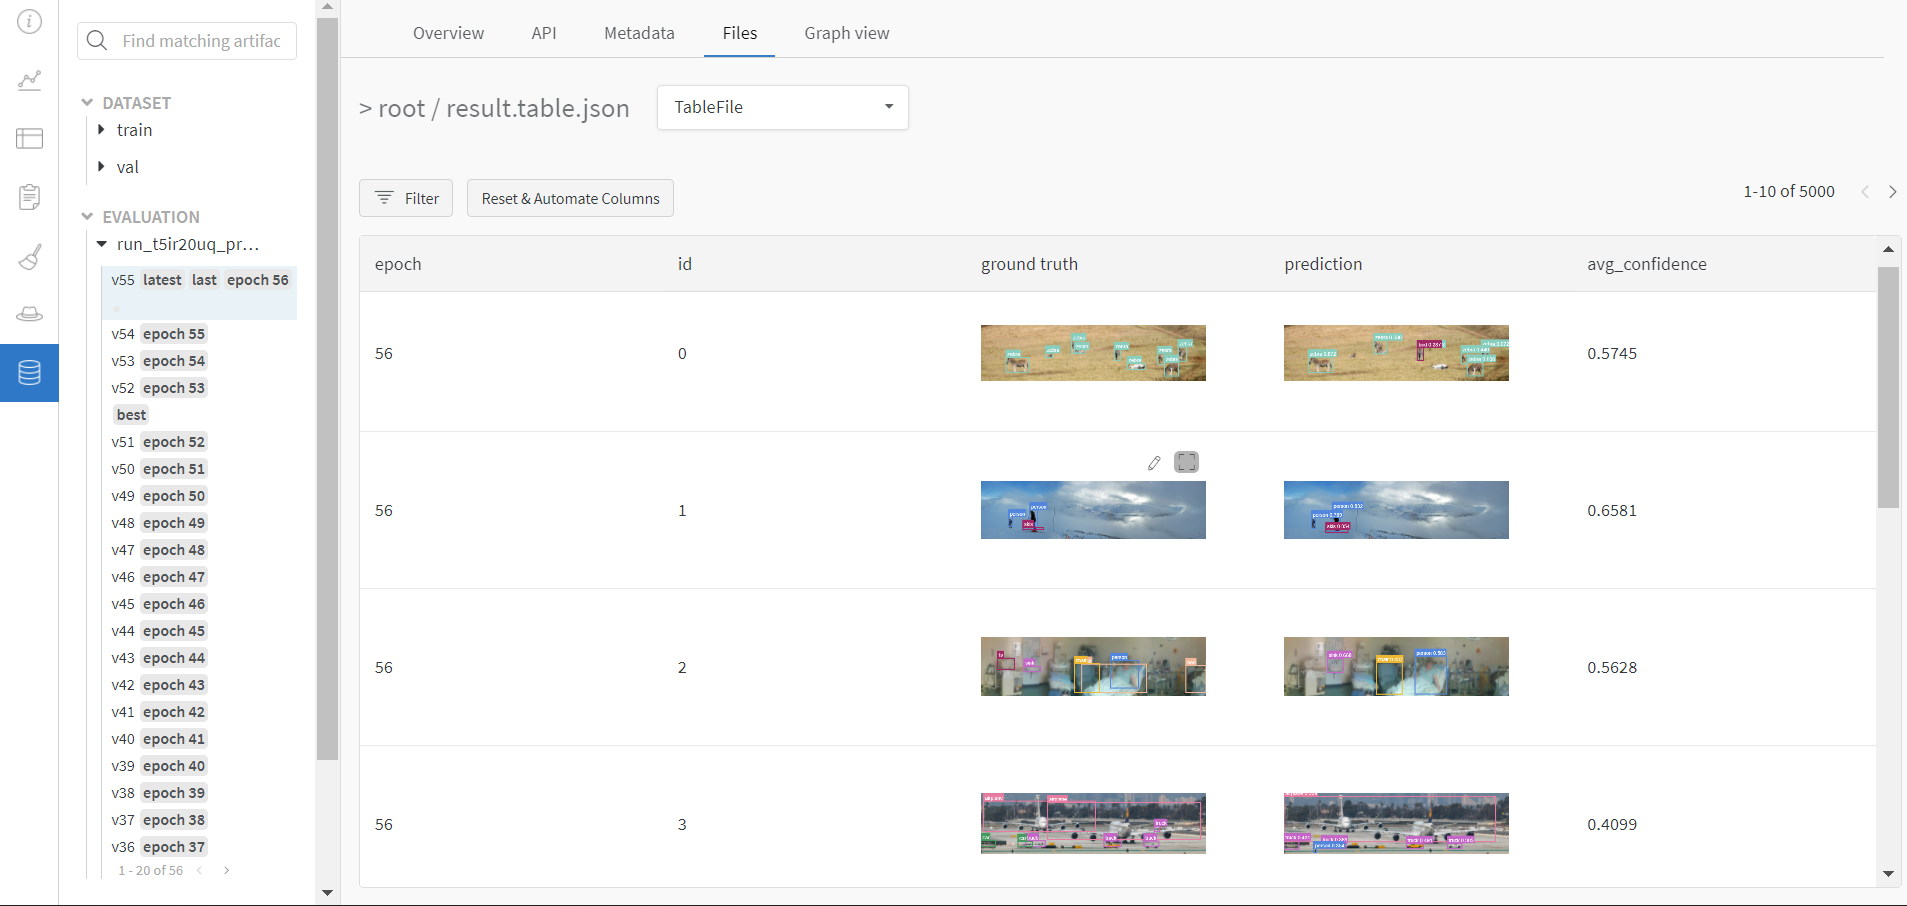
This is an extension of the previous section, but it'll also training after uploading the dataset. <b> This also evaluation Table</b>
|
||||
Evaluation table compares your predictions and ground truths across the validation set for each epoch. It uses the references to the already uploaded datasets,
|
||||
@@ -72,31 +72,31 @@ You can leverage W&B artifacts and Tables integration to easily visualize and ma
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --data .. --upload_data </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> 3: Train using dataset artifact </h3>
|
||||
When you upload a dataset as described in the first section, you get a new config file with an added `_wandb` to its name. This file contains the information that
|
||||
When you upload a dataset as described in the first section, you get a new config file with an added `_wandb` to its name. This file contains the information that
|
||||
can be used to train a model directly from the dataset artifact. <b> This also logs evaluation </b>
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --data {data}_wandb.yaml </code>
|
||||
|
||||
|
||||

|
||||
</details>
|
||||
|
||||
|
||||
<h3> 4: Save model checkpoints as artifacts </h3>
|
||||
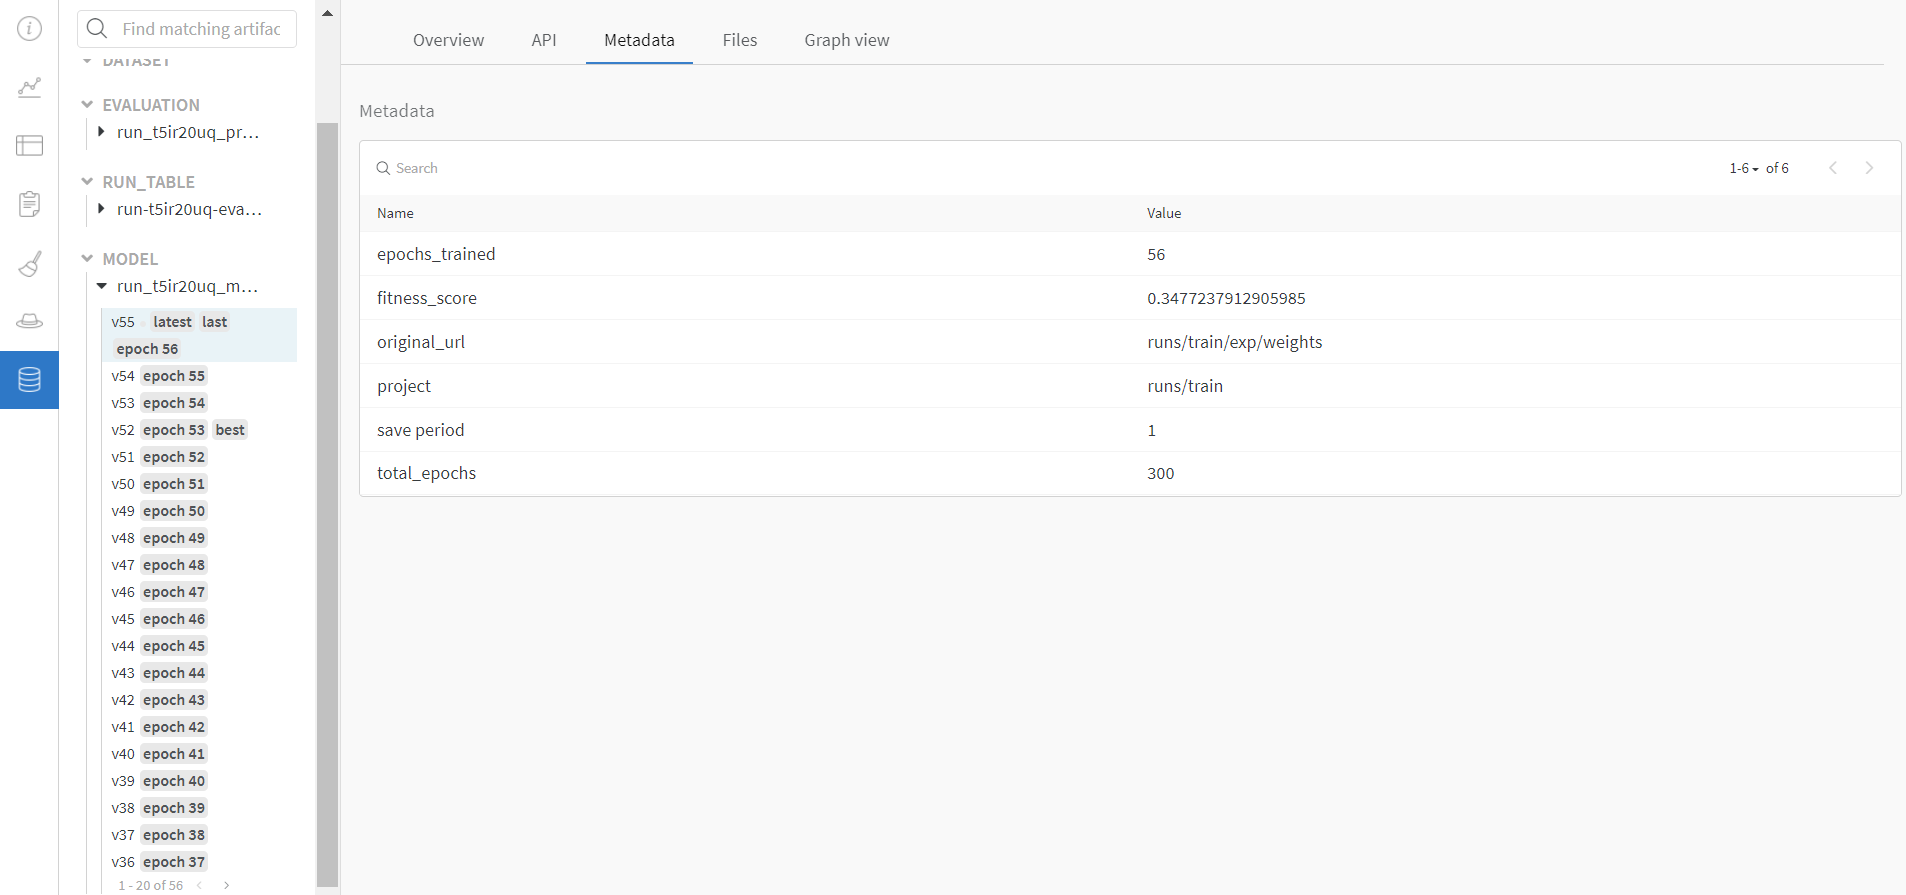
To enable saving and versioning checkpoints of your experiment, pass `--save_period n` with the base cammand, where `n` represents checkpoint interval.
|
||||
To enable saving and versioning checkpoints of your experiment, pass `--save_period n` with the base cammand, where `n` represents checkpoint interval.
|
||||
You can also log both the dataset and model checkpoints simultaneously. If not passed, only the final model will be logged
|
||||
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --save_period 1 </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<h3> 5: Resume runs from checkpoint artifacts. </h3>
|
||||
@@ -105,28 +105,28 @@ Any run can be resumed using artifacts if the <code>--resume</code> argument sta
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
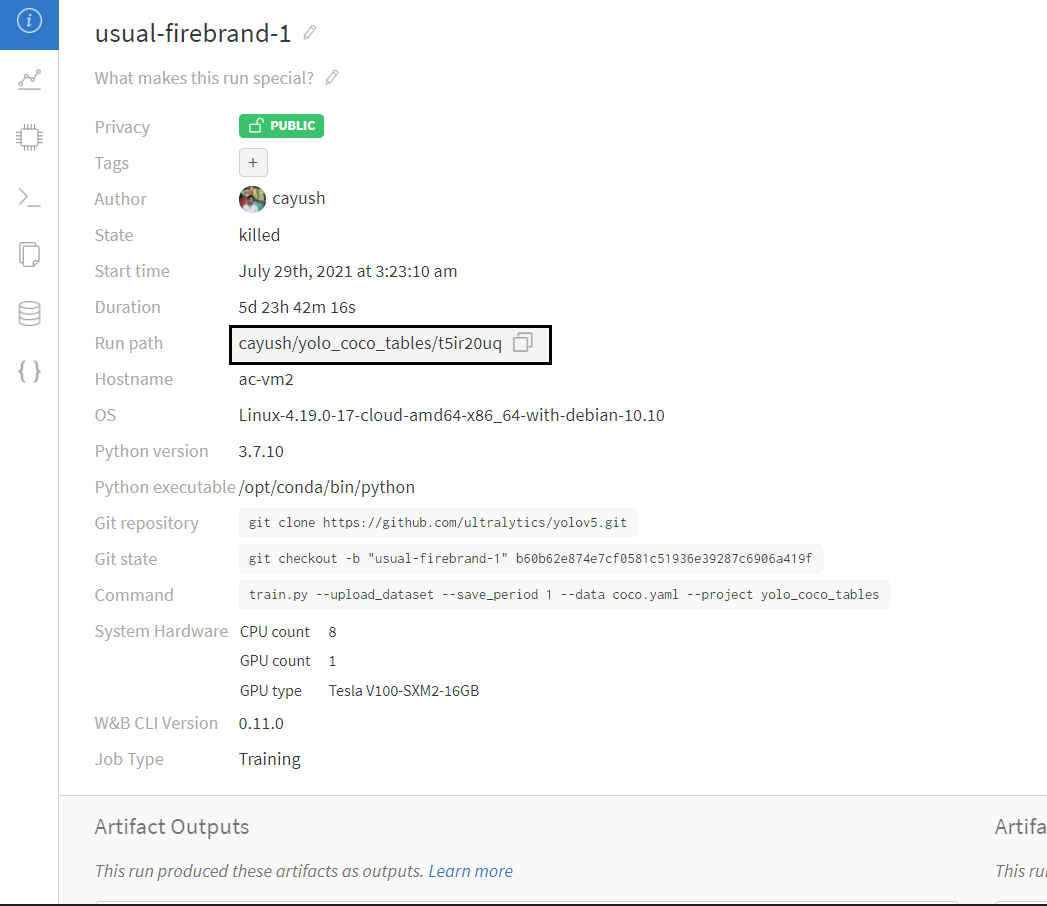
<b>Code</b> <code> $ python train.py --resume wandb-artifact://{run_path} </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> 6: Resume runs from dataset artifact & checkpoint artifacts. </h3>
|
||||
<b> Local dataset or model checkpoints are not required. This can be used to resume runs directly on a different device </b>
|
||||
The syntax is same as the previous section, but you'll need to lof both the dataset and model checkpoints as artifacts, i.e, set bot <code>--upload_dataset</code> or
|
||||
The syntax is same as the previous section, but you'll need to lof both the dataset and model checkpoints as artifacts, i.e, set bot <code>--upload_dataset</code> or
|
||||
train from <code>_wandb.yaml</code> file and set <code>--save_period</code>
|
||||
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --resume wandb-artifact://{run_path} </code>
|
||||
|
||||
|
||||

|
||||
</details>
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> Reports </h3>
|
||||
W&B Reports can be created from your saved runs for sharing online. Once a report is created you will receive a link you can use to publically share your results. Here is an example report created from the COCO128 tutorial trainings of all four YOLOv5 models ([link](https://wandb.ai/glenn-jocher/yolov5_tutorial/reports/YOLOv5-COCO128-Tutorial-Results--VmlldzozMDI5OTY)).
|
||||
|
||||
|
||||
<img width="900" alt="Weights & Biases Reports" src="https://user-images.githubusercontent.com/26833433/135394029-a17eaf86-c6c1-4b1d-bb80-b90e83aaffa7.png">
|
||||
|
||||
|
||||
|
||||
Reference in new issue
Block a user