Ultralytics Refactor https://ultralytics.com/actions (#13553)
* Refactor code for speed and clarity

* Auto-format by https://ultralytics.com/actions

* Update README.md

Signed-off-by: Glenn Jocher <glenn.jocher@ultralytics.com>

---------

Signed-off-by: Glenn Jocher <glenn.jocher@ultralytics.com>
Co-authored-by: Glenn Jocher <glenn.jocher@ultralytics.com>
Co-authored-by: UltralyticsAssistant <web@ultralytics.com>
This commit is contained in:

13 files changed
+484
-390
No files matched your search
+124
-122
@@ -1,222 +1,224 @@
|
||||
# ClearML Integration
|
||||
<a href="https://www.ultralytics.com/"><img src="https://raw.githubusercontent.com/ultralytics/assets/main/logo/Ultralytics_Logotype_Original.svg" width="320" alt="Ultralytics logo"></a>
|
||||
|
||||
# ClearML Integration with Ultralytics YOLOv5
|
||||
|
||||
<img align="center" src="https://github.com/thepycoder/clearml_screenshots/raw/main/logos_dark.png#gh-light-mode-only" alt="Clear|ML"><img align="center" src="https://github.com/thepycoder/clearml_screenshots/raw/main/logos_light.png#gh-dark-mode-only" alt="Clear|ML">
|
||||
|
||||
## About ClearML
|
||||
## ℹ️ About ClearML
|
||||
|
||||
[ClearML](https://clear.ml/) is an [open-source](https://github.com/clearml/clearml) toolbox designed to save you time ⏱️.
|
||||
[ClearML](https://clear.ml/) is an [open-source](https://github.com/clearml/clearml) MLOps platform designed to streamline your machine learning workflow and save you valuable time ⏱️. Integrating ClearML with Ultralytics YOLOv5 allows you to leverage a powerful suite of tools:
|
||||
|
||||
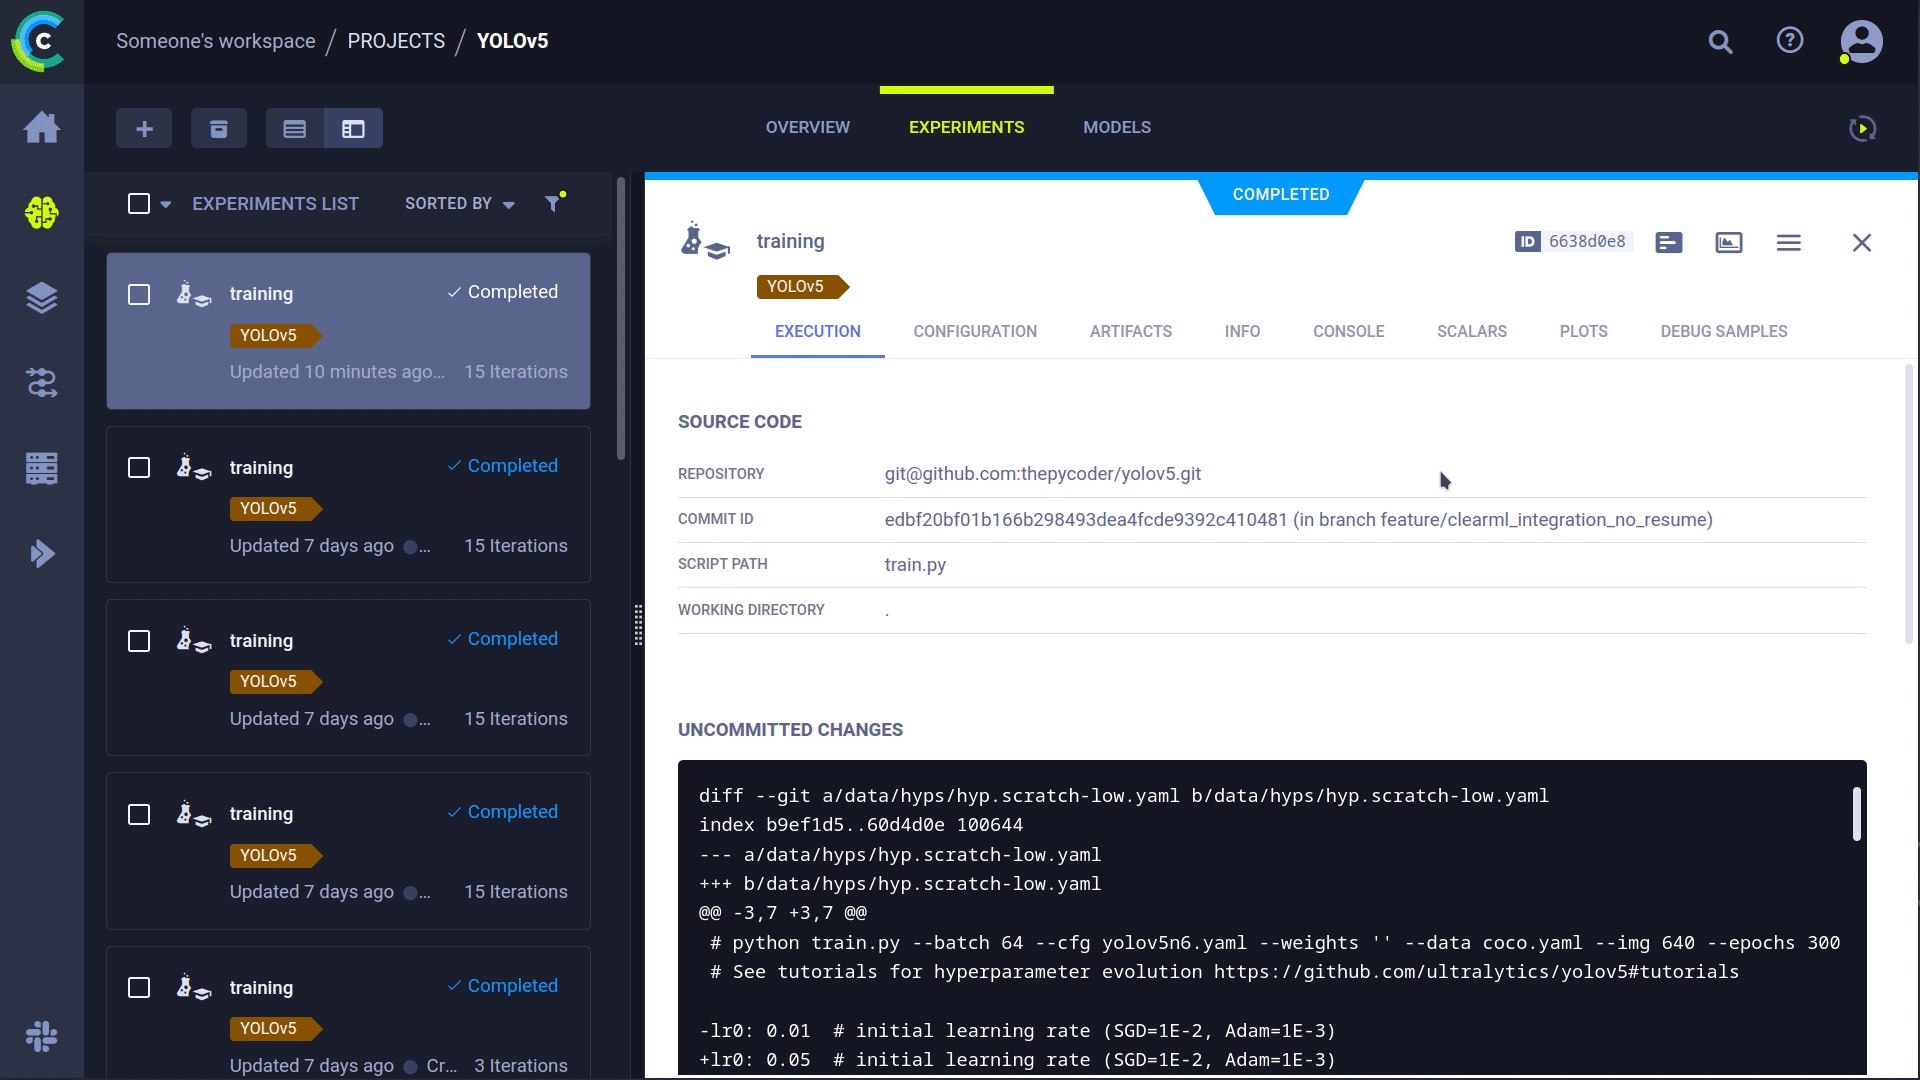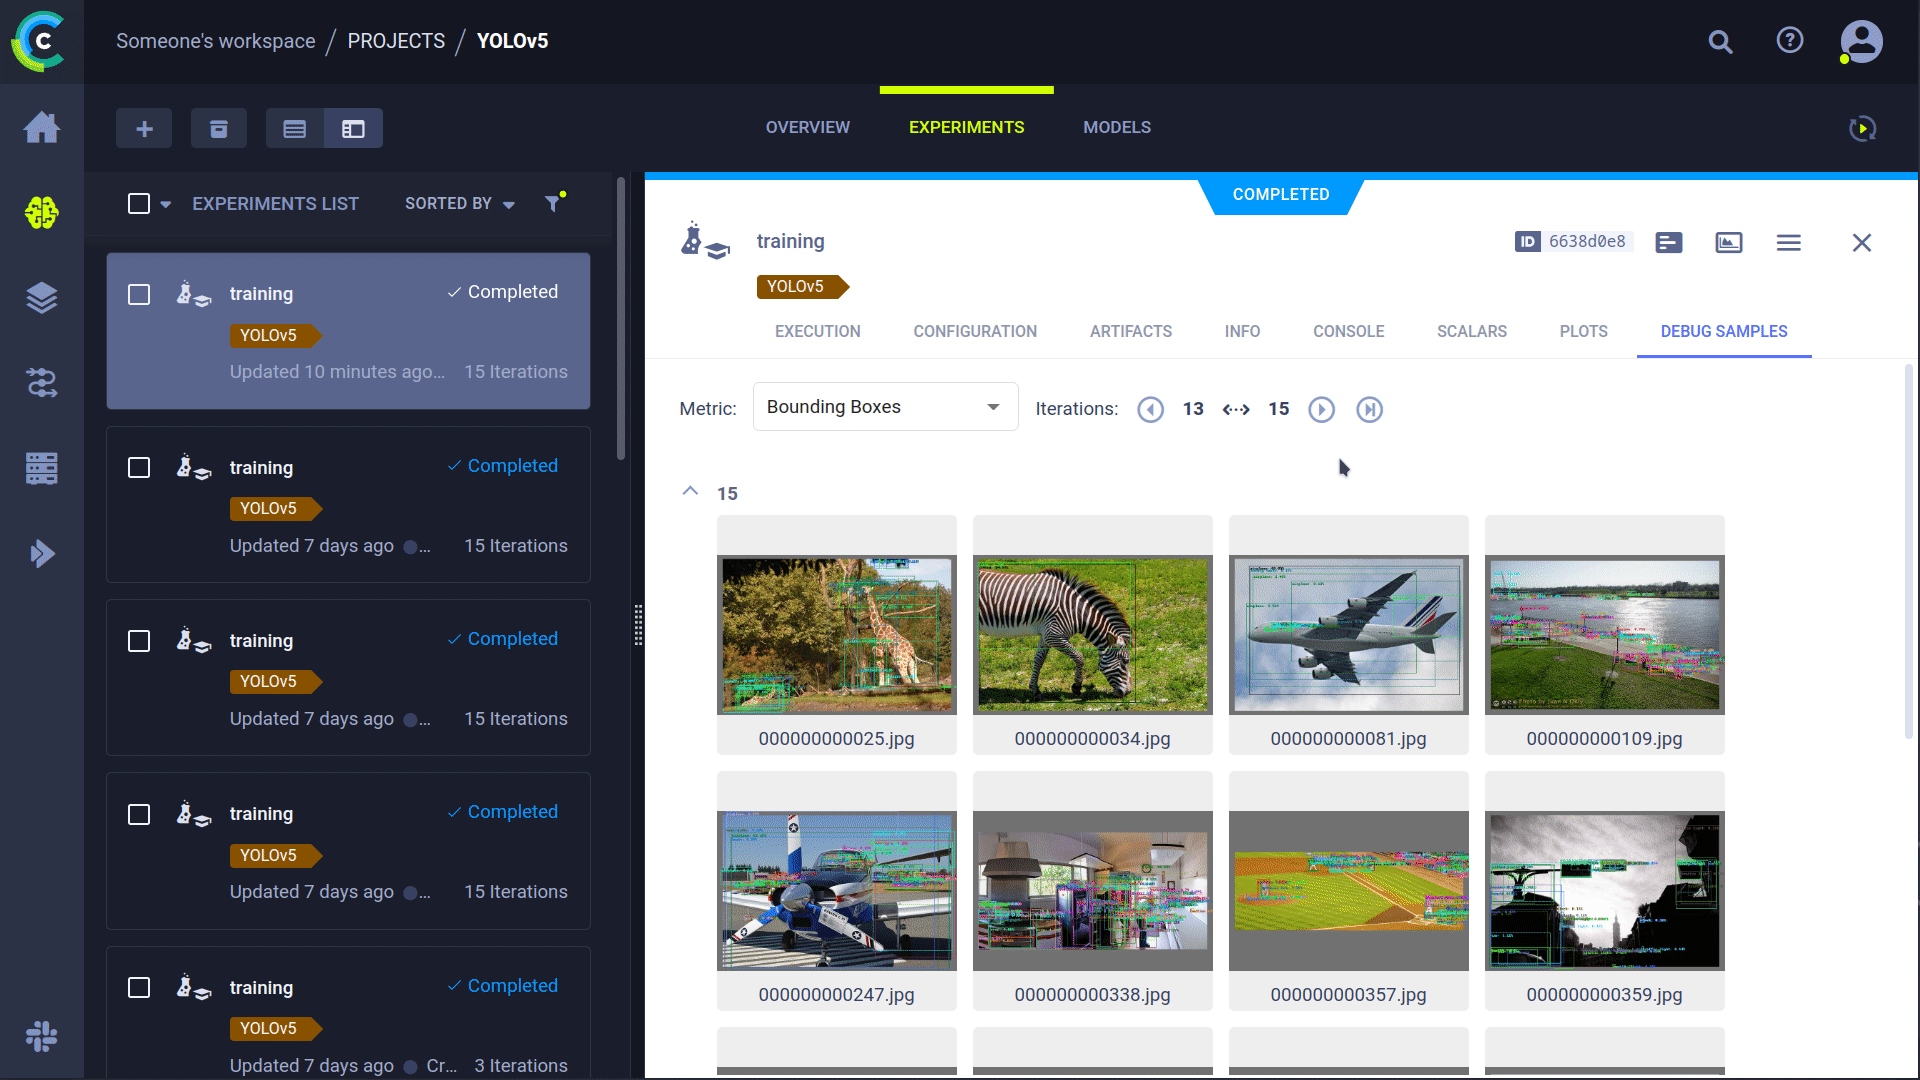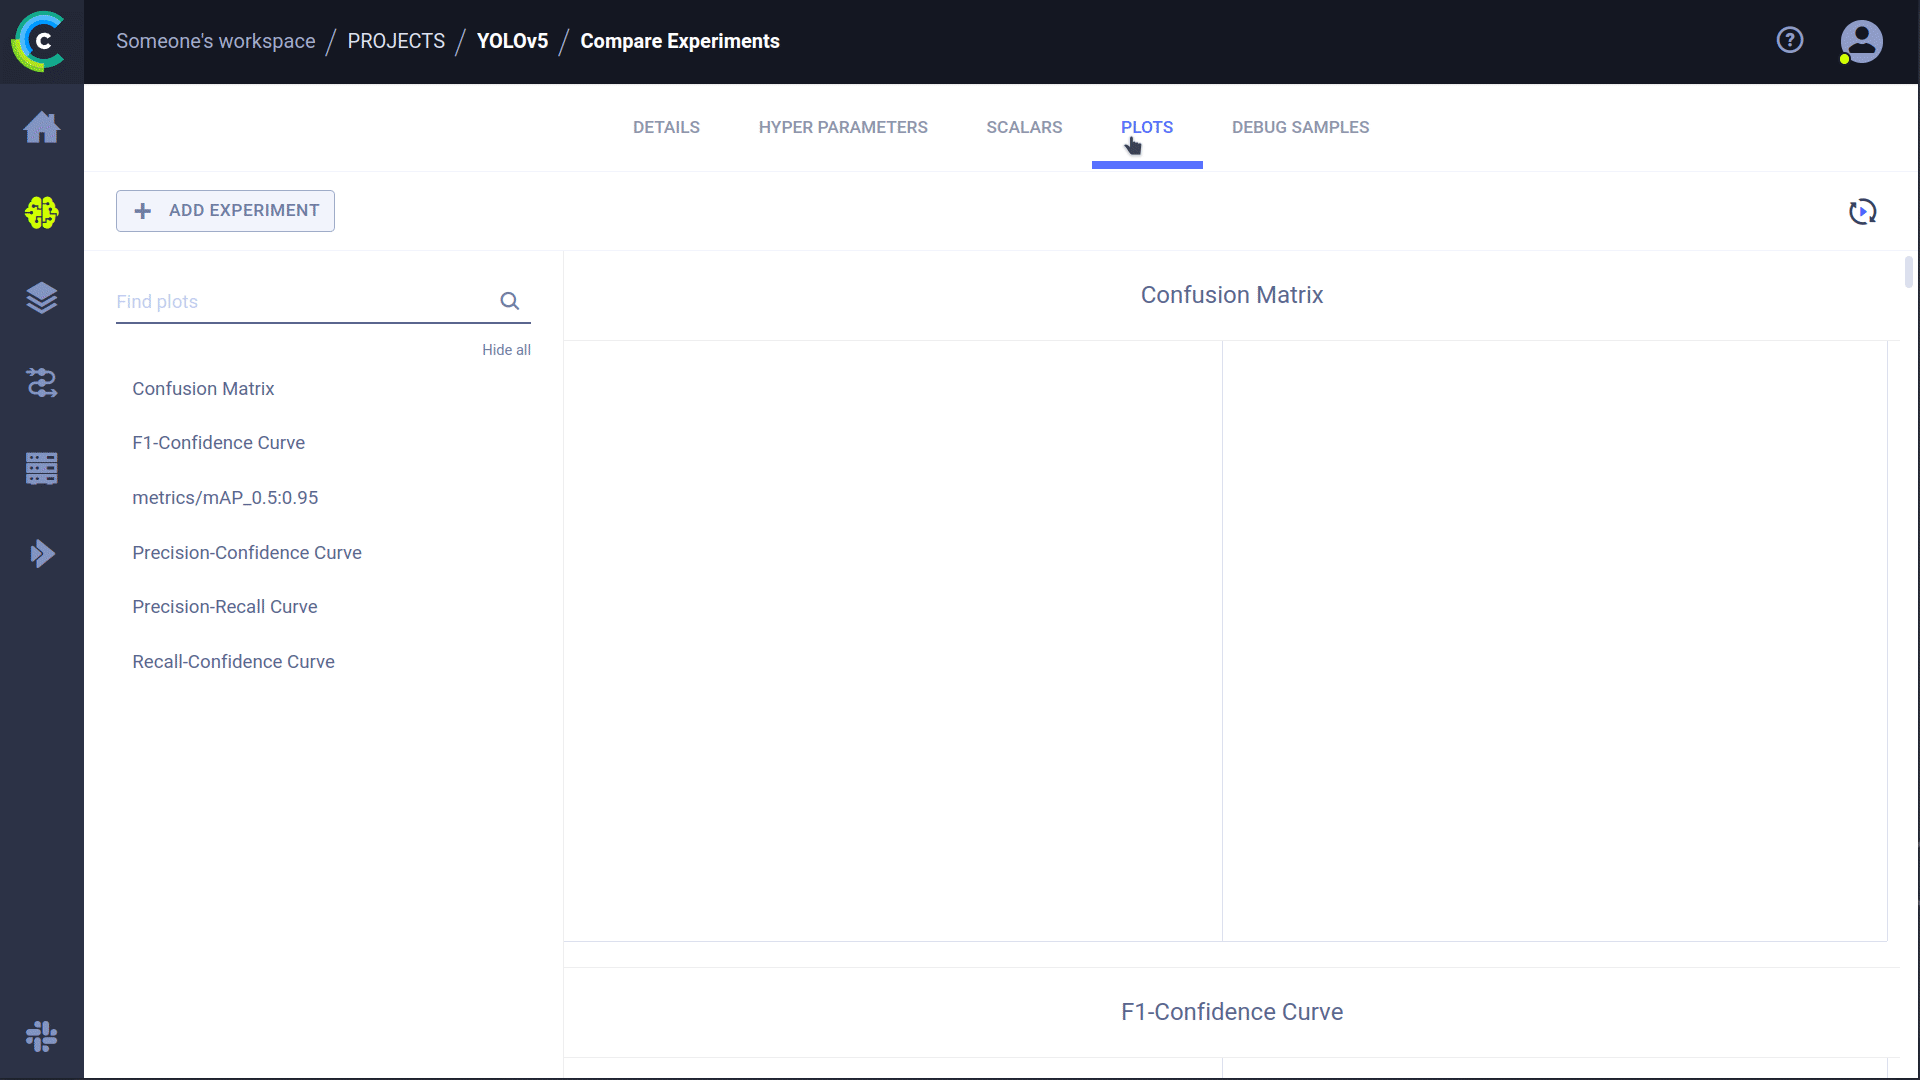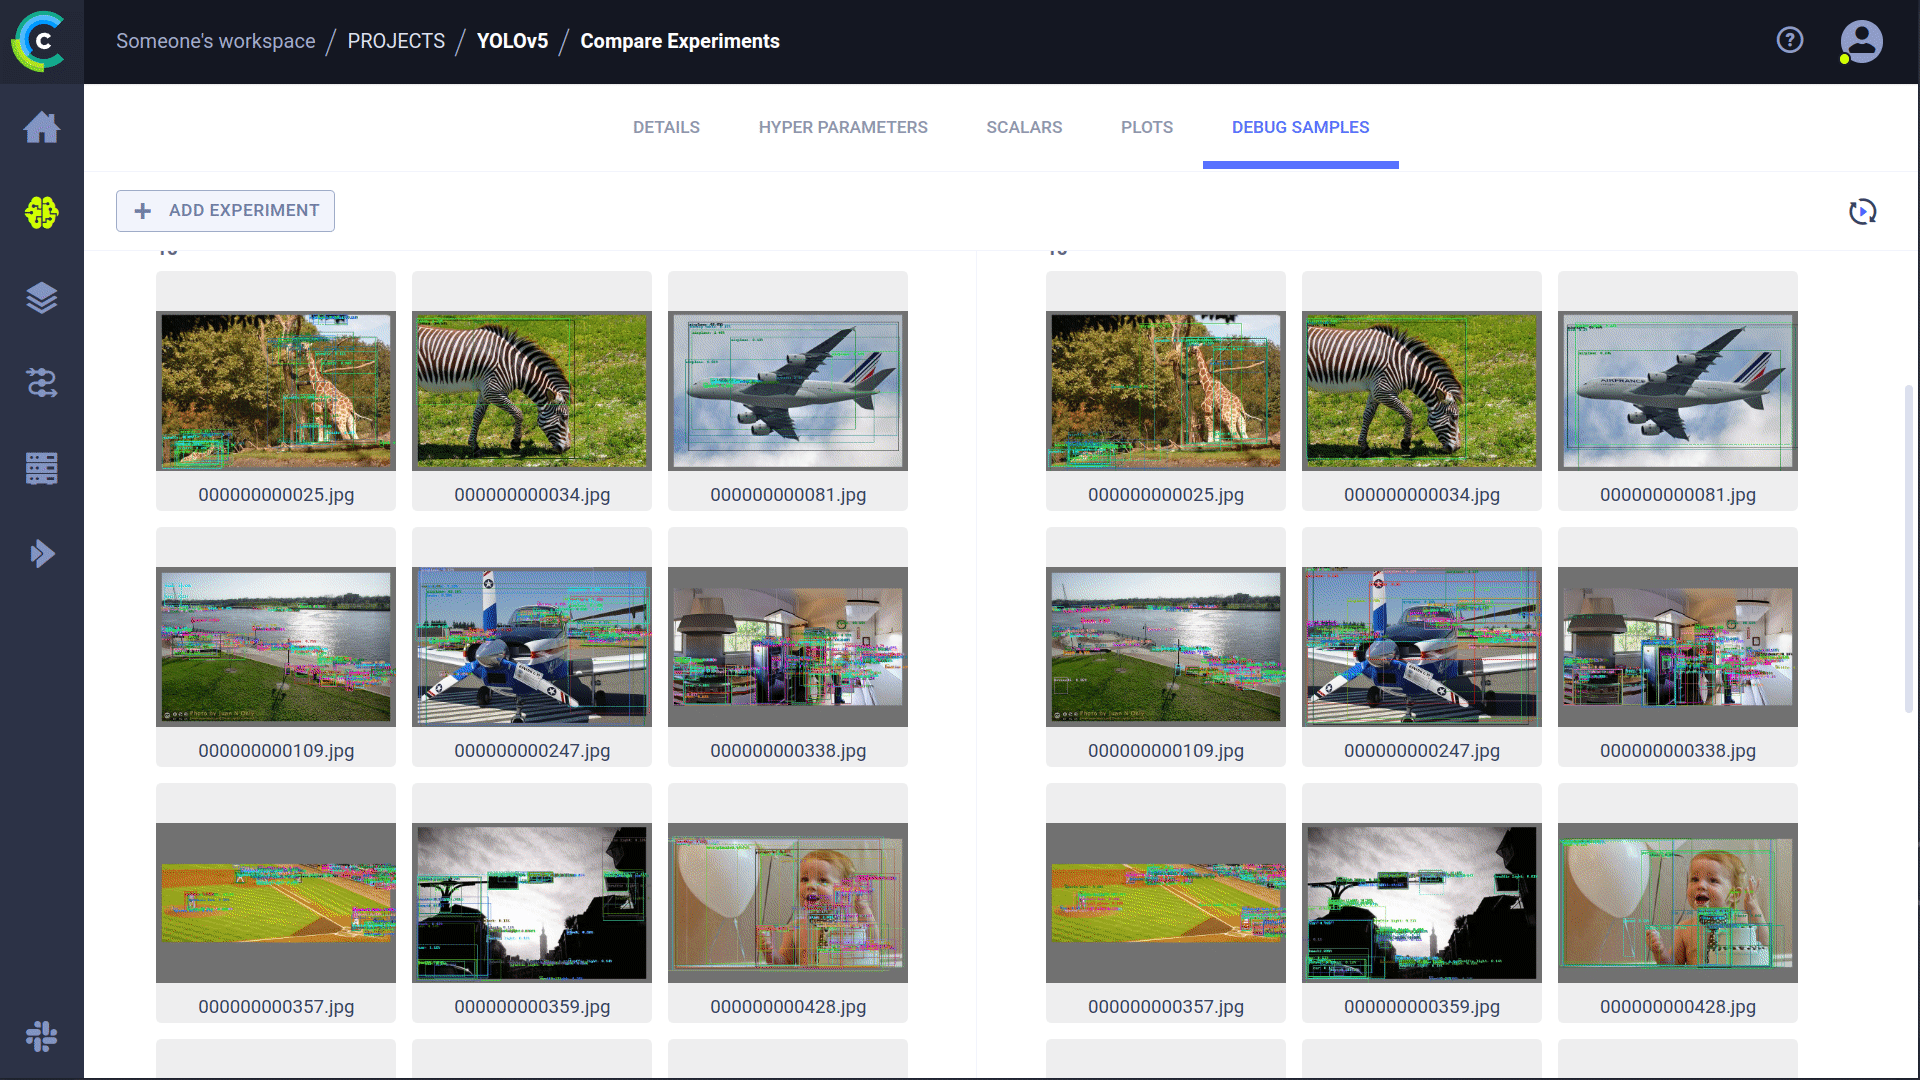
🔨 Track every YOLOv5 training run in the <b>experiment manager</b>
|
||||
- **Experiment Management:** 🔨 Track every [YOLOv5](https://docs.ultralytics.com/models/yolov5/) training run, including parameters, metrics, and outputs. See the [Ultralytics ClearML integration guide](https://docs.ultralytics.com/integrations/clearml/) for more details.
|
||||
- **Data Versioning:** 🔧 Version and easily access your custom training data using the integrated ClearML Data Versioning Tool, similar to concepts in [DVC integration](https://docs.ultralytics.com/integrations/dvc/).
|
||||
- **Remote Execution:** 🔦 [Remotely train and monitor](https://docs.ultralytics.com/hub/cloud-training/) your YOLOv5 models using ClearML Agent.
|
||||
- **Hyperparameter Optimization:** 🔬 Achieve optimal [Mean Average Precision (mAP)](https://docs.ultralytics.com/guides/yolo-performance-metrics/) using ClearML's [Hyperparameter Optimization](https://docs.ultralytics.com/guides/hyperparameter-tuning/) capabilities.
|
||||
- **Model Deployment:** 🔭 Turn your trained YOLOv5 model into an API with just a few commands using ClearML Serving, complementing [Ultralytics deployment options](https://docs.ultralytics.com/guides/model-deployment-options/).
|
||||
|
||||
🔧 Version and easily access your custom training data with the integrated ClearML <b>Data Versioning Tool</b>
|
||||
|
||||
🔦 <b>Remotely train and monitor</b> your YOLOv5 training runs using ClearML Agent
|
||||
|
||||
🔬 Get the very best mAP using ClearML <b>Hyperparameter Optimization</b>
|
||||
|
||||
🔭 Turn your newly trained <b>YOLOv5 model into an API</b> with just a few commands using ClearML Serving
|
||||
|
||||
And so much more. It's up to you how many of these tools you want to use, you can stick to the experiment manager, or chain them all together into an impressive pipeline!
|
||||
You can choose to use only the experiment manager or combine multiple tools into a comprehensive MLOps pipeline.
|
||||
|
||||
|
||||
|
||||
## 🦾 Setting Things Up
|
||||
|
||||
To keep track of your experiments and/or data, ClearML needs to communicate to a server. You have 2 options to get one:
|
||||
ClearML requires communication with a server to track experiments and data. You have two main options:
|
||||
|
||||
Either sign up for free to the [ClearML Hosted Service](https://clear.ml/) or you can set up your own server, see [here](https://clear.ml/docs/latest/docs/deploying_clearml/clearml_server). Even the server is open-source, so even if you're dealing with sensitive data, you should be good to go!
|
||||
1. **ClearML Hosted Service:** Sign up for a free account at [app.clear.ml](https://app.clear.ml/).
|
||||
2. **Self-Hosted Server:** Set up your own ClearML server. Find instructions [here](https://clear.ml/docs/latest/docs/deploying_clearml/clearml_server). The server is also open-source, ensuring data privacy.
|
||||
|
||||
1. Install the `clearml` python package:
|
||||
Follow these steps to get started:
|
||||
|
||||
```bash
|
||||
pip install clearml
|
||||
```
|
||||
1. Install the `clearml` Python package:
|
||||
|
||||
2. Connect the ClearML SDK to the server by [creating credentials](https://app.clear.ml/settings/workspace-configuration) (go right top to Settings -> Workspace -> Create new credentials), then execute the command below and follow the instructions:
|
||||
```bash
|
||||
pip install clearml
|
||||
```
|
||||
|
||||
```bash
|
||||
clearml-init
|
||||
```
|
||||
_Note: This package is included in the `requirements.txt` of YOLOv5._
|
||||
|
||||
That's it! You're done 😎
|
||||
2. Connect the ClearML SDK to your server. [Create credentials](https://app.clear.ml/settings/workspace-configuration) (Settings -> Workspace -> Create new credentials), then run the following command and follow the prompts:
|
||||
```bash
|
||||
clearml-init
|
||||
```
|
||||
|
||||
That's it! You're ready to integrate ClearML with your YOLOv5 projects 😎. For a general Ultralytics setup, see the [Quickstart Guide](https://docs.ultralytics.com/quickstart/).
|
||||
|
||||
## 🚀 Training YOLOv5 With ClearML
|
||||
|
||||
To enable ClearML experiment tracking, simply install the ClearML pip package.
|
||||
|
||||
```bash
|
||||
pip install clearml
|
||||
```
|
||||
|
||||
This will enable integration with the YOLOv5 training script. Every training run from now on, will be captured and stored by the ClearML experiment manager.
|
||||
|
||||
If you want to change the `project_name` or `task_name`, use the `--project` and `--name` arguments of the `train.py` script, by default the project will be called `YOLOv5` and the task `Training`. PLEASE NOTE: ClearML uses `/` as a delimiter for subprojects, so be careful when using `/` in your project name!
|
||||
ClearML experiment tracking is automatically enabled when the `clearml` package is installed. Every YOLOv5 [training run](https://docs.ultralytics.com/modes/train/) will be captured and stored in the ClearML experiment manager.
|
||||
|
||||
To customize the project or task name in ClearML, use the `--project` and `--name` arguments when running `train.py`. By default, the project is `YOLOv5` and the task is `Training`. Note that ClearML uses `/` as a delimiter for subprojects.
|
||||
|
||||
**Example Training Command:**
|
||||
|
||||
```bash
|
||||
# Train YOLOv5s on COCO128 dataset for 3 epochs
|
||||
python train.py --img 640 --batch 16 --epochs 3 --data coco128.yaml --weights yolov5s.pt --cache
|
||||
```
|
||||
|
||||
or with custom project and task name:
|
||||
**Example with Custom Project and Task Names:**
|
||||
|
||||
```bash
|
||||
python train.py --project my_project --name my_training --img 640 --batch 16 --epochs 3 --data coco128.yaml --weights yolov5s.pt --cache
|
||||
# Train with custom names
|
||||
python train.py --project my_yolo_project --name experiment_001 --img 640 --batch 16 --epochs 3 --data coco128.yaml --weights yolov5s.pt --cache
|
||||
```
|
||||
|
||||
This will capture:
|
||||
ClearML automatically captures comprehensive information about your training run:
|
||||
|
||||
- Source code + uncommitted changes
|
||||
- Installed packages
|
||||
- (Hyper)parameters
|
||||
- Model files (use `--save-period n` to save a checkpoint every n epochs)
|
||||
- Console output
|
||||
- Scalars (mAP_0.5, mAP_0.5:0.95, precision, recall, losses, learning rates, ...)
|
||||
- General info such as machine details, runtime, creation date etc.
|
||||
- All produced plots such as label correlogram and confusion matrix
|
||||
- Source code and uncommitted changes
|
||||
- Installed Python packages
|
||||
- Hyperparameters and configuration settings
|
||||
- Model checkpoints (use `--save-period n` to save every `n` epochs)
|
||||
- Console output logs
|
||||
- Performance metrics ([mAP_0.5](https://docs.ultralytics.com/guides/yolo-performance-metrics/), mAP_0.5:0.95, [precision, recall](https://docs.ultralytics.com/guides/yolo-performance-metrics/), [losses](https://docs.ultralytics.com/reference/utils/loss/), [learning rates](https://www.ultralytics.com/glossary/learning-rate), etc.)
|
||||
- System details (machine specs, runtime, creation date)
|
||||
- Generated plots (e.g., label correlogram, [confusion matrix](https://www.ultralytics.com/glossary/confusion-matrix))
|
||||
- Images with bounding boxes per epoch
|
||||
- Mosaic per epoch
|
||||
- Mosaic augmentation previews per epoch
|
||||
- Validation images per epoch
|
||||
- ...
|
||||
|
||||
That's a lot right? 🤯 Now, we can visualize all of this information in the ClearML UI to get an overview of our training progress. Add custom columns to the table view (such as e.g. mAP_0.5) so you can easily sort on the best performing model. Or select multiple experiments and directly compare them!
|
||||
|
||||
There even more we can do with all of this information, like hyperparameter optimization and remote execution, so keep reading if you want to see how that works!
|
||||
This wealth of information 🤯 can be visualized in the ClearML UI. You can customize table views, sort experiments by metrics like mAP, and directly compare multiple runs. This detailed tracking enables advanced features like hyperparameter optimization and remote execution.
|
||||
|
||||
## 🔗 Dataset Version Management
|
||||
|
||||
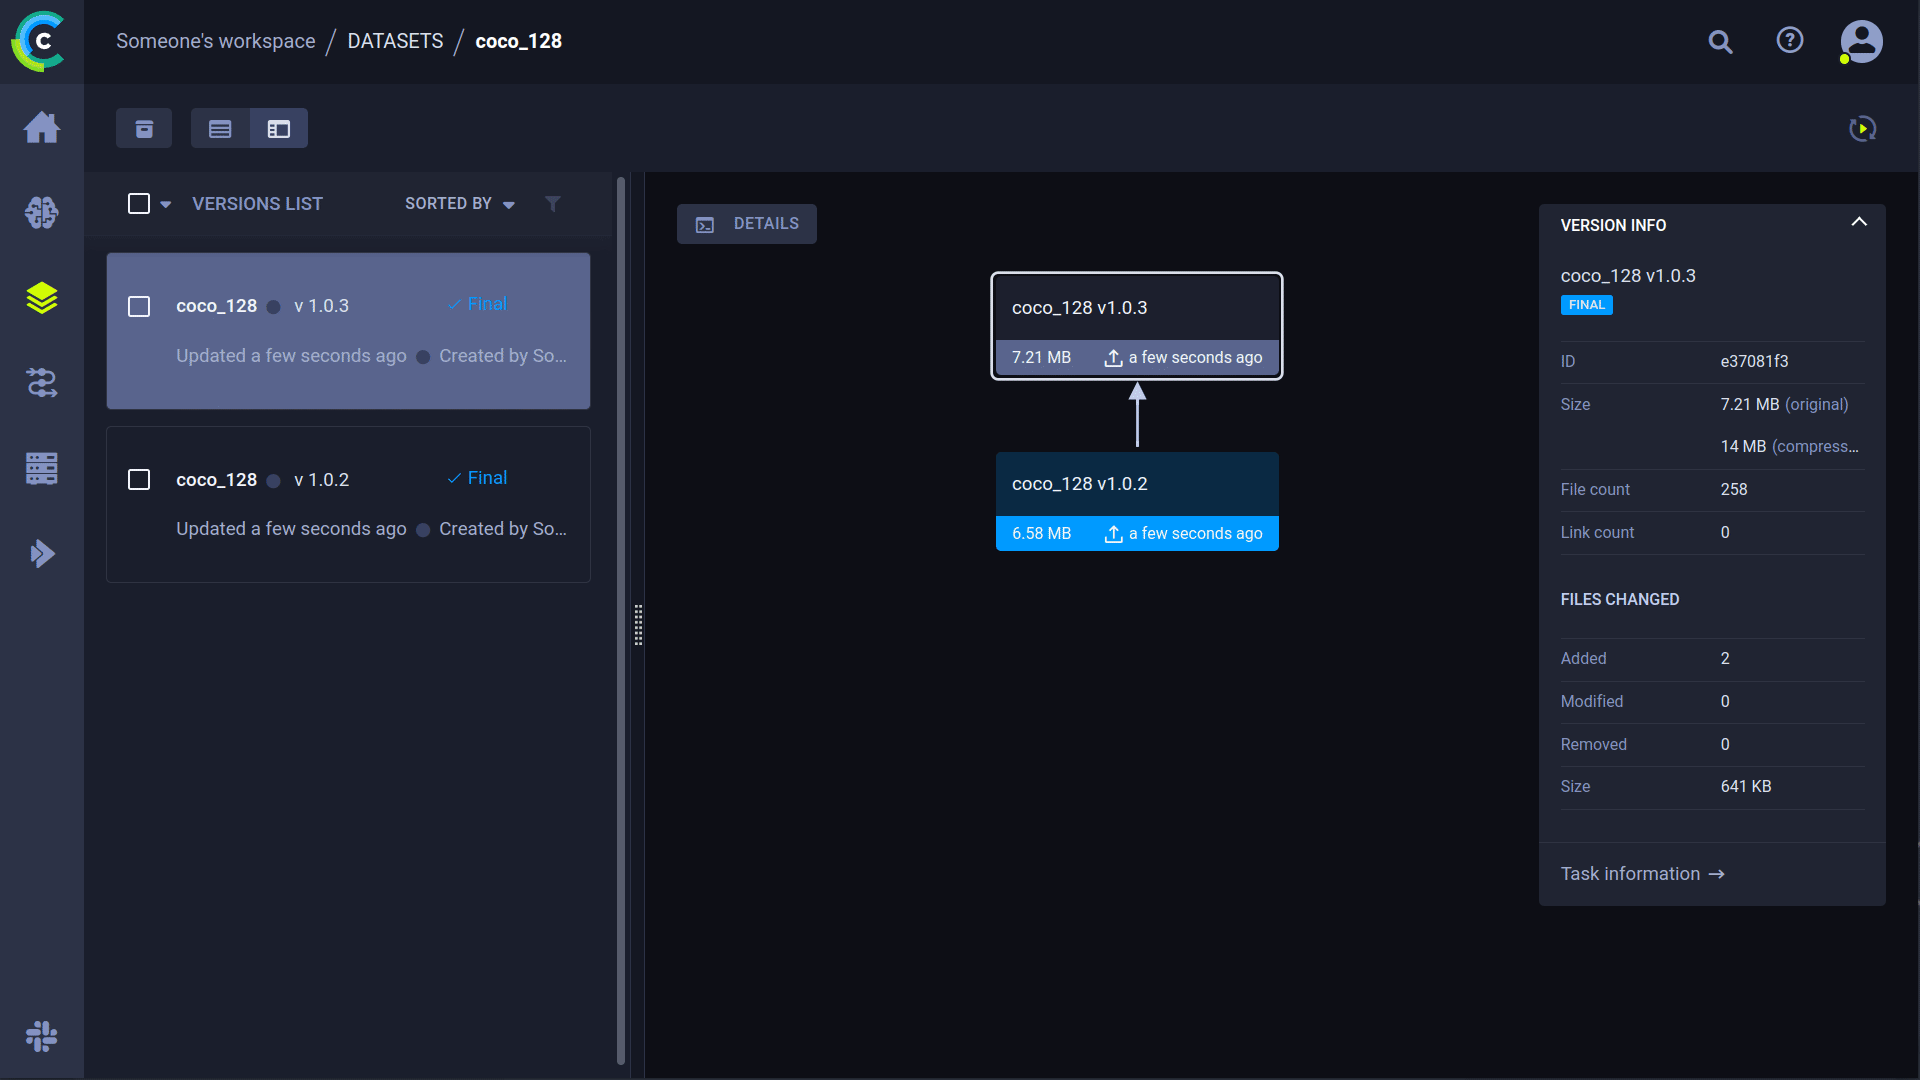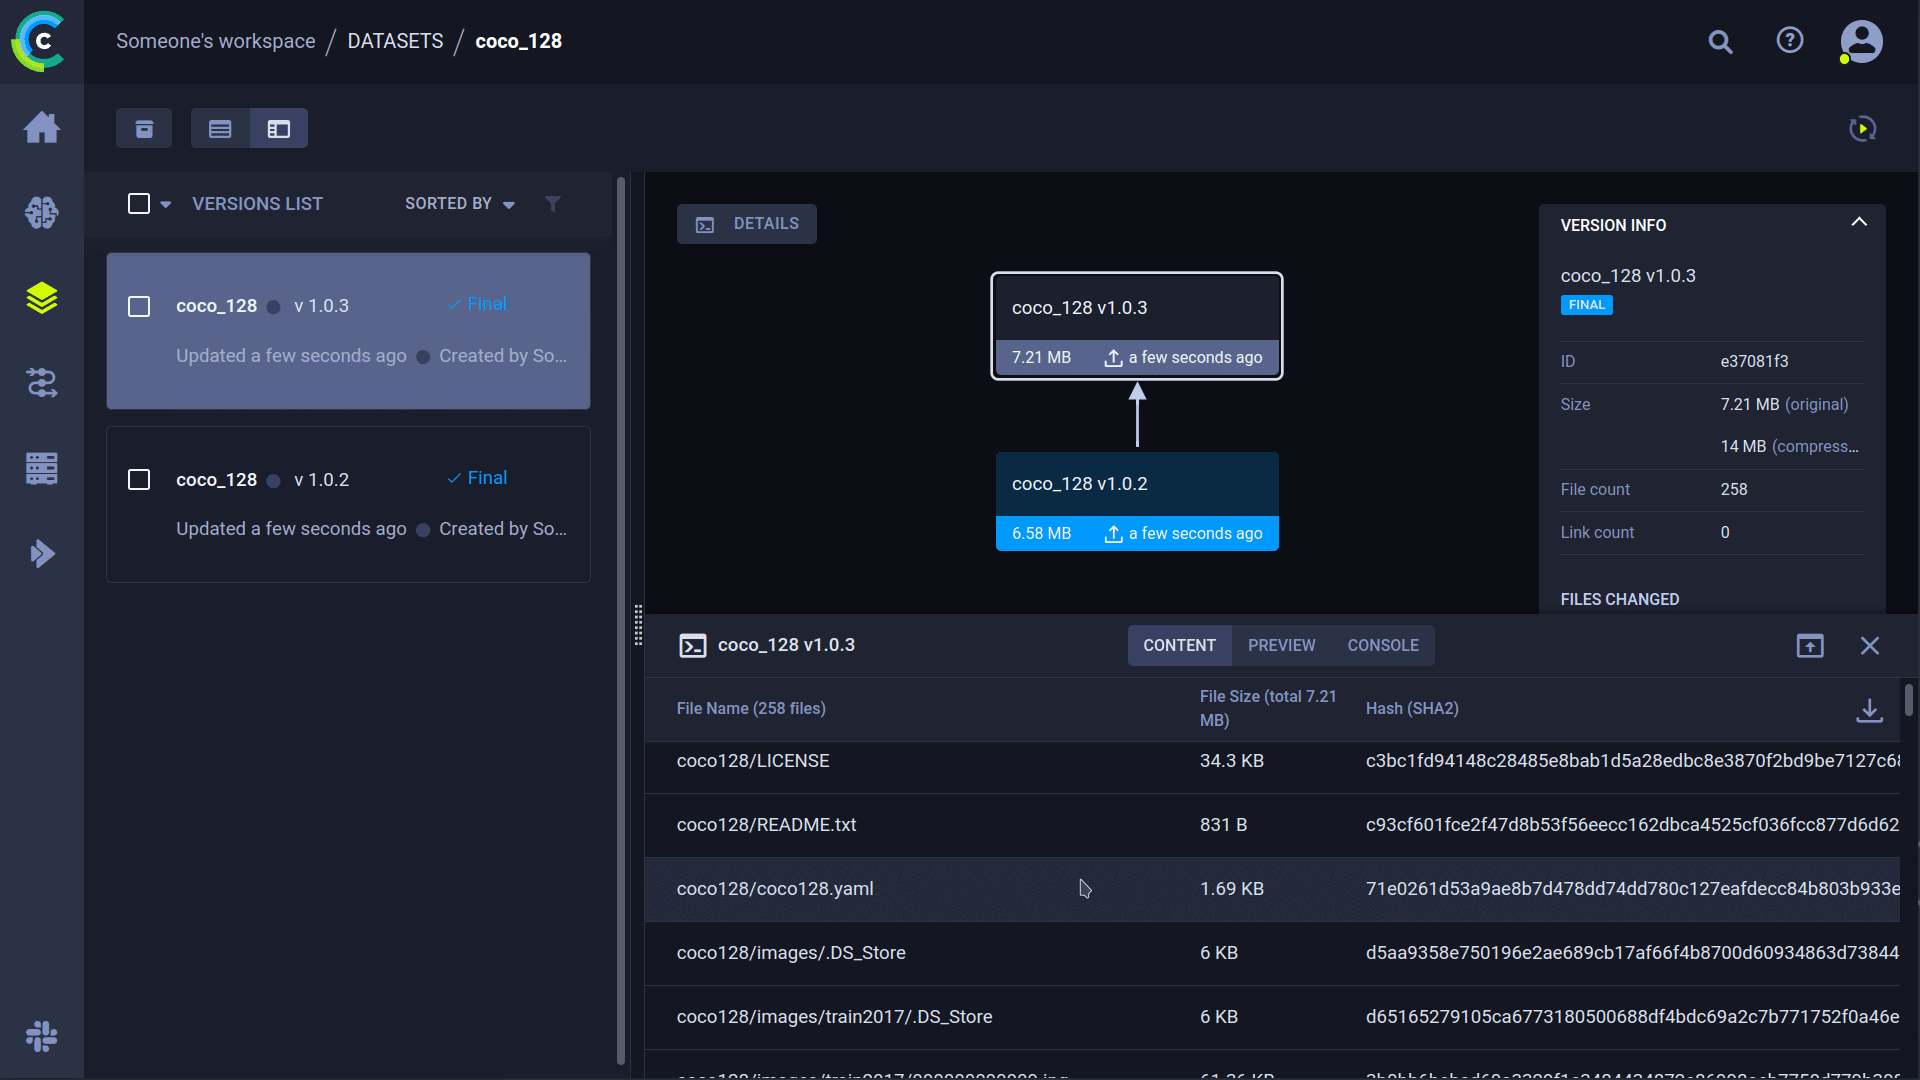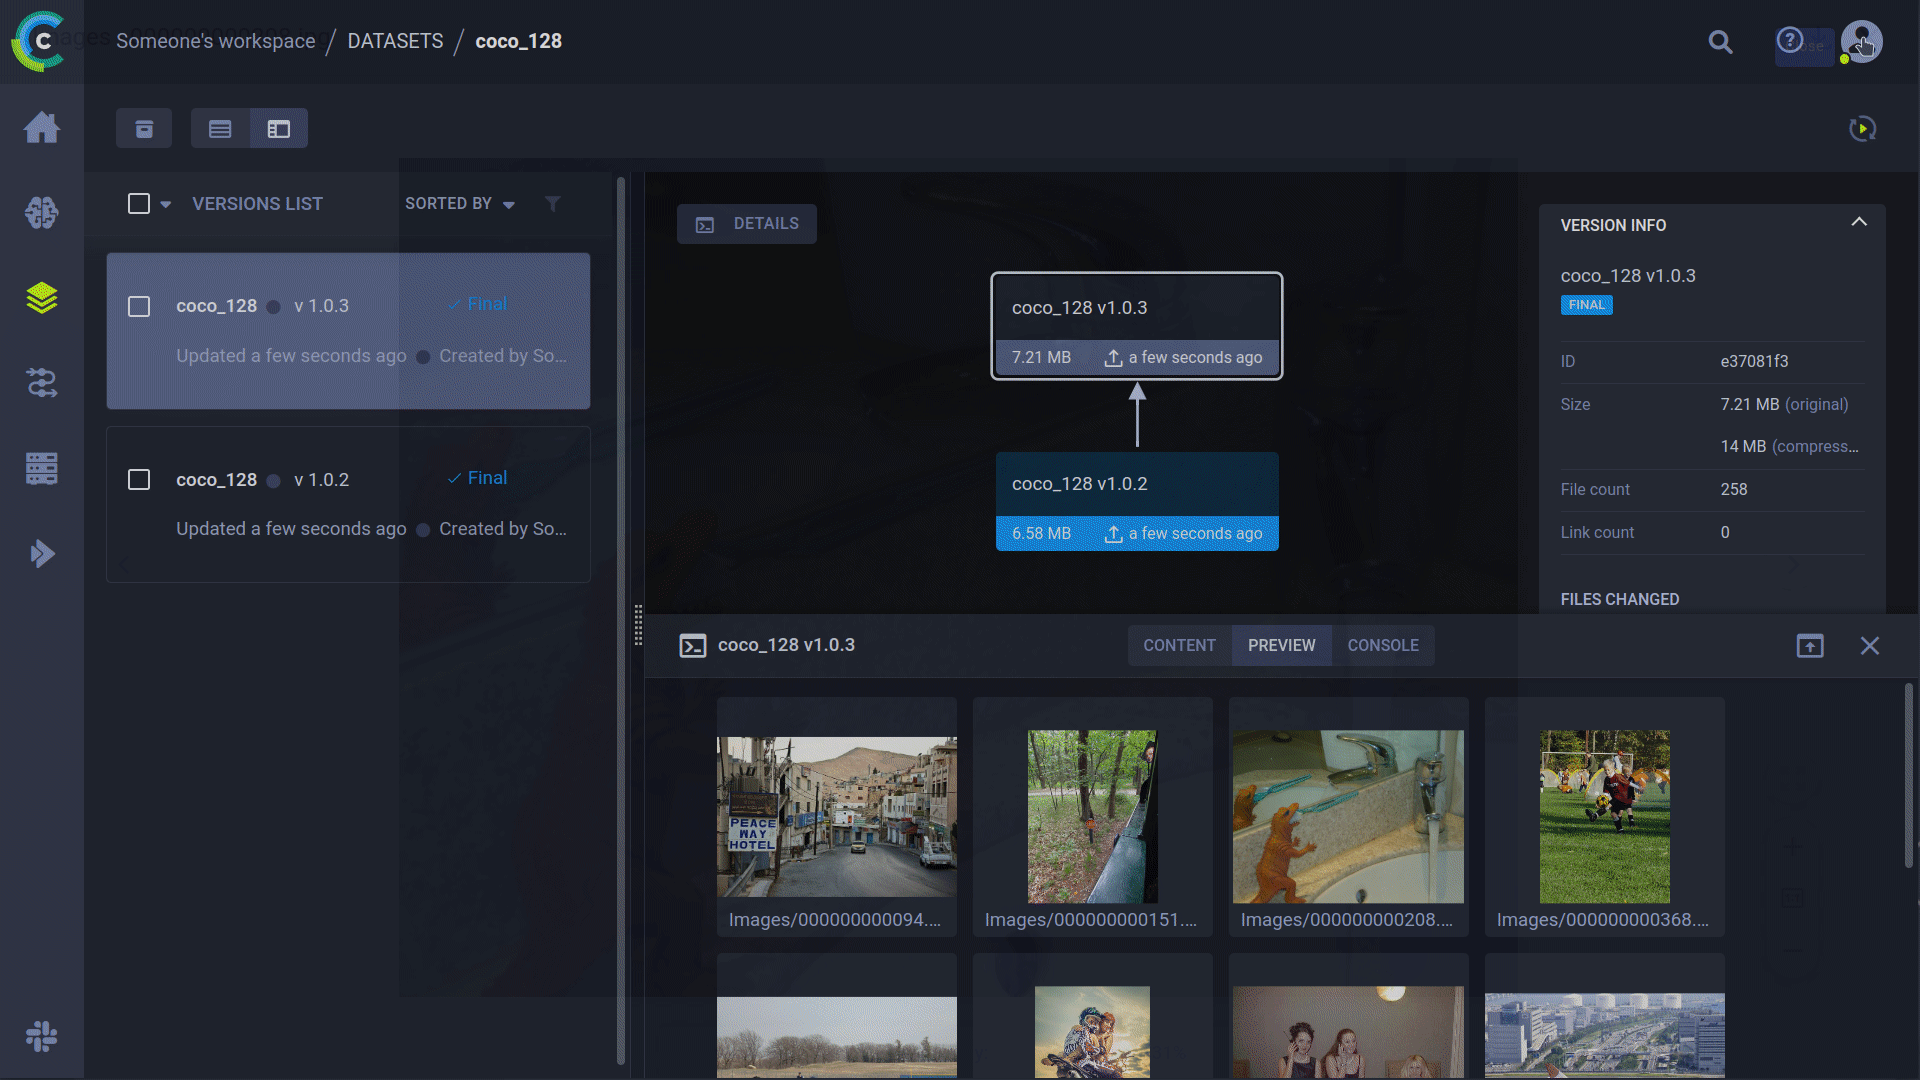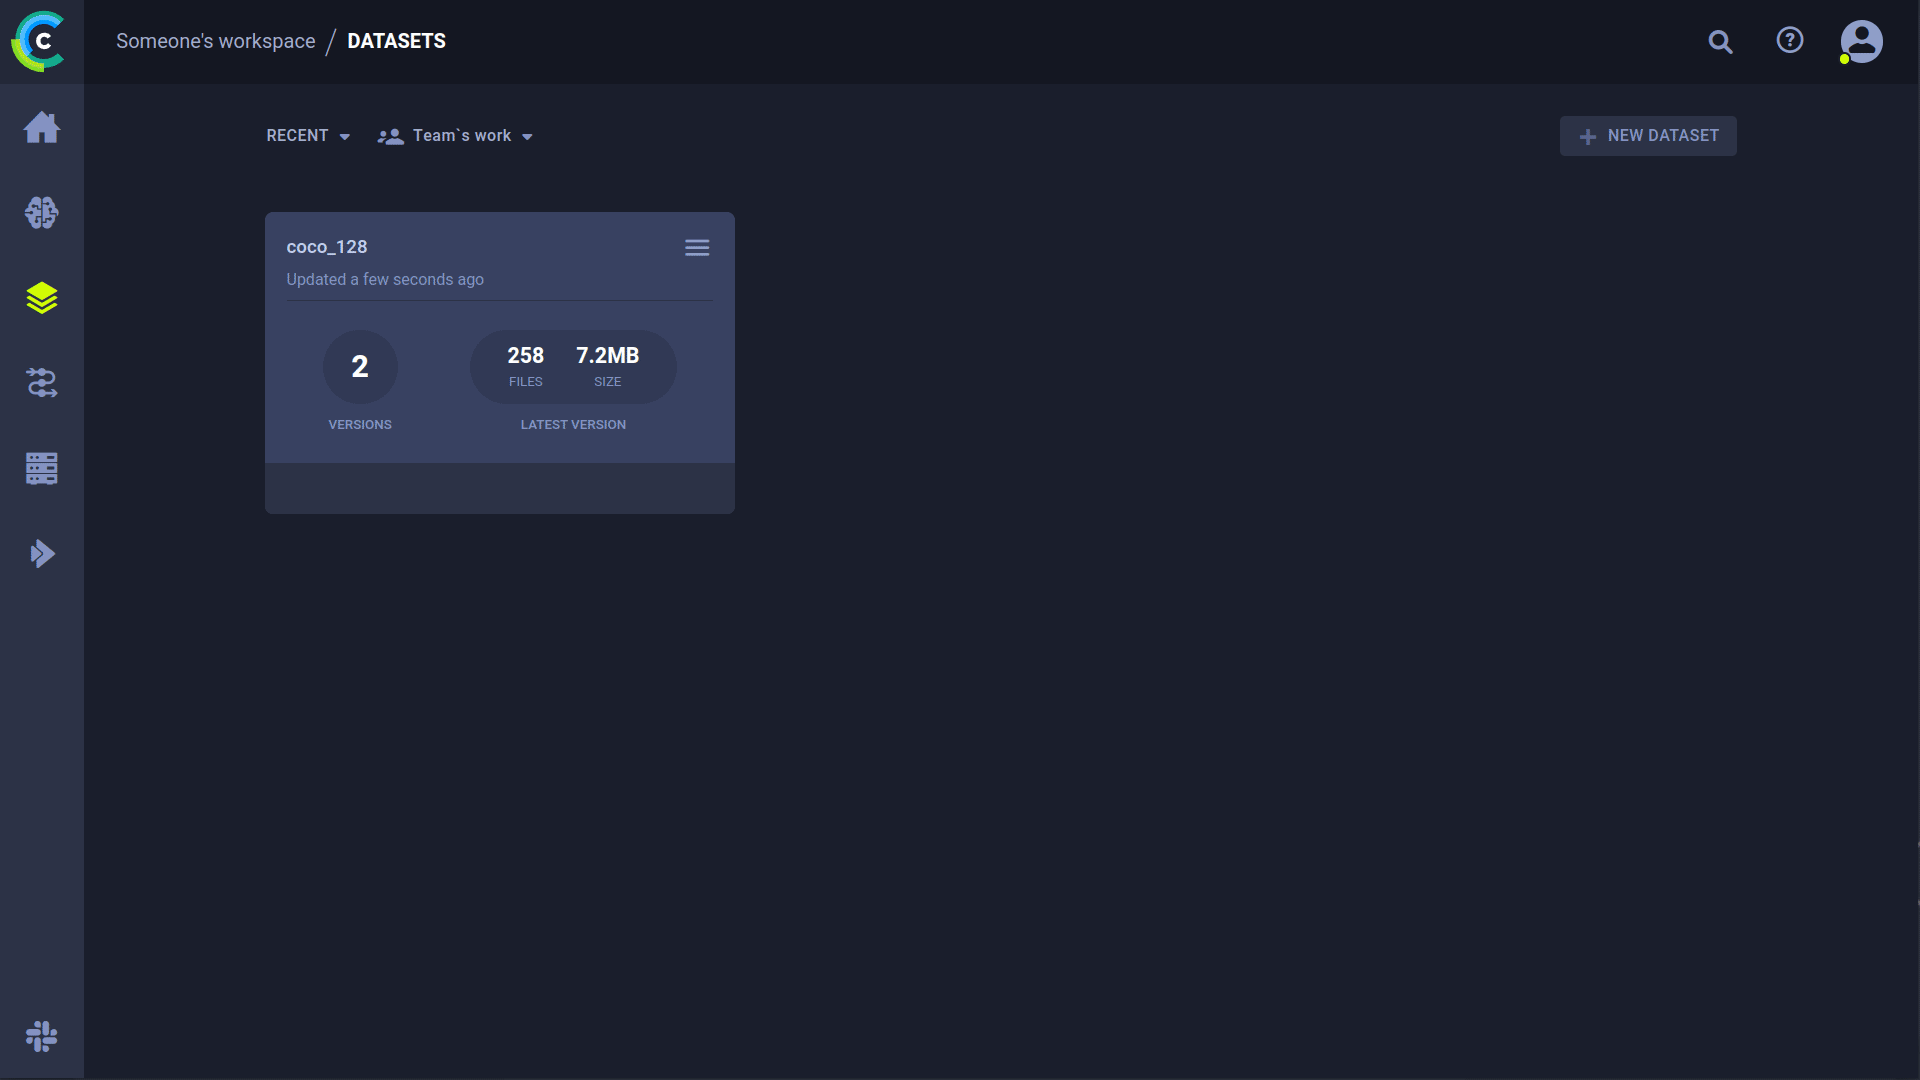
Versioning your data separately from your code is generally a good idea and makes it easy to acquire the latest version too. This repository supports supplying a dataset version ID, and it will make sure to get the data if it's not there yet. Next to that, this workflow also saves the used dataset ID as part of the task parameters, so you will always know for sure which data was used in which experiment!
|
||||
Versioning your [datasets](https://docs.ultralytics.com/datasets/) separately from code is crucial for reproducibility and collaboration. ClearML's Data Versioning Tool helps manage this process. YOLOv5 supports using ClearML dataset version IDs, automatically downloading the data if needed. The dataset ID used is saved as a task parameter, ensuring you always know which data version was used for each experiment.
|
||||
|
||||
|
||||
|
||||
### Prepare Your Dataset
|
||||
|
||||
The YOLOv5 repository supports a number of different datasets by using yaml files containing their information. By default datasets are downloaded to the `../datasets` folder in relation to the repository root folder. So if you downloaded the `coco128` dataset using the link in the yaml or with the scripts provided by yolov5, you get this folder structure:
|
||||
YOLOv5 uses [YAML](https://www.ultralytics.com/glossary/yaml) files to define dataset configurations. By default, datasets are expected in the `../datasets` directory relative to the repository root. For example, the [COCO128 dataset](https://docs.ultralytics.com/datasets/detect/coco128/) structure looks like this:
|
||||
|
||||
```
|
||||
..
|
||||
|_ yolov5
|
||||
|_ datasets
|
||||
|_ coco128
|
||||
|_ images
|
||||
|_ labels
|
||||
|_ LICENSE
|
||||
|_ README.txt
|
||||
../
|
||||
├── yolov5/ # Your YOLOv5 repository clone
|
||||
└── datasets/
|
||||
└── coco128/
|
||||
├── images/
|
||||
├── labels/
|
||||
├── LICENSE
|
||||
└── README.txt
|
||||
```
|
||||
|
||||
But this can be any dataset you wish. Feel free to use your own, as long as you keep to this folder structure.
|
||||
Ensure your custom dataset follows a similar structure.
|
||||
|
||||
Next, ⚠️**copy the corresponding yaml file to the root of the dataset folder**⚠️. This yaml files contains the information ClearML will need to properly use the dataset. You can make this yourself too, of course, just follow the structure of the example yamls.
|
||||
|
||||
Basically we need the following keys: `path`, `train`, `test`, `val`, `nc`, `names`.
|
||||
Next, ⚠️**copy the corresponding dataset `.yaml` file into the root of your dataset folder**⚠️. This file contains essential information (`path`, `train`, `test`, `val`, `nc`, `names`) that ClearML needs.
|
||||
|
||||
```
|
||||
..
|
||||
|_ yolov5
|
||||
|_ datasets
|
||||
|_ coco128
|
||||
|_ images
|
||||
|_ labels
|
||||
|_ coco128.yaml # <---- HERE!
|
||||
|_ LICENSE
|
||||
|_ README.txt
|
||||
../
|
||||
└── datasets/
|
||||
└── coco128/
|
||||
├── images/
|
||||
├── labels/
|
||||
├── coco128.yaml # <---- Place the YAML file here!
|
||||
├── LICENSE
|
||||
└── README.txt
|
||||
```
|
||||
|
||||
### Upload Your Dataset
|
||||
|
||||
To get this dataset into ClearML as a versioned dataset, go to the dataset root folder and run the following command:
|
||||
Navigate to your dataset's root directory in the terminal and use the `clearml-data` CLI tool to upload it:
|
||||
|
||||
```bash
|
||||
cd coco128
|
||||
clearml-data sync --project YOLOv5 --name coco128 --folder .
|
||||
cd ../datasets/coco128
|
||||
clearml-data sync --project YOLOv5_Datasets --name coco128 --folder .
|
||||
```
|
||||
|
||||
The command `clearml-data sync` is actually a shorthand command. You could also run these commands one after the other:
|
||||
Alternatively, you can use the following commands:
|
||||
|
||||
```bash
|
||||
# Optionally add --parent <parent_dataset_id> if you want to base
|
||||
# this version on another dataset version, so no duplicate files are uploaded!
|
||||
clearml-data create --name coco128 --project YOLOv5
|
||||
# Create a new dataset entry in ClearML
|
||||
clearml-data create --project YOLOv5_Datasets --name coco128
|
||||
|
||||
# Add the dataset files (use '.' for the current directory)
|
||||
clearml-data add --files .
|
||||
|
||||
# Finalize and upload the dataset version
|
||||
clearml-data close
|
||||
```
|
||||
|
||||
### Run Training Using A ClearML Dataset
|
||||
_Tip: Use `--parent <parent_dataset_id>` with `clearml-data create` to link versions and avoid re-uploading unchanged files._
|
||||
|
||||
Now that you have a ClearML dataset, you can very simply use it to train custom YOLOv5 🚀 models!
|
||||
### Run Training Using a ClearML Dataset
|
||||
|
||||
Once your dataset is versioned in ClearML, you can easily use it for training by providing the dataset ID via the `--data` argument with the `clearml://` prefix:
|
||||
|
||||
```bash
|
||||
python train.py --img 640 --batch 16 --epochs 3 --data clearml:// yolov5s.pt --cache YOUR_DATASET_ID --weights
|
||||
# Replace YOUR_DATASET_ID with the actual ID from ClearML
|
||||
python train.py --img 640 --batch 16 --epochs 3 --data clearml://YOUR_DATASET_ID --weights yolov5s.pt --cache
|
||||
```
|
||||
|
||||
## 👀 Hyperparameter Optimization
|
||||
|
||||
Now that we have our experiments and data versioned, it's time to take a look at what we can build on top!
|
||||
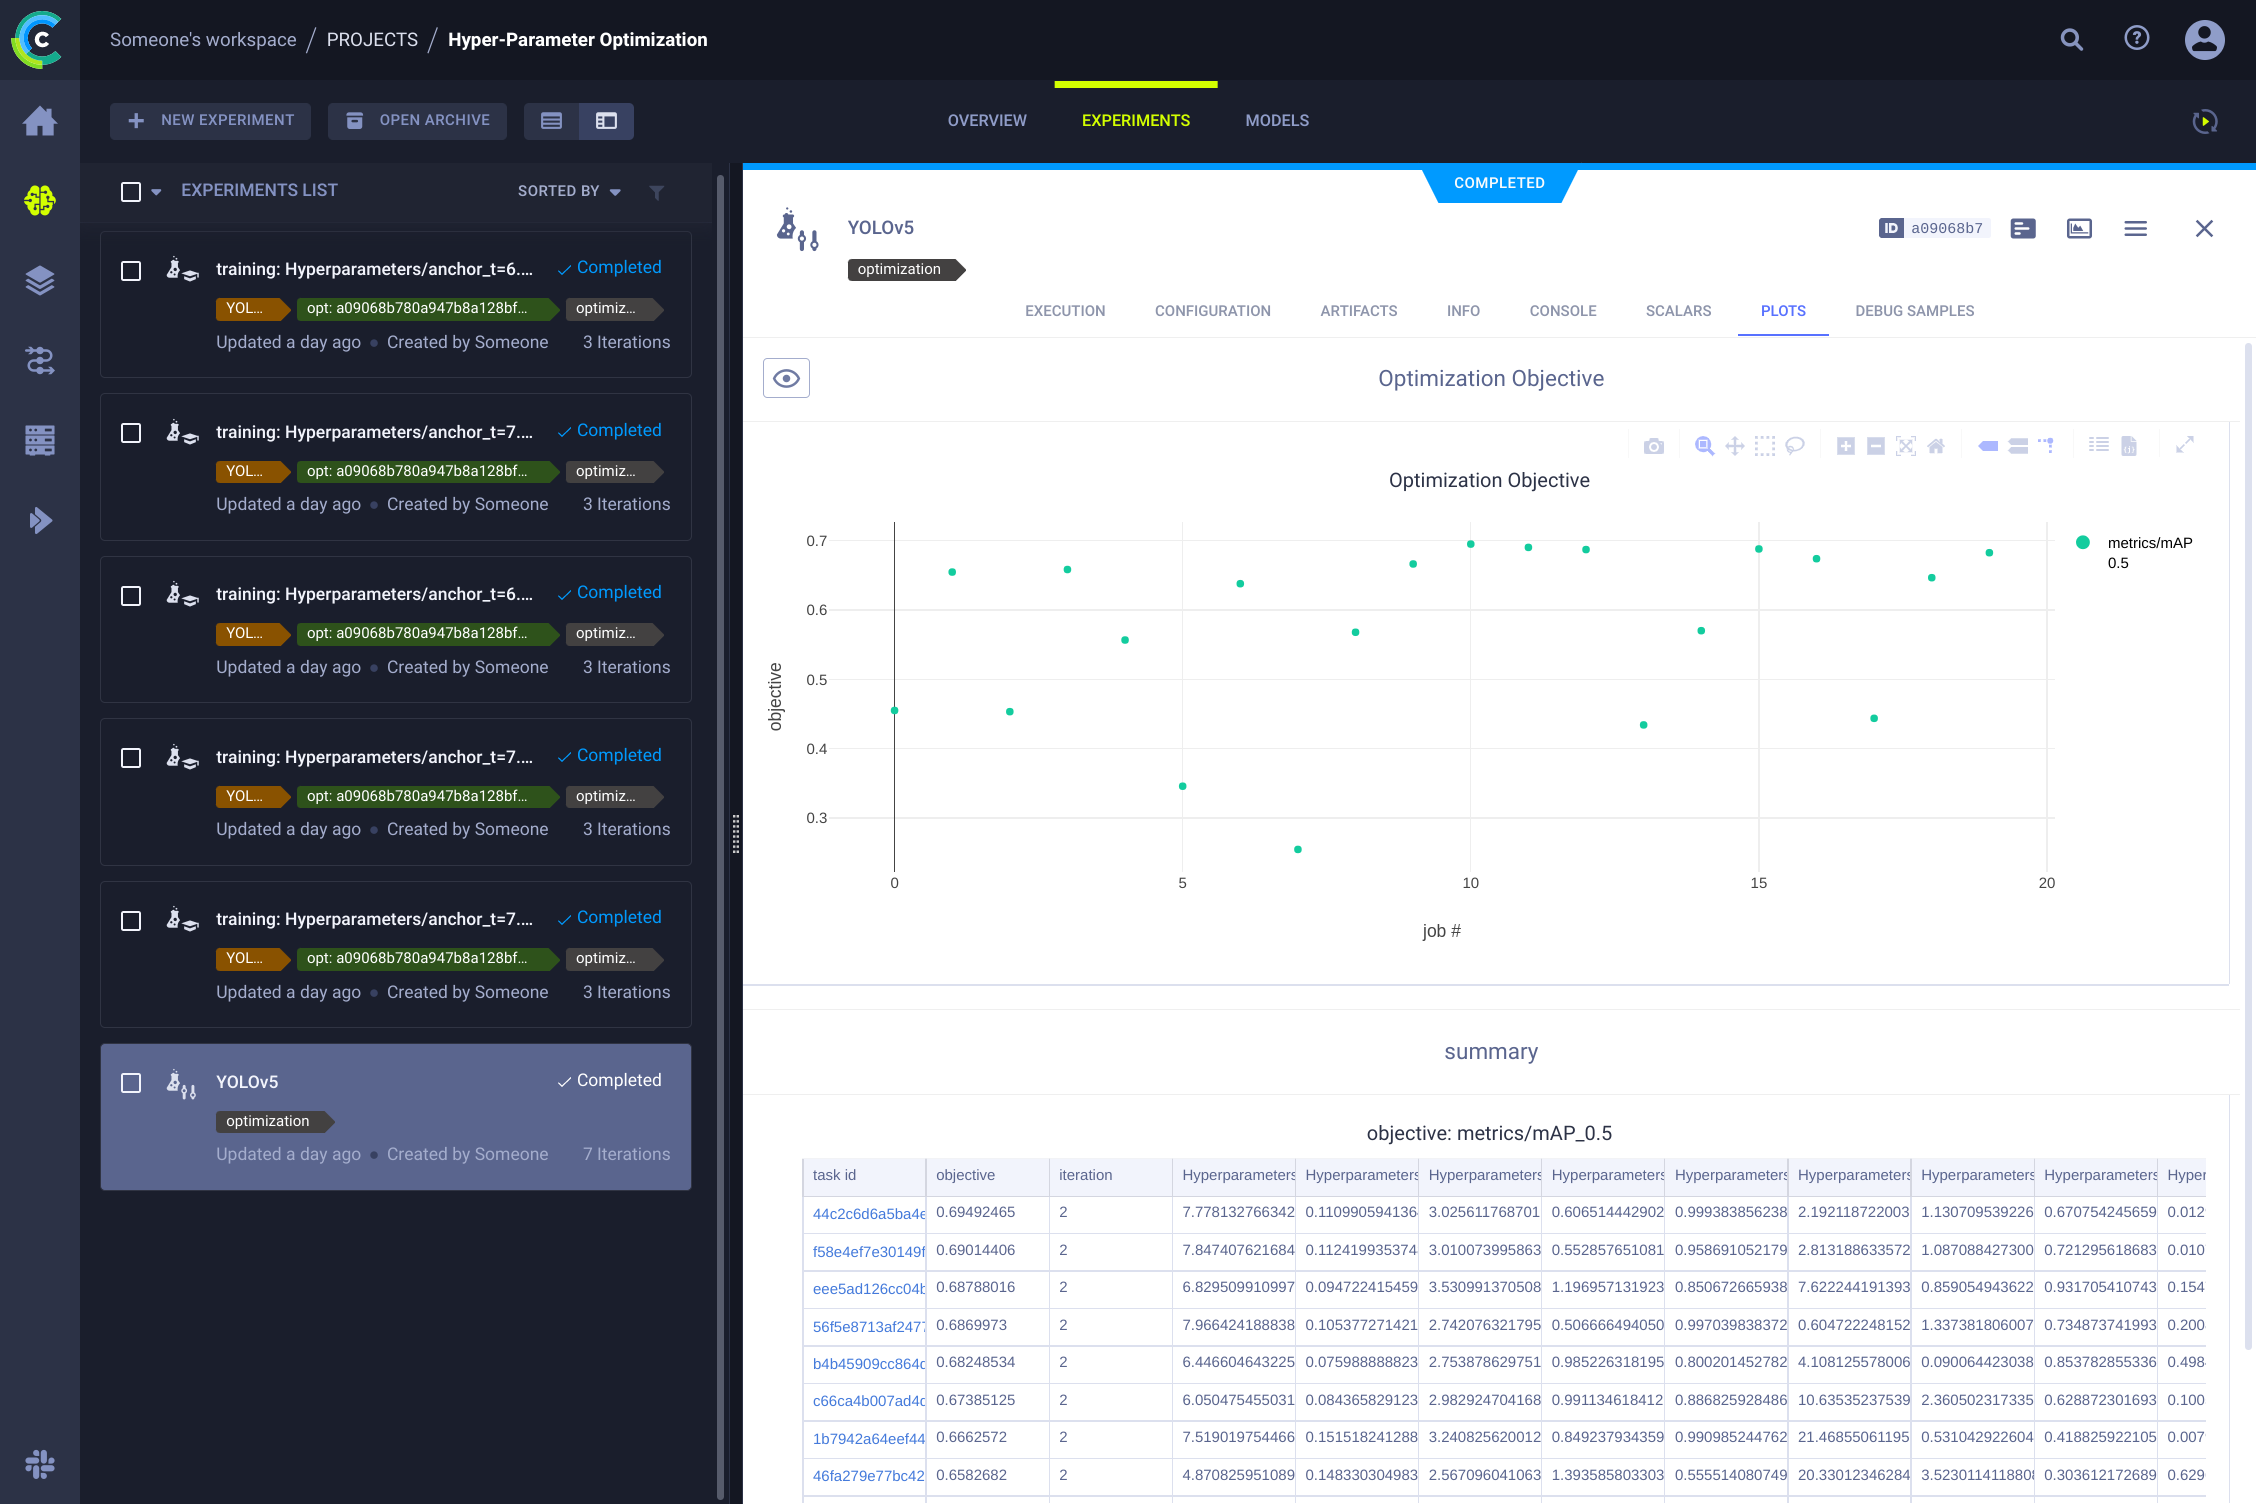
With experiments and data versioned, you can leverage ClearML for [Hyperparameter Optimization (HPO)](https://docs.ultralytics.com/guides/hyperparameter-tuning/). Since ClearML captures all necessary information (code, packages, environment), experiments are fully reproducible. ClearML's HPO tools clone an existing experiment, modify its hyperparameters, and automatically rerun it.
|
||||
|
||||
Using the code information, installed packages and environment details, the experiment itself is now **completely reproducible**. In fact, ClearML allows you to clone an experiment and even change its parameters. We can then just rerun it with these new parameters automatically, this is basically what HPO does!
|
||||
|
||||
To **run hyperparameter optimization locally**, we've included a pre-made script for you. Just make sure a training task has been run at least once, so it is in the ClearML experiment manager, we will essentially clone it and change its hyperparameters.
|
||||
|
||||
You'll need to fill in the ID of this `template task` in the script found at `utils/loggers/clearml/hpo.py` and then just run it :) You can change `task.execute_locally()` to `task.execute()` to put it in a ClearML queue and have a remote agent work on it instead.
|
||||
To run HPO locally, use the provided script `utils/loggers/clearml/hpo.py`. You'll need the ID of a previously run training task (the "template task") to clone. Update the script with this ID and run it.
|
||||
|
||||
```bash
|
||||
# To use optuna, install it first, otherwise you can change the optimizer to just be RandomSearch
|
||||
pip install optuna
|
||||
# Install Optuna for advanced optimization strategies (optional)
|
||||
# pip install optuna
|
||||
|
||||
# Run the HPO script
|
||||
python utils/loggers/clearml/hpo.py
|
||||
```
|
||||
|
||||
|
||||
The script uses [Optuna](https://optuna.org/) by default if installed; otherwise, it falls back to `RandomSearch`. You can modify `task.execute_locally()` to `task.execute()` in the script to enqueue the HPO tasks for a remote ClearML agent.
|
||||
|
||||
## 🤯 Remote Execution (advanced)
|
||||

|
||||
|
||||
Running HPO locally is really handy, but what if we want to run our experiments on a remote machine instead? Maybe you have access to a very powerful GPU machine on-site, or you have some budget to use cloud GPUs. This is where the ClearML Agent comes into play. Check out what the agent can do here:
|
||||
## 🤯 Remote Execution (Advanced)
|
||||
|
||||
- [YouTube video](https://www.youtube.com/watch?v=MX3BrXnaULs&feature=youtu.be)
|
||||
- [Documentation](https://clear.ml/docs/latest/docs/clearml_agent)
|
||||
ClearML Agent allows you to execute experiments on remote machines (e.g., powerful on-site servers, cloud GPUs like [AWS](https://aws.amazon.com/), [GCP](https://cloud.google.com/), or [Azure](https://azure.microsoft.com/)). The agent listens to task queues, reproduces the experiment environment, runs the task, and reports results back to the ClearML server.
|
||||
|
||||
In short: every experiment tracked by the experiment manager contains enough information to reproduce it on a different machine (installed packages, uncommitted changes etc.). So a ClearML agent does just that: it listens to a queue for incoming tasks and when it finds one, it recreates the environment and runs it while still reporting scalars, plots etc. to the experiment manager.
|
||||
Learn more about ClearML Agent:
|
||||
|
||||
You can turn any machine (a cloud VM, a local GPU machine, your own laptop ... ) into a ClearML agent by simply running:
|
||||
- [YouTube Introduction](https://www.youtube.com/watch?v=MX3BrXnaULs)
|
||||
- [Official Documentation](https://clear.ml/docs/latest/docs/clearml_agent)
|
||||
|
||||
Turn any machine into a ClearML agent by running:
|
||||
|
||||
```bash
|
||||
clearml-agent daemon --queue QUEUES_TO_LISTEN_TO [--docker]
|
||||
# Replace QUEUES_TO_LISTEN_TO with the name(s) of your queue(s)
|
||||
clearml-agent daemon --queue QUEUES_TO_LISTEN_TO [--docker] # Use --docker to run in a Docker container
|
||||
```
|
||||
|
||||
### Cloning, Editing And Enqueuing
|
||||
### Cloning, Editing, and Enqueuing Tasks
|
||||
|
||||
With our agent running, we can give it some work. Remember from the HPO section that we can clone a task and edit the hyperparameters? We can do that from the interface too!
|
||||
You can manage remote execution directly from the ClearML web UI:
|
||||
|
||||
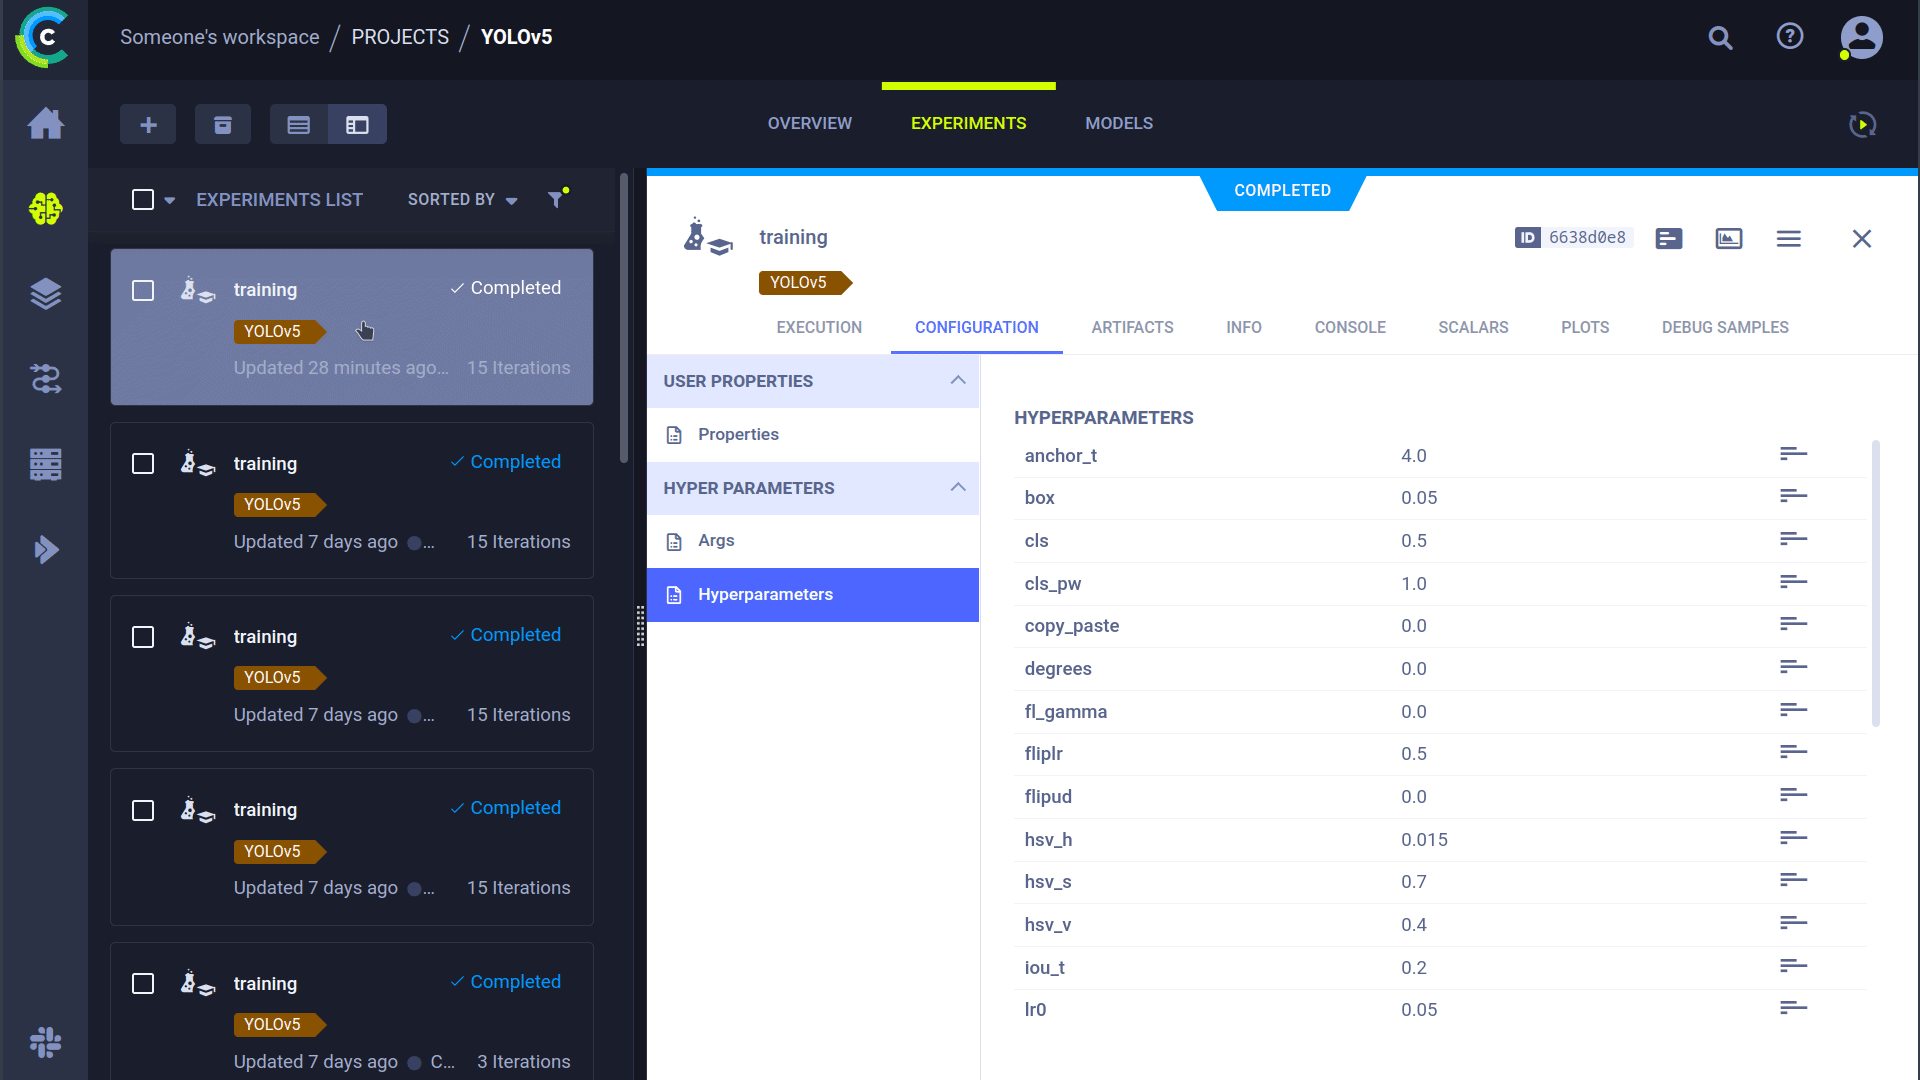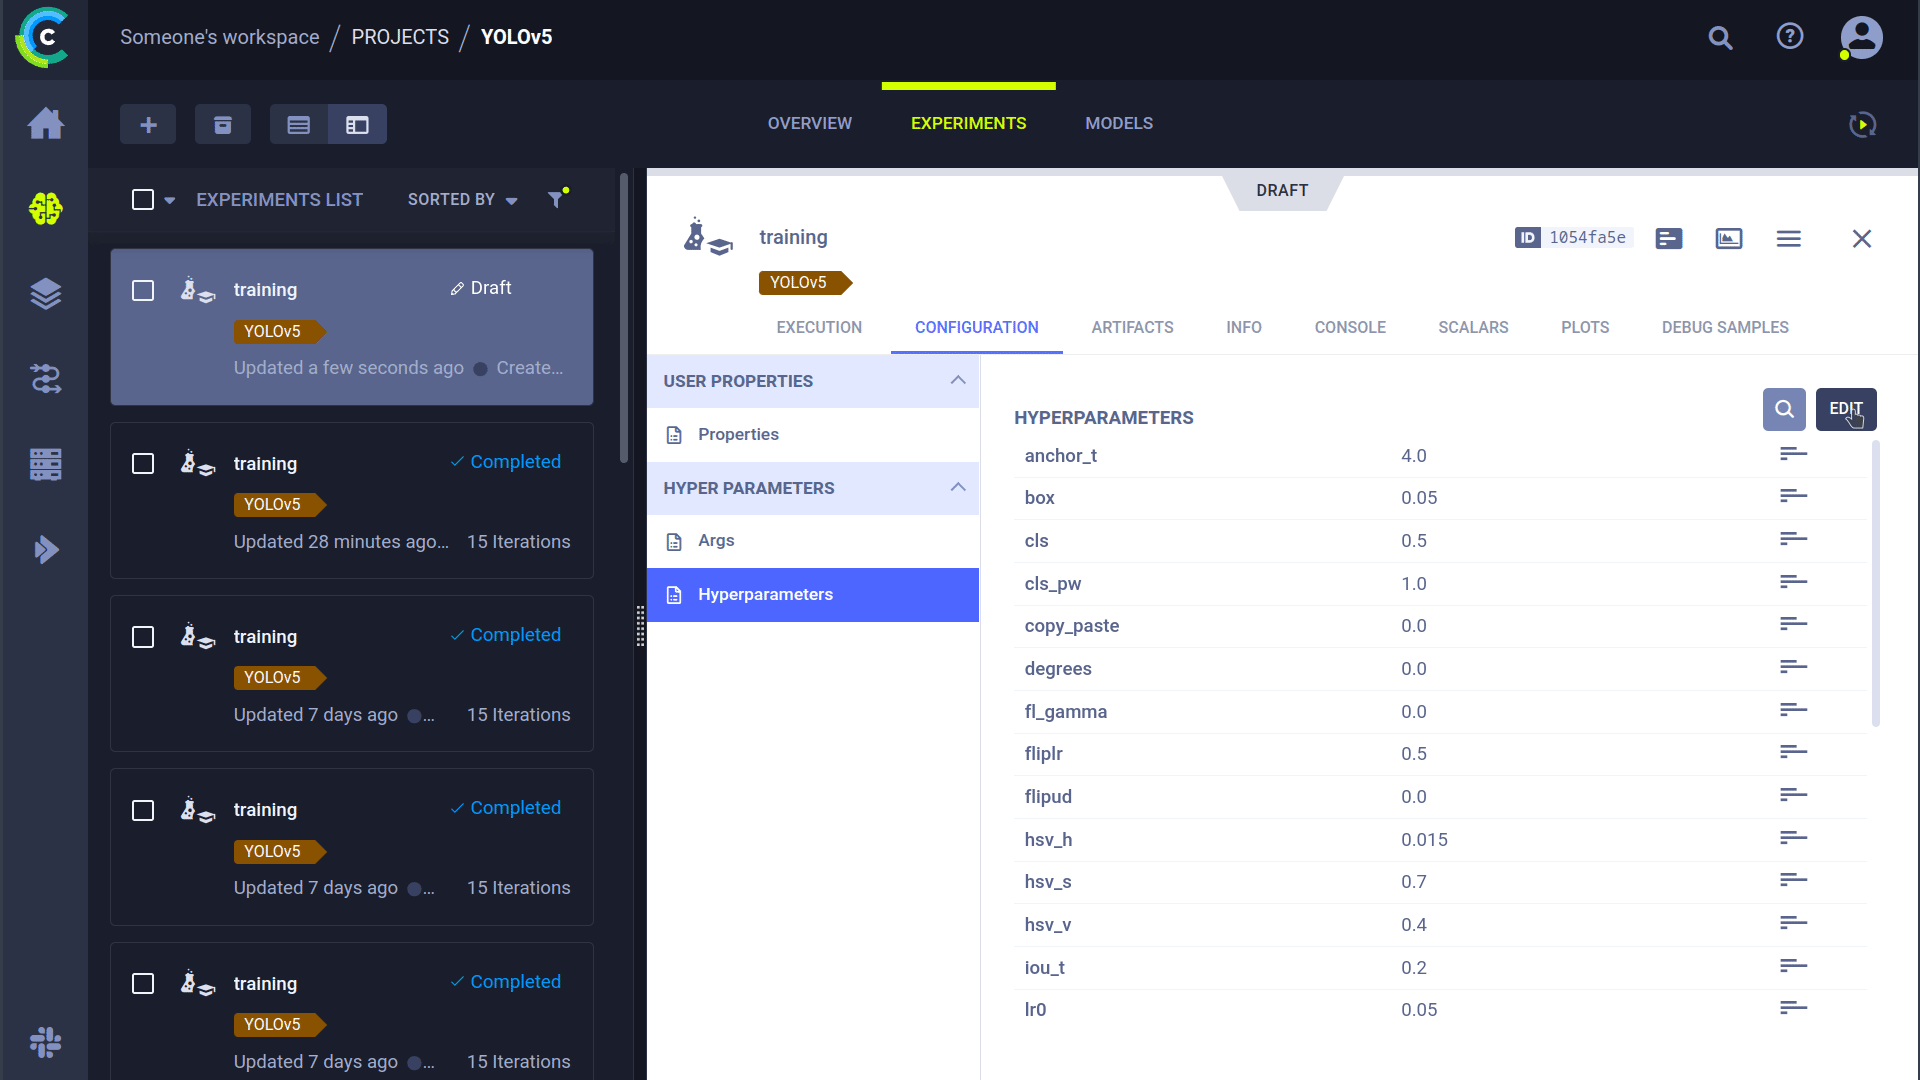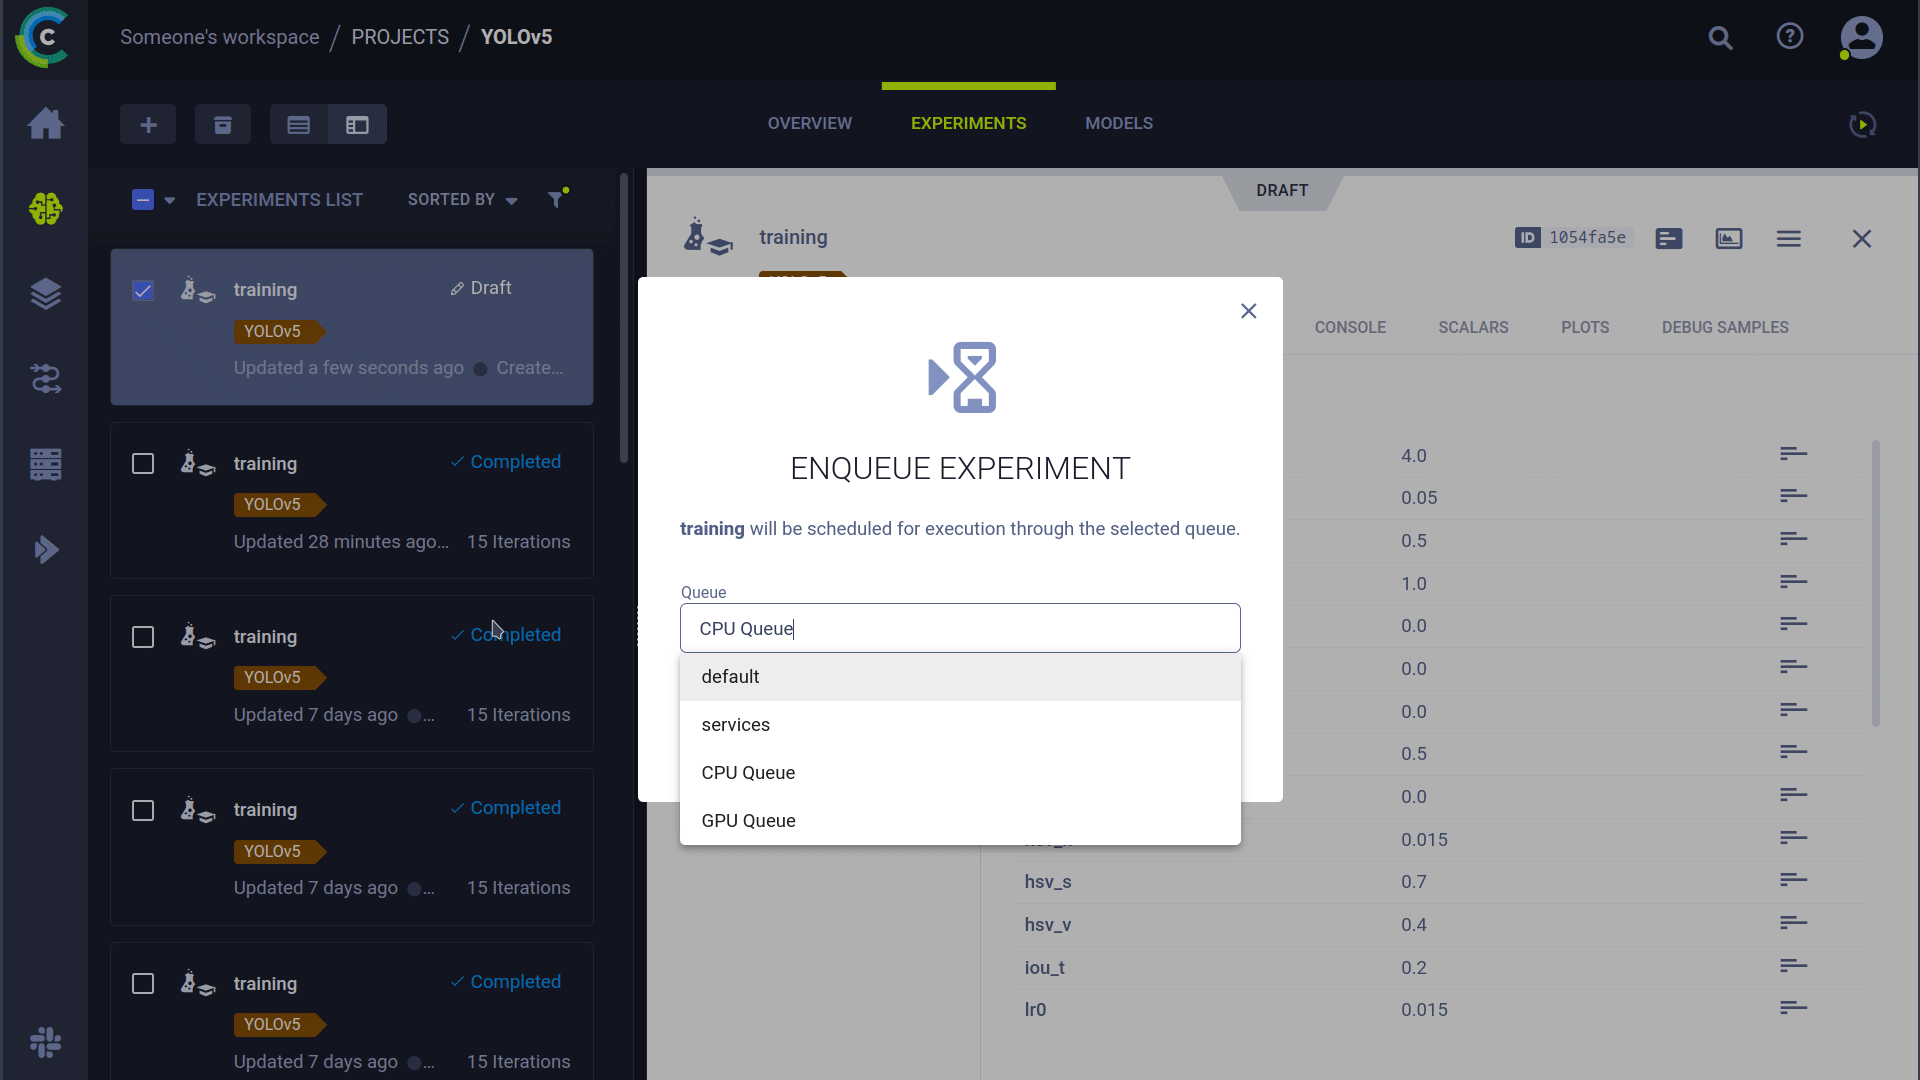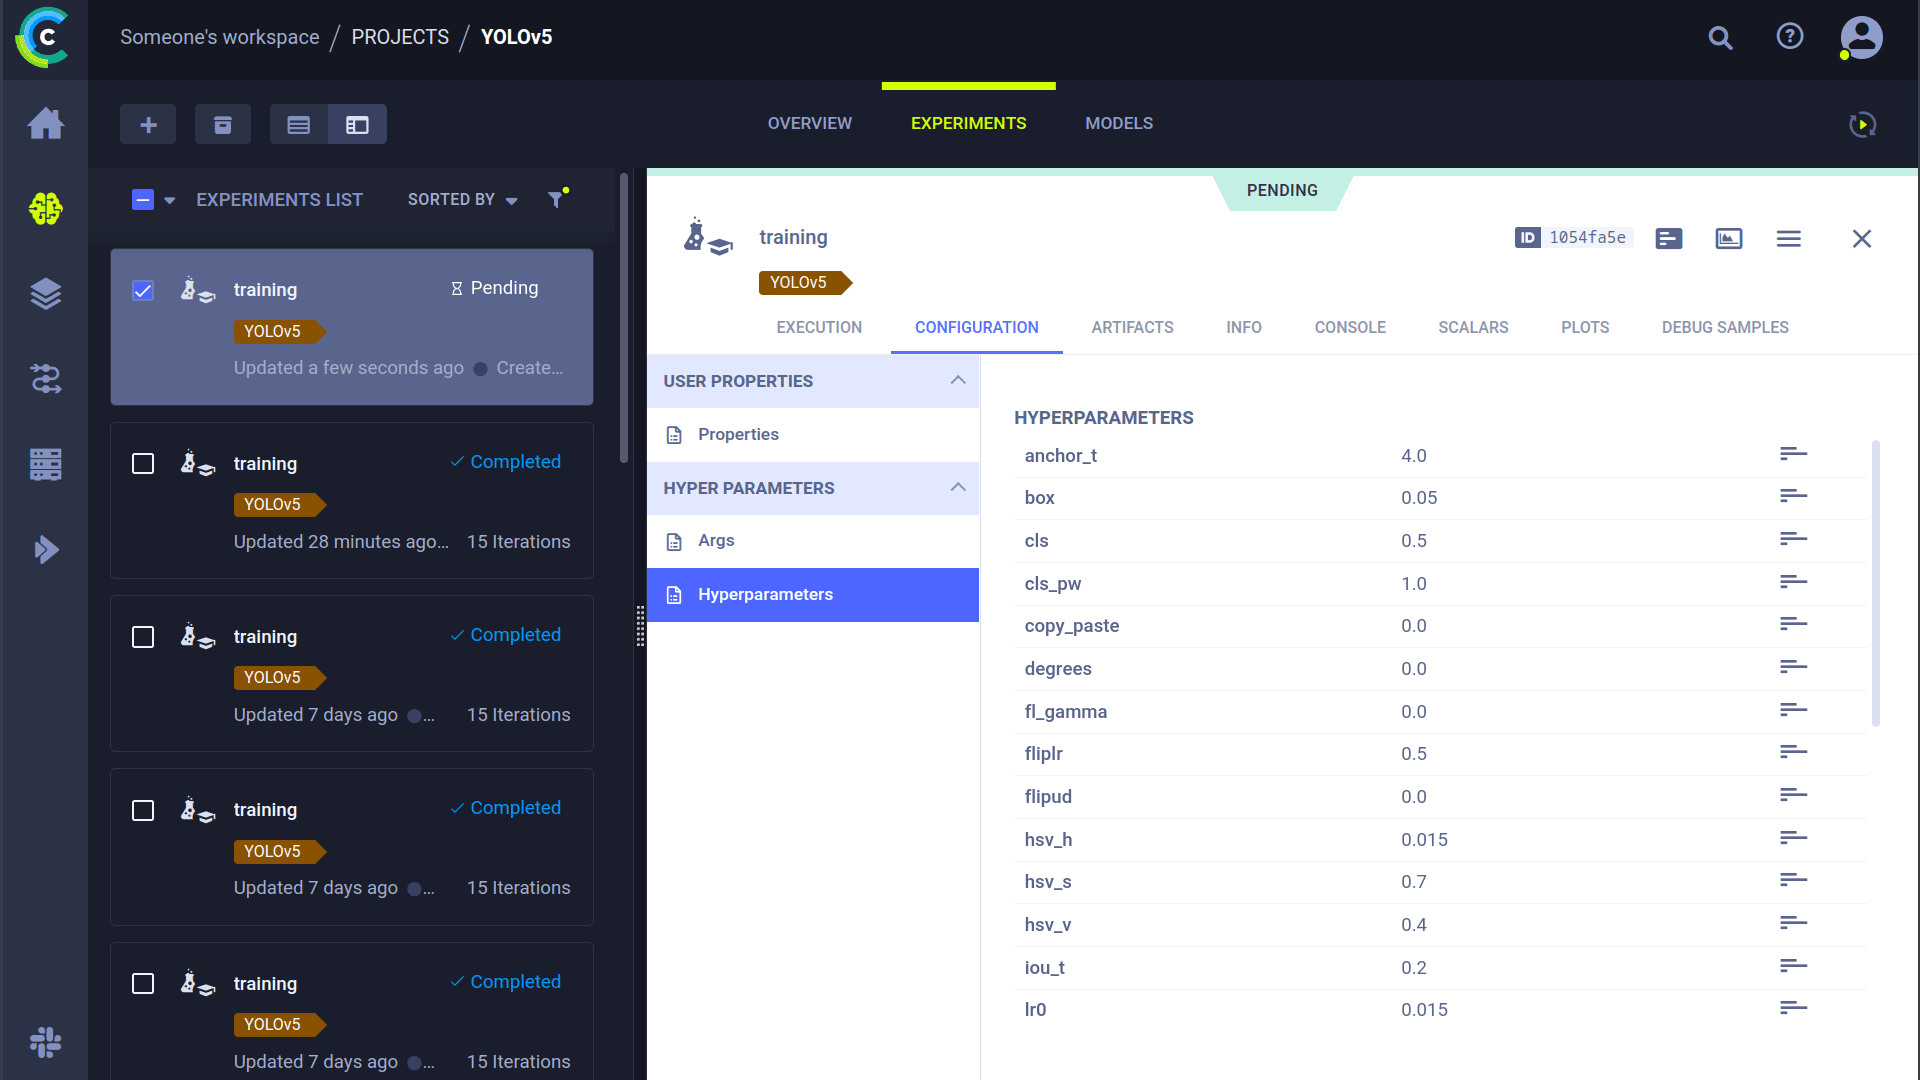
🪄 Clone the experiment by right-clicking it
|
||||
1. **Clone:** Right-click an existing experiment to clone it.
|
||||
2. **Edit:** Modify hyperparameters or other settings as needed in the cloned task.
|
||||
3. **Enqueue:** Right-click the modified task and select "Enqueue" to assign it to a specific queue for an agent to pick up.
|
||||
|
||||
🎯 Edit the hyperparameters to what you wish them to be
|
||||
|
||||
|
||||
⏳ Enqueue the task to any of the queues by right-clicking it
|
||||
### Executing a Task Remotely via Code
|
||||
|
||||

|
||||
|
||||
### Executing A Task Remotely
|
||||
|
||||
Now you can clone a task like we explained above, or simply mark your current script by adding `task.execute_remotely()` and on execution it will be put into a queue, for the agent to start working on!
|
||||
|
||||
To run the YOLOv5 training script remotely, all you have to do is add this line to the training.py script after the clearml logger has been instantiated:
|
||||
Alternatively, you can modify your training script to automatically enqueue tasks for remote execution. Add `task.execute_remotely()` after the ClearML logger is initialized in `train.py`:
|
||||
|
||||
```python
|
||||
# ...
|
||||
# Loggers
|
||||
data_dict = None
|
||||
# Inside train.py, after logger initialization...
|
||||
if RANK in {-1, 0}:
|
||||
loggers = Loggers(save_dir, weights, opt, hyp, LOGGER) # loggers instance
|
||||
# Initialize loggers
|
||||
loggers = Loggers(save_dir, weights, opt, hyp, LOGGER)
|
||||
|
||||
# Check if ClearML logger is active and enqueue the task
|
||||
if loggers.clearml:
|
||||
loggers.clearml.task.execute_remotely(queue="my_queue") # <------ ADD THIS LINE
|
||||
# Data_dict is either None is user did not choose for ClearML dataset or is filled in by ClearML
|
||||
# Specify the queue name for the remote agent
|
||||
loggers.clearml.task.execute_remotely(queue_name="my_remote_queue") # <------ ADD THIS LINE
|
||||
# data_dict might be populated by ClearML if using a ClearML dataset
|
||||
data_dict = loggers.clearml.data_dict
|
||||
# ...
|
||||
```
|
||||
|
||||
When running the training script after this change, python will run the script up until that line, after which it will package the code and send it to the queue instead!
|
||||
Running the script with this modification will package the code and its environment and send it to the specified queue, rather than executing locally.
|
||||
|
||||
### Autoscaling workers
|
||||
### Autoscaling Workers
|
||||
|
||||
ClearML comes with autoscalers too! This tool will automatically spin up new remote machines in the cloud of your choice (AWS, GCP, Azure) and turn them into ClearML agents for you whenever there are experiments detected in the queue. Once the tasks are processed, the autoscaler will automatically shut down the remote machines, and you stop paying!
|
||||
ClearML also provides Autoscalers that automatically manage cloud resources (AWS, GCP, Azure). They spin up new virtual machines and configure them as ClearML agents when tasks appear in a queue, then shut them down when the queue is empty, optimizing cost.
|
||||
|
||||
Check out the autoscalers getting started video below.
|
||||
Watch the Autoscalers getting started video:
|
||||
|
||||
[](https://youtu.be/j4XVMAaUt3E)
|
||||
[](https://youtu.be/j4XVMAaUt3E)
|
||||
|
||||
## 🤝 Contributing
|
||||
|
||||
Contributions to enhance the ClearML integration are welcome! Please see the [Ultralytics Contributing Guide](https://docs.ultralytics.com/help/contributing/) for more information on how to get involved.
|
||||
Reference in new issue
Block a user