Update Dockerfile FROM pytorch/pytorch:latest (#10902)
* Update Dockerfile `FROM pytorch/pytorch:latest`

Signed-off-by: Glenn Jocher <glenn.jocher@ultralytics.com>

* isort

* precommit

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* spelling

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* Update .pre-commit-config.yaml

Signed-off-by: Glenn Jocher <glenn.jocher@ultralytics.com>

* Cleanup

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* Cleanup

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* Cleanup

* Cleanup

* Cleanup

* Cleanup

---------

Signed-off-by: Glenn Jocher <glenn.jocher@ultralytics.com>
Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com>
This commit is contained in:
 Glenn Jocherandpre-commit-ci[bot] authored and GitHub committed
1 parent
d02ee60512
commit
b8a2c47fa9
14 files changed
+250
-980
No files matched your search
@@ -84,10 +84,6 @@ class Loggers():
|
||||
self.csv = True # always log to csv
|
||||
|
||||
# Messages
|
||||
# if not wandb:
|
||||
# prefix = colorstr('Weights & Biases: ')
|
||||
# s = f"{prefix}run 'pip install wandb' to automatically track and visualize YOLOv5 🚀 runs in Weights & Biases"
|
||||
# self.logger.info(s)
|
||||
if not clearml:
|
||||
prefix = colorstr('ClearML: ')
|
||||
s = f"{prefix}run 'pip install clearml' to automatically track, visualize and remotely train YOLOv5 🚀 in ClearML"
|
||||
@@ -105,14 +101,8 @@ class Loggers():
|
||||
|
||||
# W&B
|
||||
if wandb and 'wandb' in self.include:
|
||||
wandb_artifact_resume = isinstance(self.opt.resume, str) and self.opt.resume.startswith('wandb-artifact://')
|
||||
run_id = torch.load(self.weights).get('wandb_id') if self.opt.resume and not wandb_artifact_resume else None
|
||||
self.opt.hyp = self.hyp # add hyperparameters
|
||||
self.wandb = WandbLogger(self.opt, run_id)
|
||||
# temp warn. because nested artifacts not supported after 0.12.10
|
||||
# if pkg.parse_version(wandb.__version__) >= pkg.parse_version('0.12.11'):
|
||||
# s = "YOLOv5 temporarily requires wandb version 0.12.10 or below. Some features may not work as expected."
|
||||
# self.logger.warning(s)
|
||||
self.wandb = WandbLogger(self.opt)
|
||||
else:
|
||||
self.wandb = None
|
||||
|
||||
@@ -175,7 +165,7 @@ class Loggers():
|
||||
self.comet_logger.on_pretrain_routine_end(paths)
|
||||
|
||||
def on_train_batch_end(self, model, ni, imgs, targets, paths, vals):
|
||||
log_dict = dict(zip(self.keys[0:3], vals))
|
||||
log_dict = dict(zip(self.keys[:3], vals))
|
||||
# Callback runs on train batch end
|
||||
# ni: number integrated batches (since train start)
|
||||
if self.plots:
|
||||
@@ -221,10 +211,10 @@ class Loggers():
|
||||
# Callback runs on val end
|
||||
if self.wandb or self.clearml:
|
||||
files = sorted(self.save_dir.glob('val*.jpg'))
|
||||
if self.wandb:
|
||||
self.wandb.log({"Validation": [wandb.Image(str(f), caption=f.name) for f in files]})
|
||||
if self.clearml:
|
||||
self.clearml.log_debug_samples(files, title='Validation')
|
||||
if self.wandb:
|
||||
self.wandb.log({"Validation": [wandb.Image(str(f), caption=f.name) for f in files]})
|
||||
if self.clearml:
|
||||
self.clearml.log_debug_samples(files, title='Validation')
|
||||
|
||||
if self.comet_logger:
|
||||
self.comet_logger.on_val_end(nt, tp, fp, p, r, f1, ap, ap50, ap_class, confusion_matrix)
|
||||
@@ -253,7 +243,7 @@ class Loggers():
|
||||
for i, name in enumerate(self.best_keys):
|
||||
self.wandb.wandb_run.summary[name] = best_results[i] # log best results in the summary
|
||||
self.wandb.log(x)
|
||||
self.wandb.end_epoch(best_result=best_fitness == fi)
|
||||
self.wandb.end_epoch()
|
||||
|
||||
if self.clearml:
|
||||
self.clearml.current_epoch_logged_images = set() # reset epoch image limit
|
||||
|
||||
@@ -23,7 +23,6 @@ And so much more. It's up to you how many of these tools you want to use, you ca
|
||||
|
||||

|
||||
|
||||
|
||||
<br />
|
||||
<br />
|
||||
|
||||
@@ -35,15 +34,15 @@ Either sign up for free to the [ClearML Hosted Service](https://cutt.ly/yolov5-t
|
||||
|
||||
1. Install the `clearml` python package:
|
||||
|
||||
```bash
|
||||
pip install clearml
|
||||
```
|
||||
```bash
|
||||
pip install clearml
|
||||
```
|
||||
|
||||
1. Connect the ClearML SDK to the server by [creating credentials](https://app.clear.ml/settings/workspace-configuration) (go right top to Settings -> Workspace -> Create new credentials), then execute the command below and follow the instructions:
|
||||
|
||||
```bash
|
||||
clearml-init
|
||||
```
|
||||
```bash
|
||||
clearml-init
|
||||
```
|
||||
|
||||
That's it! You're done 😎
|
||||
|
||||
@@ -60,18 +59,20 @@ pip install clearml>=1.2.0
|
||||
This will enable integration with the YOLOv5 training script. Every training run from now on, will be captured and stored by the ClearML experiment manager.
|
||||
|
||||
If you want to change the `project_name` or `task_name`, use the `--project` and `--name` arguments of the `train.py` script, by default the project will be called `YOLOv5` and the task `Training`.
|
||||
PLEASE NOTE: ClearML uses `/` as a delimter for subprojects, so be careful when using `/` in your project name!
|
||||
PLEASE NOTE: ClearML uses `/` as a delimiter for subprojects, so be careful when using `/` in your project name!
|
||||
|
||||
```bash
|
||||
python train.py --img 640 --batch 16 --epochs 3 --data coco128.yaml --weights yolov5s.pt --cache
|
||||
```
|
||||
|
||||
or with custom project and task name:
|
||||
|
||||
```bash
|
||||
python train.py --project my_project --name my_training --img 640 --batch 16 --epochs 3 --data coco128.yaml --weights yolov5s.pt --cache
|
||||
```
|
||||
|
||||
This will capture:
|
||||
|
||||
- Source code + uncommitted changes
|
||||
- Installed packages
|
||||
- (Hyper)parameters
|
||||
@@ -94,7 +95,7 @@ There even more we can do with all of this information, like hyperparameter opti
|
||||
|
||||
## 🔗 Dataset Version Management
|
||||
|
||||
Versioning your data separately from your code is generally a good idea and makes it easy to aqcuire the latest version too. This repository supports supplying a dataset version ID and it will make sure to get the data if it's not there yet. Next to that, this workflow also saves the used dataset ID as part of the task parameters, so you will always know for sure which data was used in which experiment!
|
||||
Versioning your data separately from your code is generally a good idea and makes it easy to acquire the latest version too. This repository supports supplying a dataset version ID, and it will make sure to get the data if it's not there yet. Next to that, this workflow also saves the used dataset ID as part of the task parameters, so you will always know for sure which data was used in which experiment!
|
||||
|
||||

|
||||
|
||||
@@ -112,6 +113,7 @@ The YOLOv5 repository supports a number of different datasets by using yaml file
|
||||
|_ LICENSE
|
||||
|_ README.txt
|
||||
```
|
||||
|
||||
But this can be any dataset you wish. Feel free to use your own, as long as you keep to this folder structure.
|
||||
|
||||
Next, ⚠️**copy the corresponding yaml file to the root of the dataset folder**⚠️. This yaml files contains the information ClearML will need to properly use the dataset. You can make this yourself too, of course, just follow the structure of the example yamls.
|
||||
@@ -132,13 +134,15 @@ Basically we need the following keys: `path`, `train`, `test`, `val`, `nc`, `nam
|
||||
|
||||
### Upload Your Dataset
|
||||
|
||||
To get this dataset into ClearML as a versionned dataset, go to the dataset root folder and run the following command:
|
||||
To get this dataset into ClearML as a versioned dataset, go to the dataset root folder and run the following command:
|
||||
|
||||
```bash
|
||||
cd coco128
|
||||
clearml-data sync --project YOLOv5 --name coco128 --folder .
|
||||
```
|
||||
|
||||
The command `clearml-data sync` is actually a shorthand command. You could also run these commands one after the other:
|
||||
|
||||
```bash
|
||||
# Optionally add --parent <parent_dataset_id> if you want to base
|
||||
# this version on another dataset version, so no duplicate files are uploaded!
|
||||
@@ -177,7 +181,7 @@ python utils/loggers/clearml/hpo.py
|
||||
|
||||
## 🤯 Remote Execution (advanced)
|
||||
|
||||
Running HPO locally is really handy, but what if we want to run our experiments on a remote machine instead? Maybe you have access to a very powerful GPU machine on-site or you have some budget to use cloud GPUs.
|
||||
Running HPO locally is really handy, but what if we want to run our experiments on a remote machine instead? Maybe you have access to a very powerful GPU machine on-site, or you have some budget to use cloud GPUs.
|
||||
This is where the ClearML Agent comes into play. Check out what the agent can do here:
|
||||
|
||||
- [YouTube video](https://youtu.be/MX3BrXnaULs)
|
||||
@@ -186,6 +190,7 @@ This is where the ClearML Agent comes into play. Check out what the agent can do
|
||||
In short: every experiment tracked by the experiment manager contains enough information to reproduce it on a different machine (installed packages, uncommitted changes etc.). So a ClearML agent does just that: it listens to a queue for incoming tasks and when it finds one, it recreates the environment and runs it while still reporting scalars, plots etc. to the experiment manager.
|
||||
|
||||
You can turn any machine (a cloud VM, a local GPU machine, your own laptop ... ) into a ClearML agent by simply running:
|
||||
|
||||
```bash
|
||||
clearml-agent daemon --queue <queues_to_listen_to> [--docker]
|
||||
```
|
||||
@@ -194,11 +199,11 @@ clearml-agent daemon --queue <queues_to_listen_to> [--docker]
|
||||
|
||||
With our agent running, we can give it some work. Remember from the HPO section that we can clone a task and edit the hyperparameters? We can do that from the interface too!
|
||||
|
||||
🪄 Clone the experiment by right clicking it
|
||||
🪄 Clone the experiment by right-clicking it
|
||||
|
||||
🎯 Edit the hyperparameters to what you wish them to be
|
||||
|
||||
⏳ Enqueue the task to any of the queues by right clicking it
|
||||
⏳ Enqueue the task to any of the queues by right-clicking it
|
||||
|
||||

|
||||
|
||||
@@ -206,7 +211,8 @@ With our agent running, we can give it some work. Remember from the HPO section
|
||||
|
||||
Now you can clone a task like we explained above, or simply mark your current script by adding `task.execute_remotely()` and on execution it will be put into a queue, for the agent to start working on!
|
||||
|
||||
To run the YOLOv5 training script remotely, all you have to do is add this line to the training.py script after the clearml logger has been instatiated:
|
||||
To run the YOLOv5 training script remotely, all you have to do is add this line to the training.py script after the clearml logger has been instantiated:
|
||||
|
||||
```python
|
||||
# ...
|
||||
# Loggers
|
||||
@@ -214,16 +220,17 @@ data_dict = None
|
||||
if RANK in {-1, 0}:
|
||||
loggers = Loggers(save_dir, weights, opt, hyp, LOGGER) # loggers instance
|
||||
if loggers.clearml:
|
||||
loggers.clearml.task.execute_remotely(queue='my_queue') # <------ ADD THIS LINE
|
||||
loggers.clearml.task.execute_remotely(queue="my_queue") # <------ ADD THIS LINE
|
||||
# Data_dict is either None is user did not choose for ClearML dataset or is filled in by ClearML
|
||||
data_dict = loggers.clearml.data_dict
|
||||
# ...
|
||||
```
|
||||
|
||||
When running the training script after this change, python will run the script up until that line, after which it will package the code and send it to the queue instead!
|
||||
|
||||
### Autoscaling workers
|
||||
|
||||
ClearML comes with autoscalers too! This tool will automatically spin up new remote machines in the cloud of your choice (AWS, GCP, Azure) and turn them into ClearML agents for you whenever there are experiments detected in the queue. Once the tasks are processed, the autoscaler will automatically shut down the remote machines and you stop paying!
|
||||
ClearML comes with autoscalers too! This tool will automatically spin up new remote machines in the cloud of your choice (AWS, GCP, Azure) and turn them into ClearML agents for you whenever there are experiments detected in the queue. Once the tasks are processed, the autoscaler will automatically shut down the remote machines, and you stop paying!
|
||||
|
||||
Check out the autoscalers getting started video below.
|
||||
|
||||
|
||||
@@ -23,7 +23,7 @@ pip install comet_ml
|
||||
|
||||
There are two ways to configure Comet with YOLOv5.
|
||||
|
||||
You can either set your credentials through enviroment variables
|
||||
You can either set your credentials through environment variables
|
||||
|
||||
**Environment Variables**
|
||||
|
||||
@@ -49,11 +49,12 @@ project_name=<Your Comet Project Name> # This will default to 'yolov5'
|
||||
python train.py --img 640 --batch 16 --epochs 5 --data coco128.yaml --weights yolov5s.pt
|
||||
```
|
||||
|
||||
That's it! Comet will automatically log your hyperparameters, command line arguments, training and valiation metrics. You can visualize and analyze your runs in the Comet UI
|
||||
That's it! Comet will automatically log your hyperparameters, command line arguments, training and validation metrics. You can visualize and analyze your runs in the Comet UI
|
||||
|
||||
<img width="1920" alt="yolo-ui" src="https://user-images.githubusercontent.com/26833433/202851203-164e94e1-2238-46dd-91f8-de020e9d6b41.png">
|
||||
|
||||
# Try out an Example!
|
||||
|
||||
Check out an example of a [completed run here](https://www.comet.com/examples/comet-example-yolov5/a0e29e0e9b984e4a822db2a62d0cb357?experiment-tab=chart&showOutliers=true&smoothing=0&transformY=smoothing&xAxis=step&utm_source=yolov5&utm_medium=partner&utm_campaign=partner_yolov5_2022&utm_content=github)
|
||||
|
||||
Or better yet, try it out yourself in this Colab Notebook
|
||||
@@ -65,6 +66,7 @@ Or better yet, try it out yourself in this Colab Notebook
|
||||
By default, Comet will log the following items
|
||||
|
||||
## Metrics
|
||||
|
||||
- Box Loss, Object Loss, Classification Loss for the training and validation data
|
||||
- mAP_0.5, mAP_0.5:0.95 metrics for the validation data.
|
||||
- Precision and Recall for the validation data
|
||||
@@ -121,7 +123,6 @@ You can control the frequency of logged predictions and the associated images by
|
||||
|
||||
Here is an [example project using the Panel](https://www.comet.com/examples/comet-example-yolov5?shareable=YcwMiJaZSXfcEXpGOHDD12vA1&utm_source=yolov5&utm_medium=partner&utm_campaign=partner_yolov5_2022&utm_content=github)
|
||||
|
||||
|
||||
```shell
|
||||
python train.py \
|
||||
--img 640 \
|
||||
@@ -192,6 +193,7 @@ If you would like to use a dataset from Comet Artifacts, set the `path` variable
|
||||
# contents of artifact.yaml file
|
||||
path: "comet://<workspace name>/<artifact name>:<artifact version or alias>"
|
||||
```
|
||||
|
||||
Then pass this file to your training script in the following way
|
||||
|
||||
```shell
|
||||
@@ -221,7 +223,7 @@ python train.py \
|
||||
|
||||
## Hyperparameter Search with the Comet Optimizer
|
||||
|
||||
YOLOv5 is also integrated with Comet's Optimizer, making is simple to visualie hyperparameter sweeps in the Comet UI.
|
||||
YOLOv5 is also integrated with Comet's Optimizer, making is simple to visualize hyperparameter sweeps in the Comet UI.
|
||||
|
||||
### Configuring an Optimizer Sweep
|
||||
|
||||
|
||||
@@ -1,162 +0,0 @@
|
||||
📚 This guide explains how to use **Weights & Biases** (W&B) with YOLOv5 🚀. UPDATED 29 September 2021.
|
||||
|
||||
- [About Weights & Biases](#about-weights-&-biases)
|
||||
- [First-Time Setup](#first-time-setup)
|
||||
- [Viewing runs](#viewing-runs)
|
||||
- [Disabling wandb](#disabling-wandb)
|
||||
- [Advanced Usage: Dataset Versioning and Evaluation](#advanced-usage)
|
||||
- [Reports: Share your work with the world!](#reports)
|
||||
|
||||
## About Weights & Biases
|
||||
|
||||
Think of [W&B](https://wandb.ai/site?utm_campaign=repo_yolo_wandbtutorial) like GitHub for machine learning models. With a few lines of code, save everything you need to debug, compare and reproduce your models — architecture, hyperparameters, git commits, model weights, GPU usage, and even datasets and predictions.
|
||||
|
||||
Used by top researchers including teams at OpenAI, Lyft, Github, and MILA, W&B is part of the new standard of best practices for machine learning. How W&B can help you optimize your machine learning workflows:
|
||||
|
||||
- [Debug](https://wandb.ai/wandb/getting-started/reports/Visualize-Debug-Machine-Learning-Models--VmlldzoyNzY5MDk#Free-2) model performance in real time
|
||||
- [GPU usage](https://wandb.ai/wandb/getting-started/reports/Visualize-Debug-Machine-Learning-Models--VmlldzoyNzY5MDk#System-4) visualized automatically
|
||||
- [Custom charts](https://wandb.ai/wandb/customizable-charts/reports/Powerful-Custom-Charts-To-Debug-Model-Peformance--VmlldzoyNzY4ODI) for powerful, extensible visualization
|
||||
- [Share insights](https://wandb.ai/wandb/getting-started/reports/Visualize-Debug-Machine-Learning-Models--VmlldzoyNzY5MDk#Share-8) interactively with collaborators
|
||||
- [Optimize hyperparameters](https://docs.wandb.com/sweeps) efficiently
|
||||
- [Track](https://docs.wandb.com/artifacts) datasets, pipelines, and production models
|
||||
|
||||
## First-Time Setup
|
||||
|
||||
<details open>
|
||||
<summary> Toggle Details </summary>
|
||||
When you first train, W&B will prompt you to create a new account and will generate an **API key** for you. If you are an existing user you can retrieve your key from https://wandb.ai/authorize. This key is used to tell W&B where to log your data. You only need to supply your key once, and then it is remembered on the same device.
|
||||
|
||||
W&B will create a cloud **project** (default is 'YOLOv5') for your training runs, and each new training run will be provided a unique run **name** within that project as project/name. You can also manually set your project and run name as:
|
||||
|
||||
```shell
|
||||
$ python train.py --project ... --name ...
|
||||
```
|
||||
|
||||
YOLOv5 notebook example: <a href="https://colab.research.google.com/github/ultralytics/yolov5/blob/master/tutorial.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"></a> <a href="https://www.kaggle.com/ultralytics/yolov5"><img src="https://kaggle.com/static/images/open-in-kaggle.svg" alt="Open In Kaggle"></a>
|
||||
<img width="960" alt="Screen Shot 2021-09-29 at 10 23 13 PM" src="https://user-images.githubusercontent.com/26833433/135392431-1ab7920a-c49d-450a-b0b0-0c86ec86100e.png">
|
||||
|
||||
</details>
|
||||
|
||||
## Viewing Runs
|
||||
|
||||
<details open>
|
||||
<summary> Toggle Details </summary>
|
||||
Run information streams from your environment to the W&B cloud console as you train. This allows you to monitor and even cancel runs in <b>realtime</b> . All important information is logged:
|
||||
|
||||
- Training & Validation losses
|
||||
- Metrics: Precision, Recall, mAP@0.5, mAP@0.5:0.95
|
||||
- Learning Rate over time
|
||||
- A bounding box debugging panel, showing the training progress over time
|
||||
- GPU: Type, **GPU Utilization**, power, temperature, **CUDA memory usage**
|
||||
- System: Disk I/0, CPU utilization, RAM memory usage
|
||||
- Your trained model as W&B Artifact
|
||||
- Environment: OS and Python types, Git repository and state, **training command**
|
||||
|
||||
<p align="center"><img width="900" alt="Weights & Biases dashboard" src="https://user-images.githubusercontent.com/26833433/135390767-c28b050f-8455-4004-adb0-3b730386e2b2.png"></p>
|
||||
</details>
|
||||
|
||||
## Disabling wandb
|
||||
|
||||
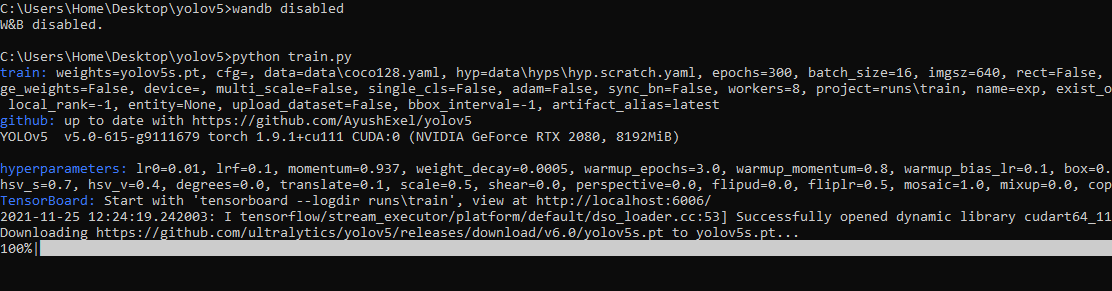
- training after running `wandb disabled` inside that directory creates no wandb run
|
||||
|
||||
|
||||
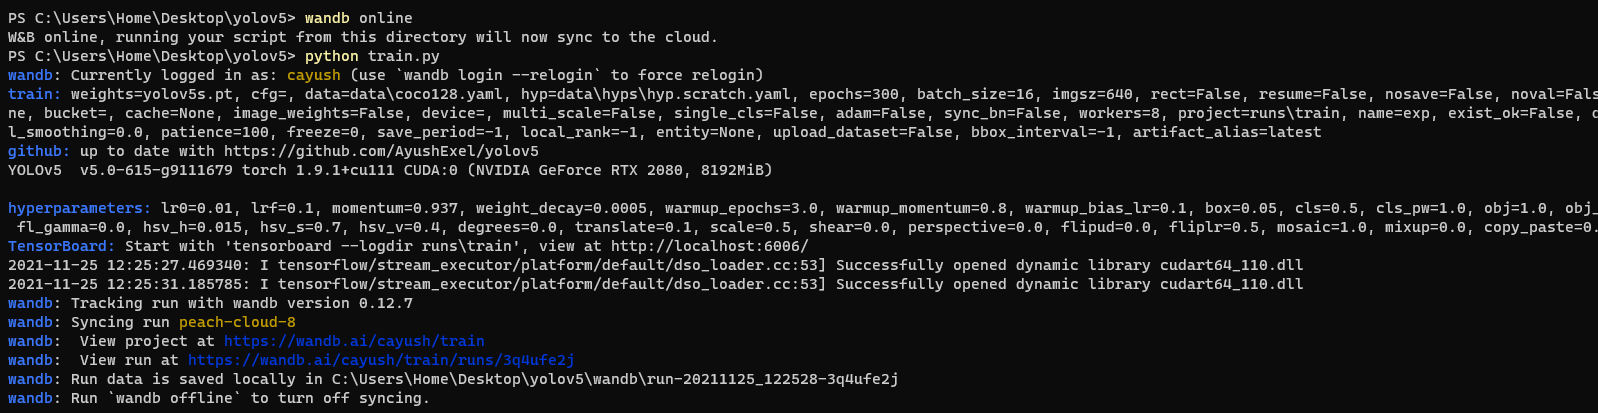
- To enable wandb again, run `wandb online`
|
||||
|
||||
|
||||
## Advanced Usage
|
||||
|
||||
You can leverage W&B artifacts and Tables integration to easily visualize and manage your datasets, models and training evaluations. Here are some quick examples to get you started.
|
||||
|
||||
<details open>
|
||||
<h3> 1: Train and Log Evaluation simultaneousy </h3>
|
||||
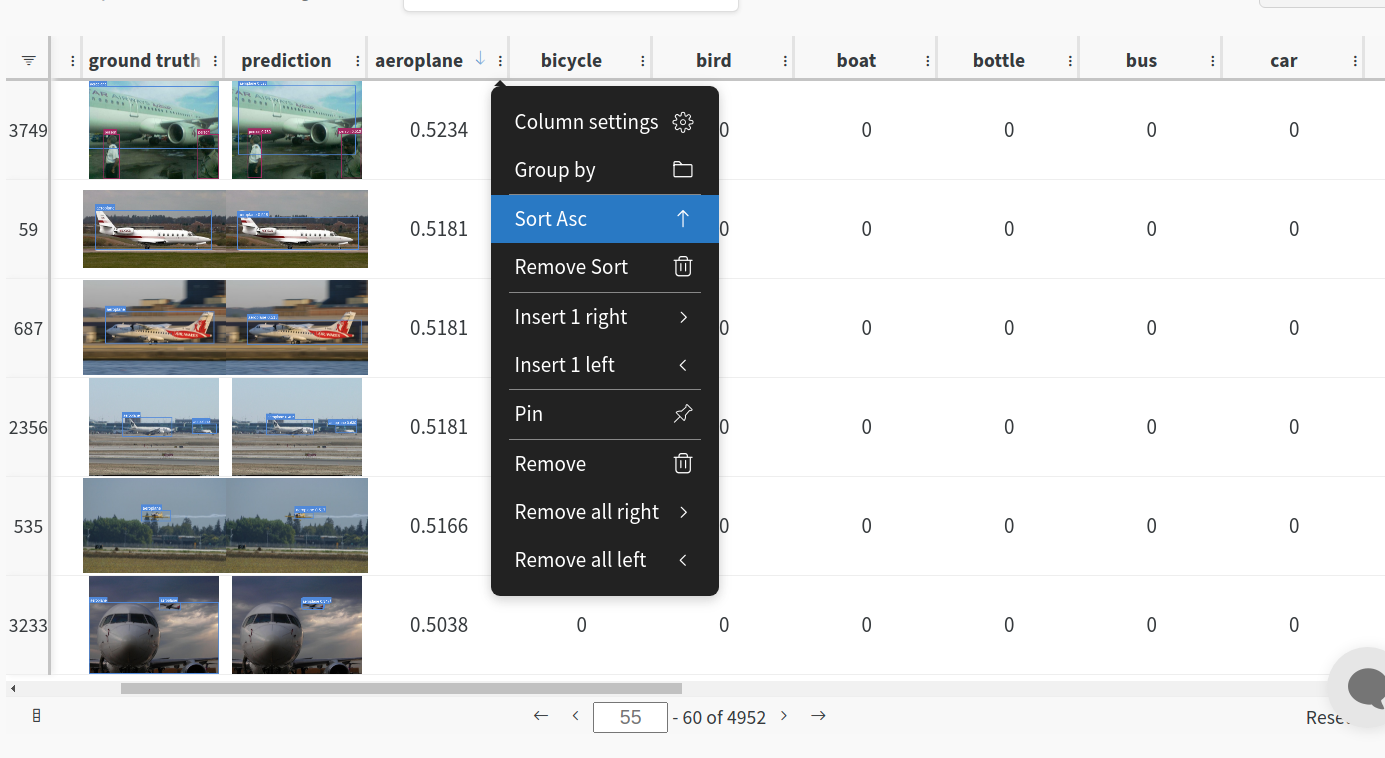
This is an extension of the previous section, but it'll also training after uploading the dataset. <b> This also evaluation Table</b>
|
||||
Evaluation table compares your predictions and ground truths across the validation set for each epoch. It uses the references to the already uploaded datasets,
|
||||
so no images will be uploaded from your system more than once.
|
||||
<details open>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --upload_data val</code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<h3>2. Visualize and Version Datasets</h3>
|
||||
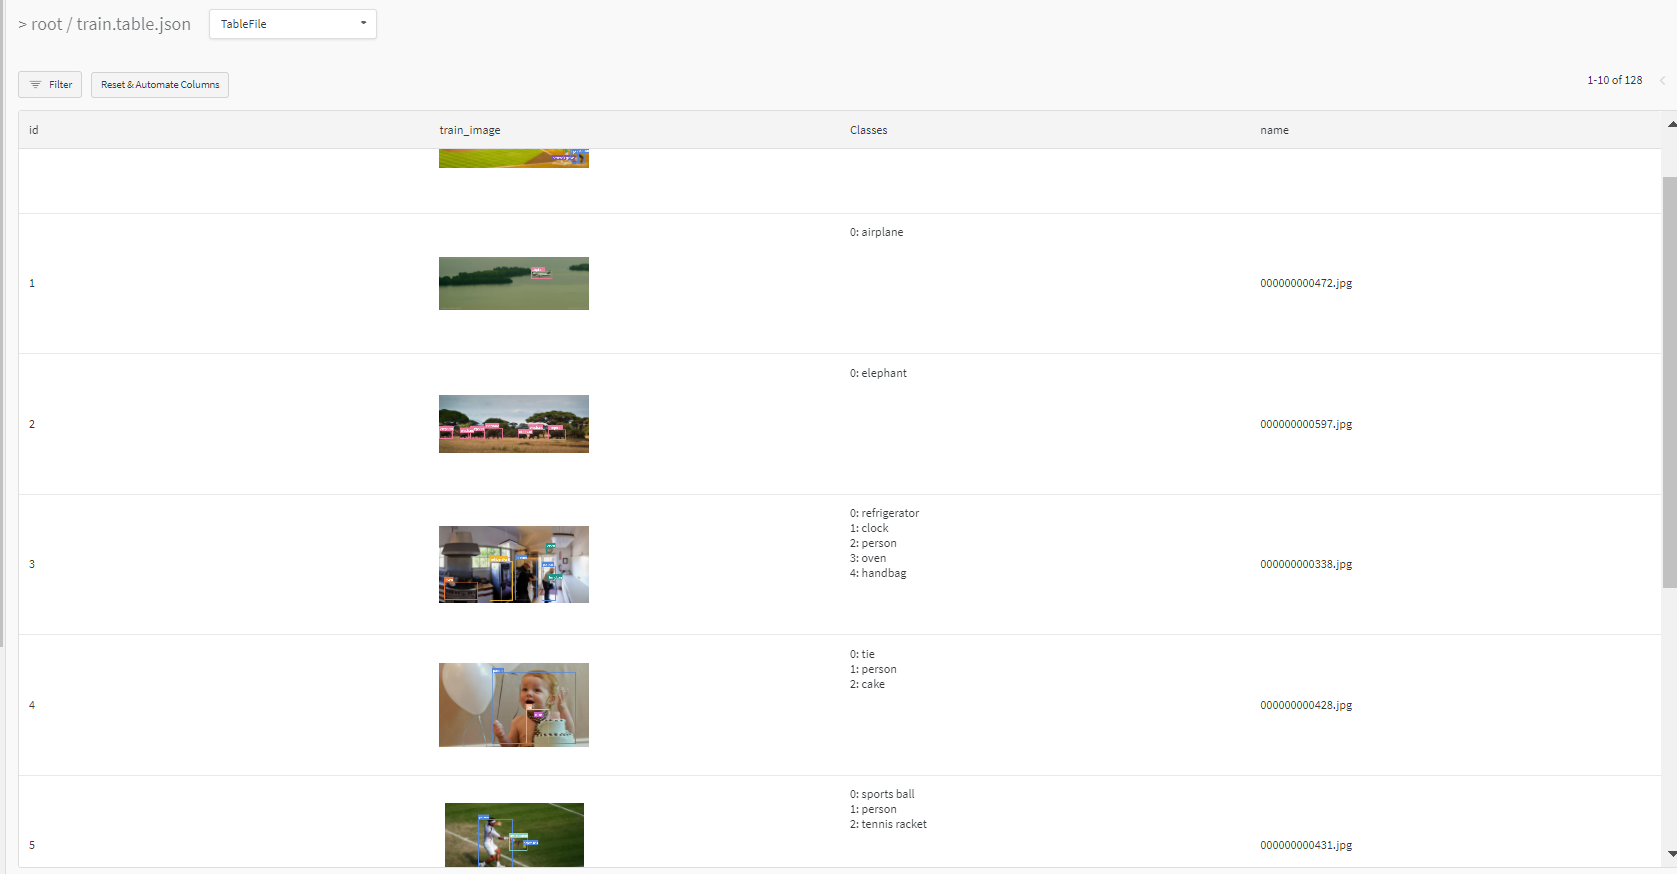
Log, visualize, dynamically query, and understand your data with <a href='https://docs.wandb.ai/guides/data-vis/tables'>W&B Tables</a>. You can use the following command to log your dataset as a W&B Table. This will generate a <code>{dataset}_wandb.yaml</code> file which can be used to train from dataset artifact.
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --project ... --name ... --data .. </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<h3> 3: Train using dataset artifact </h3>
|
||||
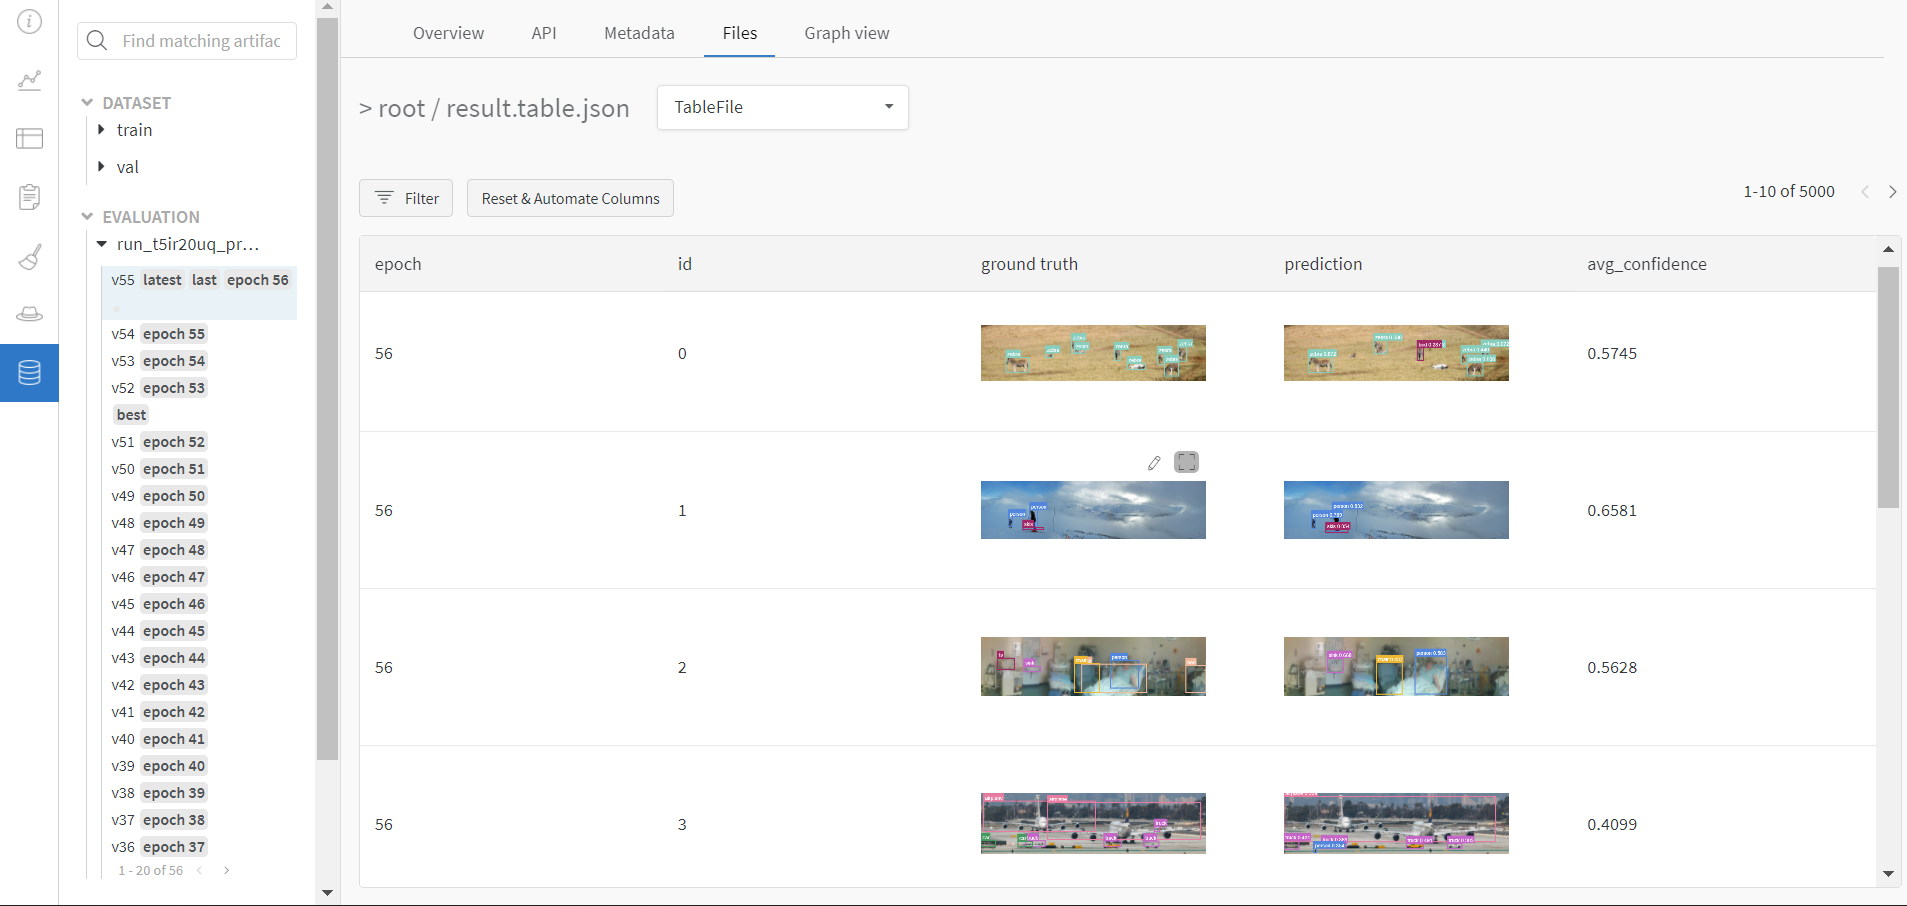
When you upload a dataset as described in the first section, you get a new config file with an added `_wandb` to its name. This file contains the information that
|
||||
can be used to train a model directly from the dataset artifact. <b> This also logs evaluation </b>
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --data {data}_wandb.yaml </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<h3> 4: Save model checkpoints as artifacts </h3>
|
||||
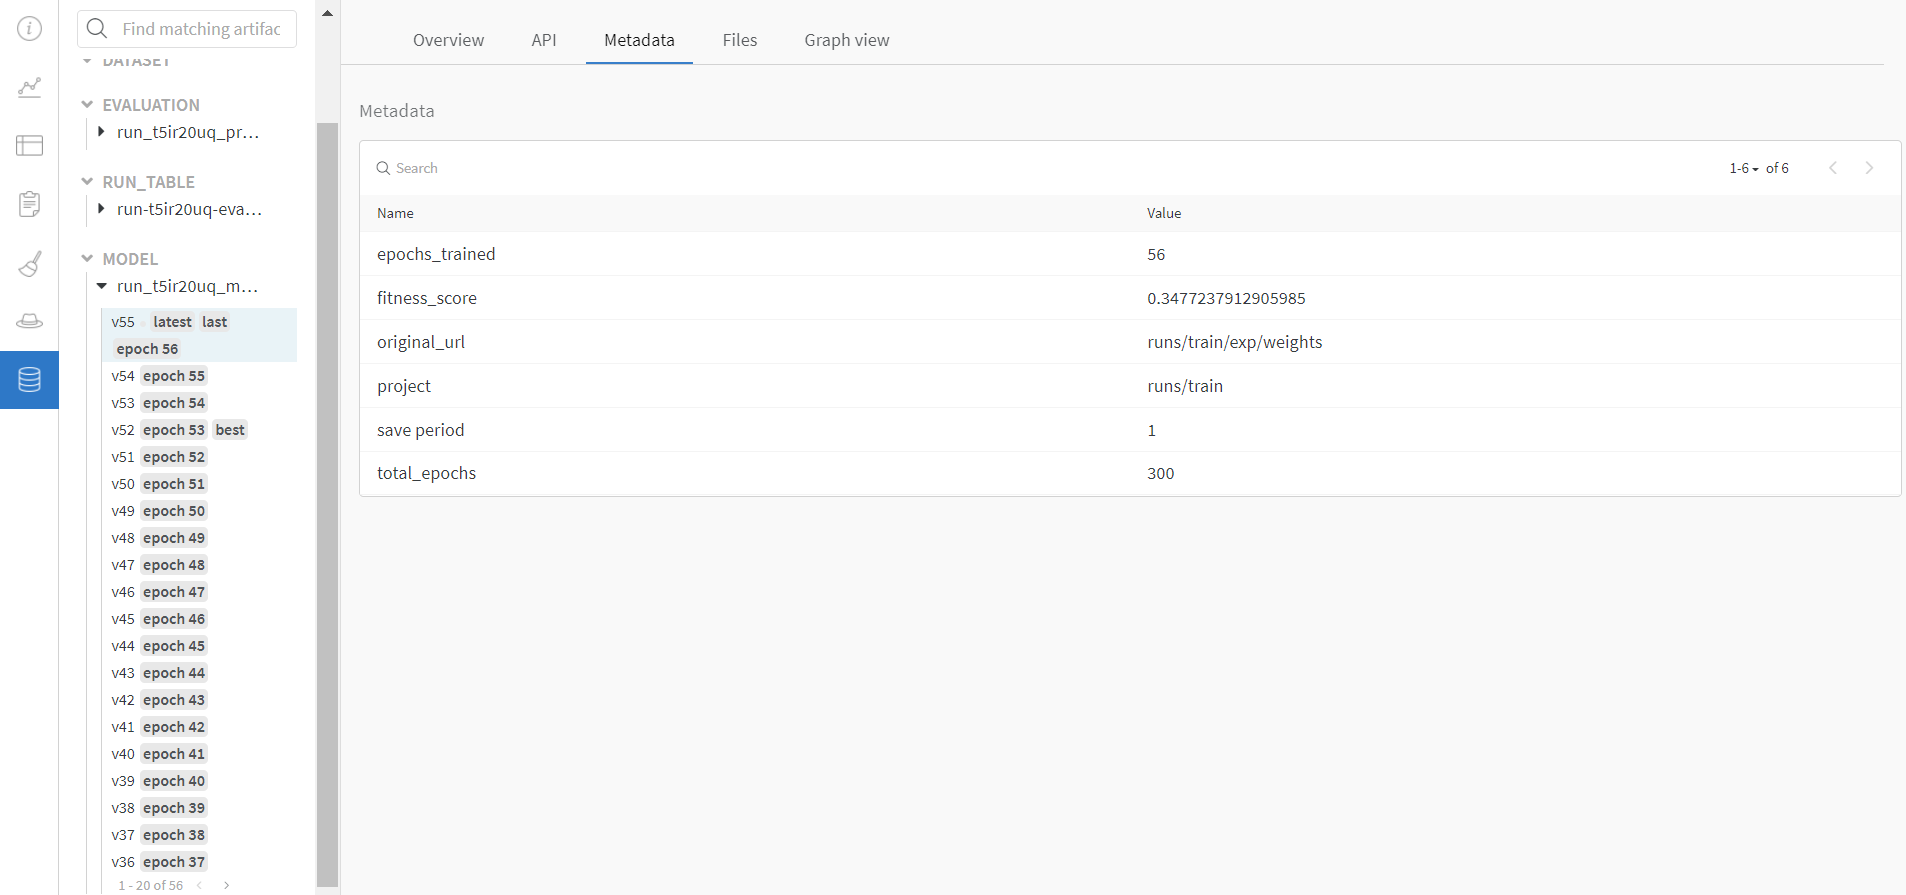
To enable saving and versioning checkpoints of your experiment, pass `--save_period n` with the base cammand, where `n` represents checkpoint interval.
|
||||
You can also log both the dataset and model checkpoints simultaneously. If not passed, only the final model will be logged
|
||||
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --save_period 1 </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
</details>
|
||||
|
||||
<h3> 5: Resume runs from checkpoint artifacts. </h3>
|
||||
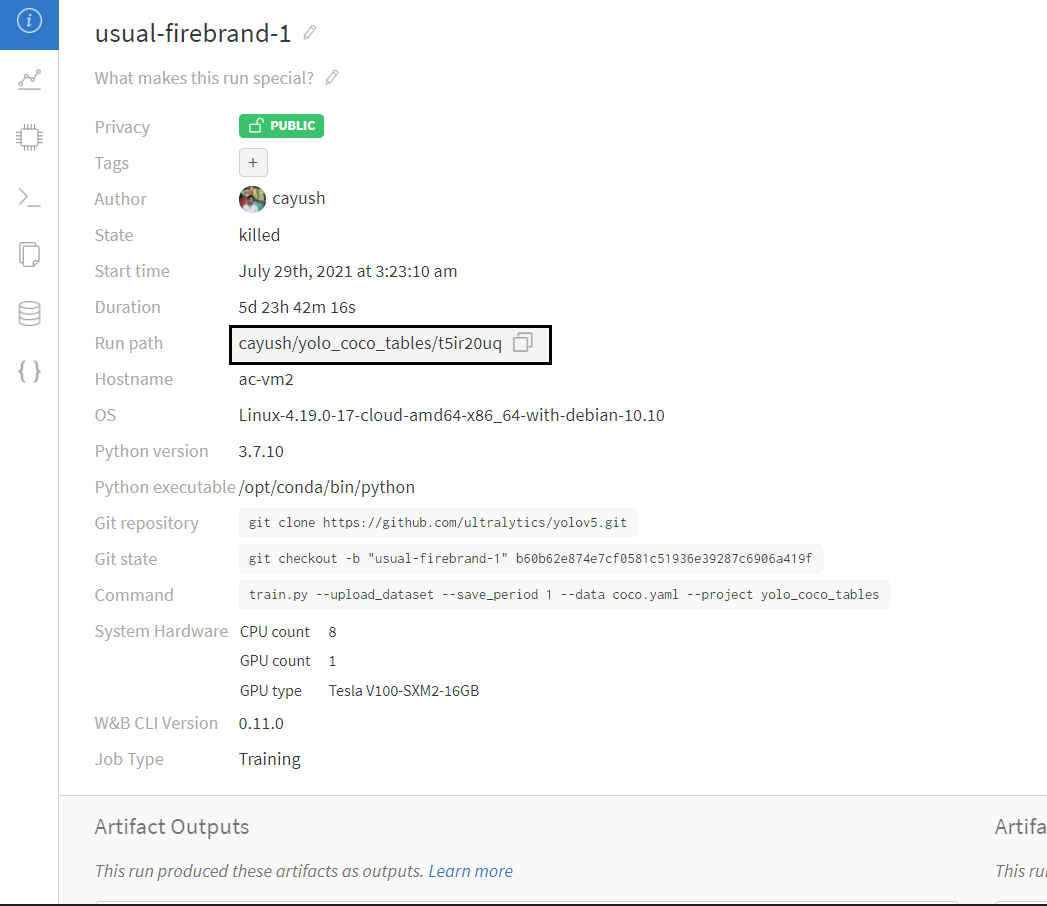
Any run can be resumed using artifacts if the <code>--resume</code> argument starts with <code>wandb-artifact://</code> prefix followed by the run path, i.e, <code>wandb-artifact://username/project/runid </code>. This doesn't require the model checkpoint to be present on the local system.
|
||||
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --resume wandb-artifact://{run_path} </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<h3> 6: Resume runs from dataset artifact & checkpoint artifacts. </h3>
|
||||
<b> Local dataset or model checkpoints are not required. This can be used to resume runs directly on a different device </b>
|
||||
The syntax is same as the previous section, but you'll need to lof both the dataset and model checkpoints as artifacts, i.e, set bot <code>--upload_dataset</code> or
|
||||
train from <code>_wandb.yaml</code> file and set <code>--save_period</code>
|
||||
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --resume wandb-artifact://{run_path} </code>
|
||||
|
||||

|
||||
|
||||
</details>
|
||||
|
||||
</details>
|
||||
|
||||
<h3> Reports </h3>
|
||||
W&B Reports can be created from your saved runs for sharing online. Once a report is created you will receive a link you can use to publically share your results. Here is an example report created from the COCO128 tutorial trainings of all four YOLOv5 models ([link](https://wandb.ai/glenn-jocher/yolov5_tutorial/reports/YOLOv5-COCO128-Tutorial-Results--VmlldzozMDI5OTY)).
|
||||
|
||||
<img width="900" alt="Weights & Biases Reports" src="https://user-images.githubusercontent.com/26833433/135394029-a17eaf86-c6c1-4b1d-bb80-b90e83aaffa7.png">
|
||||
|
||||
## Environments
|
||||
|
||||
YOLOv5 may be run in any of the following up-to-date verified environments (with all dependencies including [CUDA](https://developer.nvidia.com/cuda)/[CUDNN](https://developer.nvidia.com/cudnn), [Python](https://www.python.org/) and [PyTorch](https://pytorch.org/) preinstalled):
|
||||
|
||||
- **Google Colab and Kaggle** notebooks with free GPU: <a href="https://colab.research.google.com/github/ultralytics/yolov5/blob/master/tutorial.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" alt="Open In Colab"></a> <a href="https://www.kaggle.com/ultralytics/yolov5"><img src="https://kaggle.com/static/images/open-in-kaggle.svg" alt="Open In Kaggle"></a>
|
||||
- **Google Cloud** Deep Learning VM. See [GCP Quickstart Guide](https://github.com/ultralytics/yolov5/wiki/GCP-Quickstart)
|
||||
- **Amazon** Deep Learning AMI. See [AWS Quickstart Guide](https://github.com/ultralytics/yolov5/wiki/AWS-Quickstart)
|
||||
- **Docker Image**. See [Docker Quickstart Guide](https://github.com/ultralytics/yolov5/wiki/Docker-Quickstart) <a href="https://hub.docker.com/r/ultralytics/yolov5"><img src="https://img.shields.io/docker/pulls/ultralytics/yolov5?logo=docker" alt="Docker Pulls"></a>
|
||||
|
||||
## Status
|
||||
|
||||

|
||||
|
||||
If this badge is green, all [YOLOv5 GitHub Actions](https://github.com/ultralytics/yolov5/actions) Continuous Integration (CI) tests are currently passing. CI tests verify correct operation of YOLOv5 training ([train.py](https://github.com/ultralytics/yolov5/blob/master/train.py)), validation ([val.py](https://github.com/ultralytics/yolov5/blob/master/val.py)), inference ([detect.py](https://github.com/ultralytics/yolov5/blob/master/detect.py)) and export ([export.py](https://github.com/ultralytics/yolov5/blob/master/export.py)) on macOS, Windows, and Ubuntu every 24 hours and on every commit.
|
||||
@@ -1,27 +0,0 @@
|
||||
import argparse
|
||||
|
||||
from wandb_utils import WandbLogger
|
||||
|
||||
from utils.general import LOGGER
|
||||
|
||||
WANDB_ARTIFACT_PREFIX = 'wandb-artifact://'
|
||||
|
||||
|
||||
def create_dataset_artifact(opt):
|
||||
logger = WandbLogger(opt, None, job_type='Dataset Creation') # TODO: return value unused
|
||||
if not logger.wandb:
|
||||
LOGGER.info("install wandb using `pip install wandb` to log the dataset")
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--data', type=str, default='data/coco128.yaml', help='data.yaml path')
|
||||
parser.add_argument('--single-cls', action='store_true', help='train as single-class dataset')
|
||||
parser.add_argument('--project', type=str, default='YOLOv5', help='name of W&B Project')
|
||||
parser.add_argument('--entity', default=None, help='W&B entity')
|
||||
parser.add_argument('--name', type=str, default='log dataset', help='name of W&B run')
|
||||
|
||||
opt = parser.parse_args()
|
||||
opt.resume = False # Explicitly disallow resume check for dataset upload job
|
||||
|
||||
create_dataset_artifact(opt)
|
||||
@@ -1,41 +0,0 @@
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
import wandb
|
||||
|
||||
FILE = Path(__file__).resolve()
|
||||
ROOT = FILE.parents[3] # YOLOv5 root directory
|
||||
if str(ROOT) not in sys.path:
|
||||
sys.path.append(str(ROOT)) # add ROOT to PATH
|
||||
|
||||
from train import parse_opt, train
|
||||
from utils.callbacks import Callbacks
|
||||
from utils.general import increment_path
|
||||
from utils.torch_utils import select_device
|
||||
|
||||
|
||||
def sweep():
|
||||
wandb.init()
|
||||
# Get hyp dict from sweep agent. Copy because train() modifies parameters which confused wandb.
|
||||
hyp_dict = vars(wandb.config).get("_items").copy()
|
||||
|
||||
# Workaround: get necessary opt args
|
||||
opt = parse_opt(known=True)
|
||||
opt.batch_size = hyp_dict.get("batch_size")
|
||||
opt.save_dir = str(increment_path(Path(opt.project) / opt.name, exist_ok=opt.exist_ok or opt.evolve))
|
||||
opt.epochs = hyp_dict.get("epochs")
|
||||
opt.nosave = True
|
||||
opt.data = hyp_dict.get("data")
|
||||
opt.weights = str(opt.weights)
|
||||
opt.cfg = str(opt.cfg)
|
||||
opt.data = str(opt.data)
|
||||
opt.hyp = str(opt.hyp)
|
||||
opt.project = str(opt.project)
|
||||
device = select_device(opt.device, batch_size=opt.batch_size)
|
||||
|
||||
# train
|
||||
train(hyp_dict, opt, device, callbacks=Callbacks())
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
sweep()
|
||||
@@ -1,143 +0,0 @@
|
||||
# Hyperparameters for training
|
||||
# To set range-
|
||||
# Provide min and max values as:
|
||||
# parameter:
|
||||
#
|
||||
# min: scalar
|
||||
# max: scalar
|
||||
# OR
|
||||
#
|
||||
# Set a specific list of search space-
|
||||
# parameter:
|
||||
# values: [scalar1, scalar2, scalar3...]
|
||||
#
|
||||
# You can use grid, bayesian and hyperopt search strategy
|
||||
# For more info on configuring sweeps visit - https://docs.wandb.ai/guides/sweeps/configuration
|
||||
|
||||
program: utils/loggers/wandb/sweep.py
|
||||
method: random
|
||||
metric:
|
||||
name: metrics/mAP_0.5
|
||||
goal: maximize
|
||||
|
||||
parameters:
|
||||
# hyperparameters: set either min, max range or values list
|
||||
data:
|
||||
value: "data/coco128.yaml"
|
||||
batch_size:
|
||||
values: [64]
|
||||
epochs:
|
||||
values: [10]
|
||||
|
||||
lr0:
|
||||
distribution: uniform
|
||||
min: 1e-5
|
||||
max: 1e-1
|
||||
lrf:
|
||||
distribution: uniform
|
||||
min: 0.01
|
||||
max: 1.0
|
||||
momentum:
|
||||
distribution: uniform
|
||||
min: 0.6
|
||||
max: 0.98
|
||||
weight_decay:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.001
|
||||
warmup_epochs:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 5.0
|
||||
warmup_momentum:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.95
|
||||
warmup_bias_lr:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.2
|
||||
box:
|
||||
distribution: uniform
|
||||
min: 0.02
|
||||
max: 0.2
|
||||
cls:
|
||||
distribution: uniform
|
||||
min: 0.2
|
||||
max: 4.0
|
||||
cls_pw:
|
||||
distribution: uniform
|
||||
min: 0.5
|
||||
max: 2.0
|
||||
obj:
|
||||
distribution: uniform
|
||||
min: 0.2
|
||||
max: 4.0
|
||||
obj_pw:
|
||||
distribution: uniform
|
||||
min: 0.5
|
||||
max: 2.0
|
||||
iou_t:
|
||||
distribution: uniform
|
||||
min: 0.1
|
||||
max: 0.7
|
||||
anchor_t:
|
||||
distribution: uniform
|
||||
min: 2.0
|
||||
max: 8.0
|
||||
fl_gamma:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 4.0
|
||||
hsv_h:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.1
|
||||
hsv_s:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.9
|
||||
hsv_v:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.9
|
||||
degrees:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 45.0
|
||||
translate:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.9
|
||||
scale:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.9
|
||||
shear:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 10.0
|
||||
perspective:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 0.001
|
||||
flipud:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 1.0
|
||||
fliplr:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 1.0
|
||||
mosaic:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 1.0
|
||||
mixup:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 1.0
|
||||
copy_paste:
|
||||
distribution: uniform
|
||||
min: 0.0
|
||||
max: 1.0
|
||||
@@ -1,110 +1,32 @@
|
||||
"""Utilities and tools for tracking runs with Weights & Biases."""
|
||||
# YOLOv5 🚀 by Ultralytics, GPL-3.0 license
|
||||
|
||||
# WARNING ⚠️ wandb is deprecated and will be removed in future release.
|
||||
# See supported integrations at https://github.com/ultralytics/yolov5#integrations
|
||||
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
from contextlib import contextmanager
|
||||
from pathlib import Path
|
||||
from typing import Dict
|
||||
|
||||
import yaml
|
||||
from tqdm import tqdm
|
||||
from utils.general import LOGGER, colorstr
|
||||
|
||||
FILE = Path(__file__).resolve()
|
||||
ROOT = FILE.parents[3] # YOLOv5 root directory
|
||||
if str(ROOT) not in sys.path:
|
||||
sys.path.append(str(ROOT)) # add ROOT to PATH
|
||||
|
||||
from utils.dataloaders import LoadImagesAndLabels, img2label_paths
|
||||
from utils.general import LOGGER, check_dataset, check_file
|
||||
RANK = int(os.getenv('RANK', -1))
|
||||
DEPRECATION_WARNING = f"{colorstr('wandb')}: WARNING ⚠️ wandb is deprecated and will be removed in a future release. " \
|
||||
f"See supported integrations at https://github.com/ultralytics/yolov5#integrations."
|
||||
|
||||
try:
|
||||
import wandb
|
||||
|
||||
assert hasattr(wandb, '__version__') # verify package import not local dir
|
||||
LOGGER.warning(DEPRECATION_WARNING)
|
||||
except (ImportError, AssertionError):
|
||||
wandb = None
|
||||
|
||||
RANK = int(os.getenv('RANK', -1))
|
||||
WANDB_ARTIFACT_PREFIX = 'wandb-artifact://'
|
||||
|
||||
|
||||
def remove_prefix(from_string, prefix=WANDB_ARTIFACT_PREFIX):
|
||||
return from_string[len(prefix):]
|
||||
|
||||
|
||||
def check_wandb_config_file(data_config_file):
|
||||
wandb_config = '_wandb.'.join(data_config_file.rsplit('.', 1)) # updated data.yaml path
|
||||
if Path(wandb_config).is_file():
|
||||
return wandb_config
|
||||
return data_config_file
|
||||
|
||||
|
||||
def check_wandb_dataset(data_file):
|
||||
is_trainset_wandb_artifact = False
|
||||
is_valset_wandb_artifact = False
|
||||
if isinstance(data_file, dict):
|
||||
# In that case another dataset manager has already processed it and we don't have to
|
||||
return data_file
|
||||
if check_file(data_file) and data_file.endswith('.yaml'):
|
||||
with open(data_file, errors='ignore') as f:
|
||||
data_dict = yaml.safe_load(f)
|
||||
is_trainset_wandb_artifact = isinstance(data_dict['train'],
|
||||
str) and data_dict['train'].startswith(WANDB_ARTIFACT_PREFIX)
|
||||
is_valset_wandb_artifact = isinstance(data_dict['val'],
|
||||
str) and data_dict['val'].startswith(WANDB_ARTIFACT_PREFIX)
|
||||
if is_trainset_wandb_artifact or is_valset_wandb_artifact:
|
||||
return data_dict
|
||||
else:
|
||||
return check_dataset(data_file)
|
||||
|
||||
|
||||
def get_run_info(run_path):
|
||||
run_path = Path(remove_prefix(run_path, WANDB_ARTIFACT_PREFIX))
|
||||
run_id = run_path.stem
|
||||
project = run_path.parent.stem
|
||||
entity = run_path.parent.parent.stem
|
||||
model_artifact_name = 'run_' + run_id + '_model'
|
||||
return entity, project, run_id, model_artifact_name
|
||||
|
||||
|
||||
def check_wandb_resume(opt):
|
||||
process_wandb_config_ddp_mode(opt) if RANK not in [-1, 0] else None
|
||||
if isinstance(opt.resume, str):
|
||||
if opt.resume.startswith(WANDB_ARTIFACT_PREFIX):
|
||||
if RANK not in [-1, 0]: # For resuming DDP runs
|
||||
entity, project, run_id, model_artifact_name = get_run_info(opt.resume)
|
||||
api = wandb.Api()
|
||||
artifact = api.artifact(entity + '/' + project + '/' + model_artifact_name + ':latest')
|
||||
modeldir = artifact.download()
|
||||
opt.weights = str(Path(modeldir) / "last.pt")
|
||||
return True
|
||||
return None
|
||||
|
||||
|
||||
def process_wandb_config_ddp_mode(opt):
|
||||
with open(check_file(opt.data), errors='ignore') as f:
|
||||
data_dict = yaml.safe_load(f) # data dict
|
||||
train_dir, val_dir = None, None
|
||||
if isinstance(data_dict['train'], str) and data_dict['train'].startswith(WANDB_ARTIFACT_PREFIX):
|
||||
api = wandb.Api()
|
||||
train_artifact = api.artifact(remove_prefix(data_dict['train']) + ':' + opt.artifact_alias)
|
||||
train_dir = train_artifact.download()
|
||||
train_path = Path(train_dir) / 'data/images/'
|
||||
data_dict['train'] = str(train_path)
|
||||
|
||||
if isinstance(data_dict['val'], str) and data_dict['val'].startswith(WANDB_ARTIFACT_PREFIX):
|
||||
api = wandb.Api()
|
||||
val_artifact = api.artifact(remove_prefix(data_dict['val']) + ':' + opt.artifact_alias)
|
||||
val_dir = val_artifact.download()
|
||||
val_path = Path(val_dir) / 'data/images/'
|
||||
data_dict['val'] = str(val_path)
|
||||
if train_dir or val_dir:
|
||||
ddp_data_path = str(Path(val_dir) / 'wandb_local_data.yaml')
|
||||
with open(ddp_data_path, 'w') as f:
|
||||
yaml.safe_dump(data_dict, f)
|
||||
opt.data = ddp_data_path
|
||||
|
||||
|
||||
class WandbLogger():
|
||||
"""Log training runs, datasets, models, and predictions to Weights & Biases.
|
||||
@@ -132,38 +54,16 @@ class WandbLogger():
|
||||
job_type (str) -- To set the job_type for this run
|
||||
|
||||
"""
|
||||
# Temporary-fix
|
||||
if opt.upload_dataset:
|
||||
opt.upload_dataset = False
|
||||
# LOGGER.info("Uploading Dataset functionality is not being supported temporarily due to a bug.")
|
||||
|
||||
# Pre-training routine --
|
||||
self.job_type = job_type
|
||||
self.wandb, self.wandb_run = wandb, None if not wandb else wandb.run
|
||||
self.wandb, self.wandb_run = wandb, wandb.run if wandb else None
|
||||
self.val_artifact, self.train_artifact = None, None
|
||||
self.train_artifact_path, self.val_artifact_path = None, None
|
||||
self.result_artifact = None
|
||||
self.val_table, self.result_table = None, None
|
||||
self.bbox_media_panel_images = []
|
||||
self.val_table_path_map = None
|
||||
self.max_imgs_to_log = 16
|
||||
self.wandb_artifact_data_dict = None
|
||||
self.data_dict = None
|
||||
# It's more elegant to stick to 1 wandb.init call,
|
||||
# but useful config data is overwritten in the WandbLogger's wandb.init call
|
||||
if isinstance(opt.resume, str): # checks resume from artifact
|
||||
if opt.resume.startswith(WANDB_ARTIFACT_PREFIX):
|
||||
entity, project, run_id, model_artifact_name = get_run_info(opt.resume)
|
||||
model_artifact_name = WANDB_ARTIFACT_PREFIX + model_artifact_name
|
||||
assert wandb, 'install wandb to resume wandb runs'
|
||||
# Resume wandb-artifact:// runs here| workaround for not overwriting wandb.config
|
||||
self.wandb_run = wandb.init(id=run_id,
|
||||
project=project,
|
||||
entity=entity,
|
||||
resume='allow',
|
||||
allow_val_change=True)
|
||||
opt.resume = model_artifact_name
|
||||
elif self.wandb:
|
||||
if self.wandb:
|
||||
self.wandb_run = wandb.init(config=opt,
|
||||
resume="allow",
|
||||
project='YOLOv5' if opt.project == 'runs/train' else Path(opt.project).stem,
|
||||
@@ -172,51 +72,15 @@ class WandbLogger():
|
||||
job_type=job_type,
|
||||
id=run_id,
|
||||
allow_val_change=True) if not wandb.run else wandb.run
|
||||
|
||||
if self.wandb_run:
|
||||
if self.job_type == 'Training':
|
||||
if opt.upload_dataset:
|
||||
if not opt.resume:
|
||||
self.wandb_artifact_data_dict = self.check_and_upload_dataset(opt)
|
||||
|
||||
if isinstance(opt.data, dict):
|
||||
# This means another dataset manager has already processed the dataset info (e.g. ClearML)
|
||||
# and they will have stored the already processed dict in opt.data
|
||||
self.data_dict = opt.data
|
||||
elif opt.resume:
|
||||
# resume from artifact
|
||||
if isinstance(opt.resume, str) and opt.resume.startswith(WANDB_ARTIFACT_PREFIX):
|
||||
self.data_dict = dict(self.wandb_run.config.data_dict)
|
||||
else: # local resume
|
||||
self.data_dict = check_wandb_dataset(opt.data)
|
||||
else:
|
||||
self.data_dict = check_wandb_dataset(opt.data)
|
||||
self.wandb_artifact_data_dict = self.wandb_artifact_data_dict or self.data_dict
|
||||
|
||||
# write data_dict to config. useful for resuming from artifacts. Do this only when not resuming.
|
||||
self.wandb_run.config.update({'data_dict': self.wandb_artifact_data_dict}, allow_val_change=True)
|
||||
self.setup_training(opt)
|
||||
|
||||
if self.job_type == 'Dataset Creation':
|
||||
self.wandb_run.config.update({"upload_dataset": True})
|
||||
self.data_dict = self.check_and_upload_dataset(opt)
|
||||
|
||||
def check_and_upload_dataset(self, opt):
|
||||
"""
|
||||
Check if the dataset format is compatible and upload it as W&B artifact
|
||||
|
||||
arguments:
|
||||
opt (namespace)-- Commandline arguments for current run
|
||||
|
||||
returns:
|
||||
Updated dataset info dictionary where local dataset paths are replaced by WAND_ARFACT_PREFIX links.
|
||||
"""
|
||||
assert wandb, 'Install wandb to upload dataset'
|
||||
config_path = self.log_dataset_artifact(opt.data, opt.single_cls,
|
||||
'YOLOv5' if opt.project == 'runs/train' else Path(opt.project).stem)
|
||||
with open(config_path, errors='ignore') as f:
|
||||
wandb_data_dict = yaml.safe_load(f)
|
||||
return wandb_data_dict
|
||||
|
||||
def setup_training(self, opt):
|
||||
"""
|
||||
Setup the necessary processes for training YOLO models:
|
||||
@@ -231,81 +95,18 @@ class WandbLogger():
|
||||
self.log_dict, self.current_epoch = {}, 0
|
||||
self.bbox_interval = opt.bbox_interval
|
||||
if isinstance(opt.resume, str):
|
||||
modeldir, _ = self.download_model_artifact(opt)
|
||||
if modeldir:
|
||||
self.weights = Path(modeldir) / "last.pt"
|
||||
model_dir, _ = self.download_model_artifact(opt)
|
||||
if model_dir:
|
||||
self.weights = Path(model_dir) / "last.pt"
|
||||
config = self.wandb_run.config
|
||||
opt.weights, opt.save_period, opt.batch_size, opt.bbox_interval, opt.epochs, opt.hyp, opt.imgsz = str(
|
||||
self.weights), config.save_period, config.batch_size, config.bbox_interval, config.epochs,\
|
||||
self.weights), config.save_period, config.batch_size, config.bbox_interval, config.epochs, \
|
||||
config.hyp, config.imgsz
|
||||
data_dict = self.data_dict
|
||||
if self.val_artifact is None: # If --upload_dataset is set, use the existing artifact, don't download
|
||||
self.train_artifact_path, self.train_artifact = self.download_dataset_artifact(
|
||||
data_dict.get('train'), opt.artifact_alias)
|
||||
self.val_artifact_path, self.val_artifact = self.download_dataset_artifact(
|
||||
data_dict.get('val'), opt.artifact_alias)
|
||||
|
||||
if self.train_artifact_path is not None:
|
||||
train_path = Path(self.train_artifact_path) / 'data/images/'
|
||||
data_dict['train'] = str(train_path)
|
||||
if self.val_artifact_path is not None:
|
||||
val_path = Path(self.val_artifact_path) / 'data/images/'
|
||||
data_dict['val'] = str(val_path)
|
||||
|
||||
if self.val_artifact is not None:
|
||||
self.result_artifact = wandb.Artifact("run_" + wandb.run.id + "_progress", "evaluation")
|
||||
columns = ["epoch", "id", "ground truth", "prediction"]
|
||||
columns.extend(self.data_dict['names'])
|
||||
self.result_table = wandb.Table(columns)
|
||||
self.val_table = self.val_artifact.get("val")
|
||||
if self.val_table_path_map is None:
|
||||
self.map_val_table_path()
|
||||
if opt.bbox_interval == -1:
|
||||
self.bbox_interval = opt.bbox_interval = (opt.epochs // 10) if opt.epochs > 10 else 1
|
||||
if opt.evolve or opt.noplots:
|
||||
self.bbox_interval = opt.bbox_interval = opt.epochs + 1 # disable bbox_interval
|
||||
train_from_artifact = self.train_artifact_path is not None and self.val_artifact_path is not None
|
||||
# Update the the data_dict to point to local artifacts dir
|
||||
if train_from_artifact:
|
||||
self.data_dict = data_dict
|
||||
|
||||
def download_dataset_artifact(self, path, alias):
|
||||
"""
|
||||
download the model checkpoint artifact if the path starts with WANDB_ARTIFACT_PREFIX
|
||||
|
||||
arguments:
|
||||
path -- path of the dataset to be used for training
|
||||
alias (str)-- alias of the artifact to be download/used for training
|
||||
|
||||
returns:
|
||||
(str, wandb.Artifact) -- path of the downladed dataset and it's corresponding artifact object if dataset
|
||||
is found otherwise returns (None, None)
|
||||
"""
|
||||
if isinstance(path, str) and path.startswith(WANDB_ARTIFACT_PREFIX):
|
||||
artifact_path = Path(remove_prefix(path, WANDB_ARTIFACT_PREFIX) + ":" + alias)
|
||||
dataset_artifact = wandb.use_artifact(artifact_path.as_posix().replace("\\", "/"))
|
||||
assert dataset_artifact is not None, "'Error: W&B dataset artifact doesn\'t exist'"
|
||||
datadir = dataset_artifact.download()
|
||||
return datadir, dataset_artifact
|
||||
return None, None
|
||||
|
||||
def download_model_artifact(self, opt):
|
||||
"""
|
||||
download the model checkpoint artifact if the resume path starts with WANDB_ARTIFACT_PREFIX
|
||||
|
||||
arguments:
|
||||
opt (namespace) -- Commandline arguments for this run
|
||||
"""
|
||||
if opt.resume.startswith(WANDB_ARTIFACT_PREFIX):
|
||||
model_artifact = wandb.use_artifact(remove_prefix(opt.resume, WANDB_ARTIFACT_PREFIX) + ":latest")
|
||||
assert model_artifact is not None, 'Error: W&B model artifact doesn\'t exist'
|
||||
modeldir = model_artifact.download()
|
||||
# epochs_trained = model_artifact.metadata.get('epochs_trained')
|
||||
total_epochs = model_artifact.metadata.get('total_epochs')
|
||||
is_finished = total_epochs is None
|
||||
assert not is_finished, 'training is finished, can only resume incomplete runs.'
|
||||
return modeldir, model_artifact
|
||||
return None, None
|
||||
|
||||
def log_model(self, path, opt, epoch, fitness_score, best_model=False):
|
||||
"""
|
||||
@@ -332,190 +133,8 @@ class WandbLogger():
|
||||
aliases=['latest', 'last', 'epoch ' + str(self.current_epoch), 'best' if best_model else ''])
|
||||
LOGGER.info(f"Saving model artifact on epoch {epoch + 1}")
|
||||
|
||||
def log_dataset_artifact(self, data_file, single_cls, project, overwrite_config=False):
|
||||
"""
|
||||
Log the dataset as W&B artifact and return the new data file with W&B links
|
||||
|
||||
arguments:
|
||||
data_file (str) -- the .yaml file with information about the dataset like - path, classes etc.
|
||||
single_class (boolean) -- train multi-class data as single-class
|
||||
project (str) -- project name. Used to construct the artifact path
|
||||
overwrite_config (boolean) -- overwrites the data.yaml file if set to true otherwise creates a new
|
||||
file with _wandb postfix. Eg -> data_wandb.yaml
|
||||
|
||||
returns:
|
||||
the new .yaml file with artifact links. it can be used to start training directly from artifacts
|
||||
"""
|
||||
upload_dataset = self.wandb_run.config.upload_dataset
|
||||
log_val_only = isinstance(upload_dataset, str) and upload_dataset == 'val'
|
||||
self.data_dict = check_dataset(data_file) # parse and check
|
||||
data = dict(self.data_dict)
|
||||
nc, names = (1, ['item']) if single_cls else (int(data['nc']), data['names'])
|
||||
names = {k: v for k, v in enumerate(names)} # to index dictionary
|
||||
|
||||
# log train set
|
||||
if not log_val_only:
|
||||
self.train_artifact = self.create_dataset_table(LoadImagesAndLabels(data['train'], rect=True, batch_size=1),
|
||||
names,
|
||||
name='train') if data.get('train') else None
|
||||
if data.get('train'):
|
||||
data['train'] = WANDB_ARTIFACT_PREFIX + str(Path(project) / 'train')
|
||||
|
||||
self.val_artifact = self.create_dataset_table(
|
||||
LoadImagesAndLabels(data['val'], rect=True, batch_size=1), names, name='val') if data.get('val') else None
|
||||
if data.get('val'):
|
||||
data['val'] = WANDB_ARTIFACT_PREFIX + str(Path(project) / 'val')
|
||||
|
||||
path = Path(data_file)
|
||||
# create a _wandb.yaml file with artifacts links if both train and test set are logged
|
||||
if not log_val_only:
|
||||
path = (path.stem if overwrite_config else path.stem + '_wandb') + '.yaml' # updated data.yaml path
|
||||
path = ROOT / 'data' / path
|
||||
data.pop('download', None)
|
||||
data.pop('path', None)
|
||||
with open(path, 'w') as f:
|
||||
yaml.safe_dump(data, f)
|
||||
LOGGER.info(f"Created dataset config file {path}")
|
||||
|
||||
if self.job_type == 'Training': # builds correct artifact pipeline graph
|
||||
if not log_val_only:
|
||||
self.wandb_run.log_artifact(
|
||||
self.train_artifact) # calling use_artifact downloads the dataset. NOT NEEDED!
|
||||
self.wandb_run.use_artifact(self.val_artifact)
|
||||
self.val_artifact.wait()
|
||||
self.val_table = self.val_artifact.get('val')
|
||||
self.map_val_table_path()
|
||||
else:
|
||||
self.wandb_run.log_artifact(self.train_artifact)
|
||||
self.wandb_run.log_artifact(self.val_artifact)
|
||||
return path
|
||||
|
||||
def map_val_table_path(self):
|
||||
"""
|
||||
Map the validation dataset Table like name of file -> it's id in the W&B Table.
|
||||
Useful for - referencing artifacts for evaluation.
|
||||
"""
|
||||
self.val_table_path_map = {}
|
||||
LOGGER.info("Mapping dataset")
|
||||
for i, data in enumerate(tqdm(self.val_table.data)):
|
||||
self.val_table_path_map[data[3]] = data[0]
|
||||
|
||||
def create_dataset_table(self, dataset: LoadImagesAndLabels, class_to_id: Dict[int, str], name: str = 'dataset'):
|
||||
"""
|
||||
Create and return W&B artifact containing W&B Table of the dataset.
|
||||
|
||||
arguments:
|
||||
dataset -- instance of LoadImagesAndLabels class used to iterate over the data to build Table
|
||||
class_to_id -- hash map that maps class ids to labels
|
||||
name -- name of the artifact
|
||||
|
||||
returns:
|
||||
dataset artifact to be logged or used
|
||||
"""
|
||||
# TODO: Explore multiprocessing to slpit this loop parallely| This is essential for speeding up the the logging
|
||||
artifact = wandb.Artifact(name=name, type="dataset")
|
||||
img_files = tqdm([dataset.path]) if isinstance(dataset.path, str) and Path(dataset.path).is_dir() else None
|
||||
img_files = tqdm(dataset.im_files) if not img_files else img_files
|
||||
for img_file in img_files:
|
||||
if Path(img_file).is_dir():
|
||||
artifact.add_dir(img_file, name='data/images')
|
||||
labels_path = 'labels'.join(dataset.path.rsplit('images', 1))
|
||||
artifact.add_dir(labels_path, name='data/labels')
|
||||
else:
|
||||
artifact.add_file(img_file, name='data/images/' + Path(img_file).name)
|
||||
label_file = Path(img2label_paths([img_file])[0])
|
||||
artifact.add_file(str(label_file), name='data/labels/' +
|
||||
label_file.name) if label_file.exists() else None
|
||||
table = wandb.Table(columns=["id", "train_image", "Classes", "name"])
|
||||
class_set = wandb.Classes([{'id': id, 'name': name} for id, name in class_to_id.items()])
|
||||
for si, (img, labels, paths, shapes) in enumerate(tqdm(dataset)):
|
||||
box_data, img_classes = [], {}
|
||||
for cls, *xywh in labels[:, 1:].tolist():
|
||||
cls = int(cls)
|
||||
box_data.append({
|
||||
"position": {
|
||||
"middle": [xywh[0], xywh[1]],
|
||||
"width": xywh[2],
|
||||
"height": xywh[3]},
|
||||
"class_id": cls,
|
||||
"box_caption": "%s" % (class_to_id[cls])})
|
||||
img_classes[cls] = class_to_id[cls]
|
||||
boxes = {"ground_truth": {"box_data": box_data, "class_labels": class_to_id}} # inference-space
|
||||
table.add_data(si, wandb.Image(paths, classes=class_set, boxes=boxes), list(img_classes.values()),
|
||||
Path(paths).name)
|
||||
artifact.add(table, name)
|
||||
return artifact
|
||||
|
||||
def log_training_progress(self, predn, path, names):
|
||||
"""
|
||||
Build evaluation Table. Uses reference from validation dataset table.
|
||||
|
||||
arguments:
|
||||
predn (list): list of predictions in the native space in the format - [xmin, ymin, xmax, ymax, confidence, class]
|
||||
path (str): local path of the current evaluation image
|
||||
names (dict(int, str)): hash map that maps class ids to labels
|
||||
"""
|
||||
class_set = wandb.Classes([{'id': id, 'name': name} for id, name in names.items()])
|
||||
box_data = []
|
||||
avg_conf_per_class = [0] * len(self.data_dict['names'])
|
||||
pred_class_count = {}
|
||||
for *xyxy, conf, cls in predn.tolist():
|
||||
if conf >= 0.25:
|
||||
cls = int(cls)
|
||||
box_data.append({
|
||||
"position": {
|
||||
"minX": xyxy[0],
|
||||
"minY": xyxy[1],
|
||||
"maxX": xyxy[2],
|
||||
"maxY": xyxy[3]},
|
||||
"class_id": cls,
|
||||
"box_caption": f"{names[cls]} {conf:.3f}",
|
||||
"scores": {
|
||||
"class_score": conf},
|
||||
"domain": "pixel"})
|
||||
avg_conf_per_class[cls] += conf
|
||||
|
||||
if cls in pred_class_count:
|
||||
pred_class_count[cls] += 1
|
||||
else:
|
||||
pred_class_count[cls] = 1
|
||||
|
||||
for pred_class in pred_class_count.keys():
|
||||
avg_conf_per_class[pred_class] = avg_conf_per_class[pred_class] / pred_class_count[pred_class]
|
||||
|
||||
boxes = {"predictions": {"box_data": box_data, "class_labels": names}} # inference-space
|
||||
id = self.val_table_path_map[Path(path).name]
|
||||
self.result_table.add_data(self.current_epoch, id, self.val_table.data[id][1],
|
||||
wandb.Image(self.val_table.data[id][1], boxes=boxes, classes=class_set),
|
||||
*avg_conf_per_class)
|
||||
|
||||
def val_one_image(self, pred, predn, path, names, im):
|
||||
"""
|
||||
Log validation data for one image. updates the result Table if validation dataset is uploaded and log bbox media panel
|
||||
|
||||
arguments:
|
||||
pred (list): list of scaled predictions in the format - [xmin, ymin, xmax, ymax, confidence, class]
|
||||
predn (list): list of predictions in the native space - [xmin, ymin, xmax, ymax, confidence, class]
|
||||
path (str): local path of the current evaluation image
|
||||
"""
|
||||
if self.val_table and self.result_table: # Log Table if Val dataset is uploaded as artifact
|
||||
self.log_training_progress(predn, path, names)
|
||||
|
||||
if len(self.bbox_media_panel_images) < self.max_imgs_to_log and self.current_epoch > 0:
|
||||
if self.current_epoch % self.bbox_interval == 0:
|
||||
box_data = [{
|
||||
"position": {
|
||||
"minX": xyxy[0],
|
||||
"minY": xyxy[1],
|
||||
"maxX": xyxy[2],
|
||||
"maxY": xyxy[3]},
|
||||
"class_id": int(cls),
|
||||
"box_caption": f"{names[int(cls)]} {conf:.3f}",
|
||||
"scores": {
|
||||
"class_score": conf},
|
||||
"domain": "pixel"} for *xyxy, conf, cls in pred.tolist()]
|
||||
boxes = {"predictions": {"box_data": box_data, "class_labels": names}} # inference-space
|
||||
self.bbox_media_panel_images.append(wandb.Image(im, boxes=boxes, caption=path.name))
|
||||
pass
|
||||
|
||||
def log(self, log_dict):
|
||||
"""
|
||||
@@ -528,7 +147,7 @@ class WandbLogger():
|
||||
for key, value in log_dict.items():
|
||||
self.log_dict[key] = value
|
||||
|
||||
def end_epoch(self, best_result=False):
|
||||
def end_epoch(self):
|
||||
"""
|
||||
commit the log_dict, model artifacts and Tables to W&B and flush the log_dict.
|
||||
|
||||
@@ -537,8 +156,6 @@ class WandbLogger():
|
||||
"""
|
||||
if self.wandb_run:
|
||||
with all_logging_disabled():
|
||||
if self.bbox_media_panel_images:
|
||||
self.log_dict["BoundingBoxDebugger"] = self.bbox_media_panel_images
|
||||
try:
|
||||
wandb.log(self.log_dict)
|
||||
except BaseException as e:
|
||||
@@ -547,21 +164,7 @@ class WandbLogger():
|
||||
)
|
||||
self.wandb_run.finish()
|
||||
self.wandb_run = None
|
||||
|
||||
self.log_dict = {}
|
||||
self.bbox_media_panel_images = []
|
||||
if self.result_artifact:
|
||||
self.result_artifact.add(self.result_table, 'result')
|
||||
wandb.log_artifact(self.result_artifact,
|
||||
aliases=[
|
||||
'latest', 'last', 'epoch ' + str(self.current_epoch),
|
||||
('best' if best_result else '')])
|
||||
|
||||
wandb.log({"evaluation": self.result_table})
|
||||
columns = ["epoch", "id", "ground truth", "prediction"]
|
||||
columns.extend(self.data_dict['names'])
|
||||
self.result_table = wandb.Table(columns)
|
||||
self.result_artifact = wandb.Artifact("run_" + wandb.run.id + "_progress", "evaluation")
|
||||
|
||||
def finish_run(self):
|
||||
"""
|
||||
@@ -572,6 +175,7 @@ class WandbLogger():
|
||||
with all_logging_disabled():
|
||||
wandb.log(self.log_dict)
|
||||
wandb.run.finish()
|
||||
LOGGER.warning(DEPRECATION_WARNING)
|
||||
|
||||
|
||||
@contextmanager
|
||||
|
||||
Reference in new issue
Block a user