W&B: refactor W&B tables (#5737)
* update

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* reformat

* Single-line argparser argument

* Update README.md

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* Update README.md

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com>
Co-authored-by: Glenn Jocher <glenn.jocher@ultralytics.com>
This commit is contained in:

3 files changed
+70
-37
No files matched your search
@@ -2,6 +2,7 @@
|
||||
* [About Weights & Biases](#about-weights-&-biases)
|
||||
* [First-Time Setup](#first-time-setup)
|
||||
* [Viewing runs](#viewing-runs)
|
||||
* [Disabling wandb](#disabling-wandb)
|
||||
* [Advanced Usage: Dataset Versioning and Evaluation](#advanced-usage)
|
||||
* [Reports: Share your work with the world!](#reports)
|
||||
|
||||
@@ -49,14 +50,30 @@ Run information streams from your environment to the W&B cloud console as you tr
|
||||
* Environment: OS and Python types, Git repository and state, **training command**
|
||||
|
||||
<p align="center"><img width="900" alt="Weights & Biases dashboard" src="https://user-images.githubusercontent.com/26833433/135390767-c28b050f-8455-4004-adb0-3b730386e2b2.png"></p>
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
## Disabling wandb
|
||||
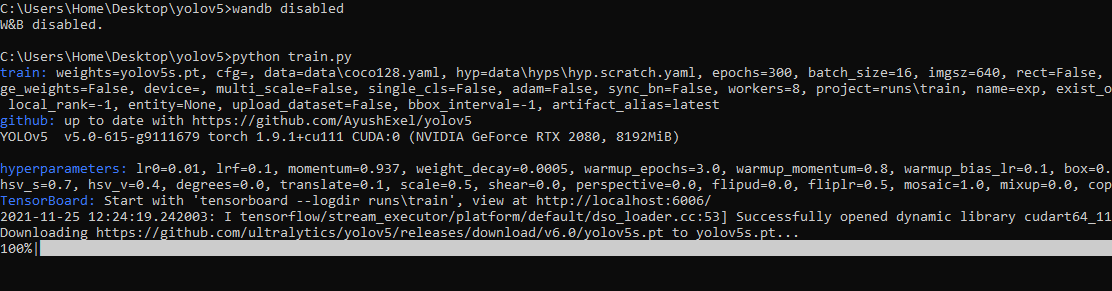
* training after running `wandb disabled` inside that directory creates no wandb run
|
||||
|
||||
|
||||
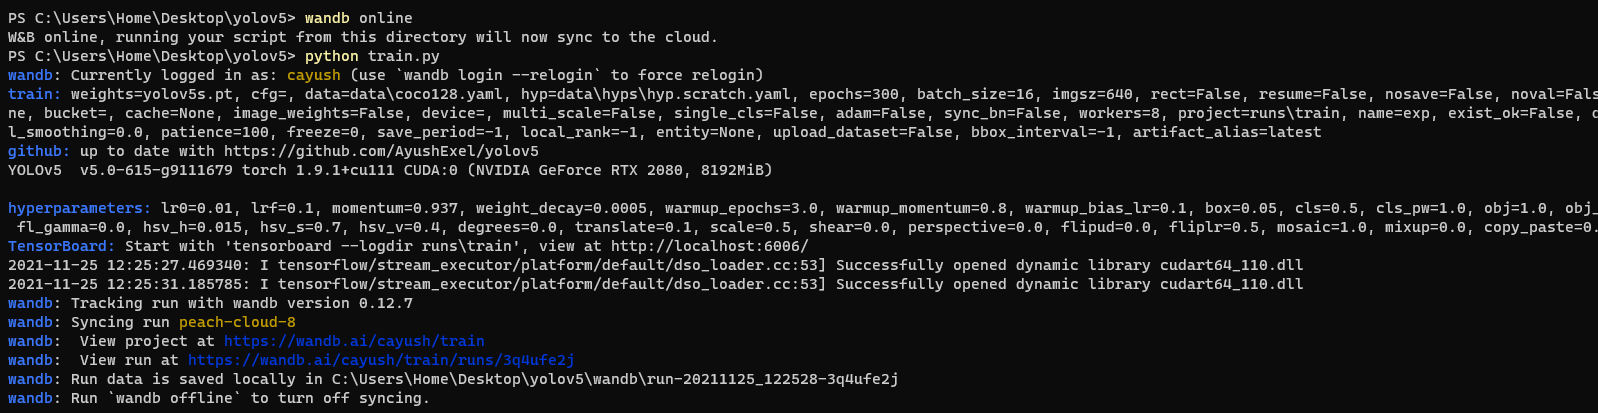
* To enable wandb again, run `wandb online`
|
||||
|
||||
|
||||
## Advanced Usage
|
||||
You can leverage W&B artifacts and Tables integration to easily visualize and manage your datasets, models and training evaluations. Here are some quick examples to get you started.
|
||||
<details open>
|
||||
<h3>1. Visualize and Version Datasets</h3>
|
||||
<h3> 1: Train and Log Evaluation simultaneousy </h3>
|
||||
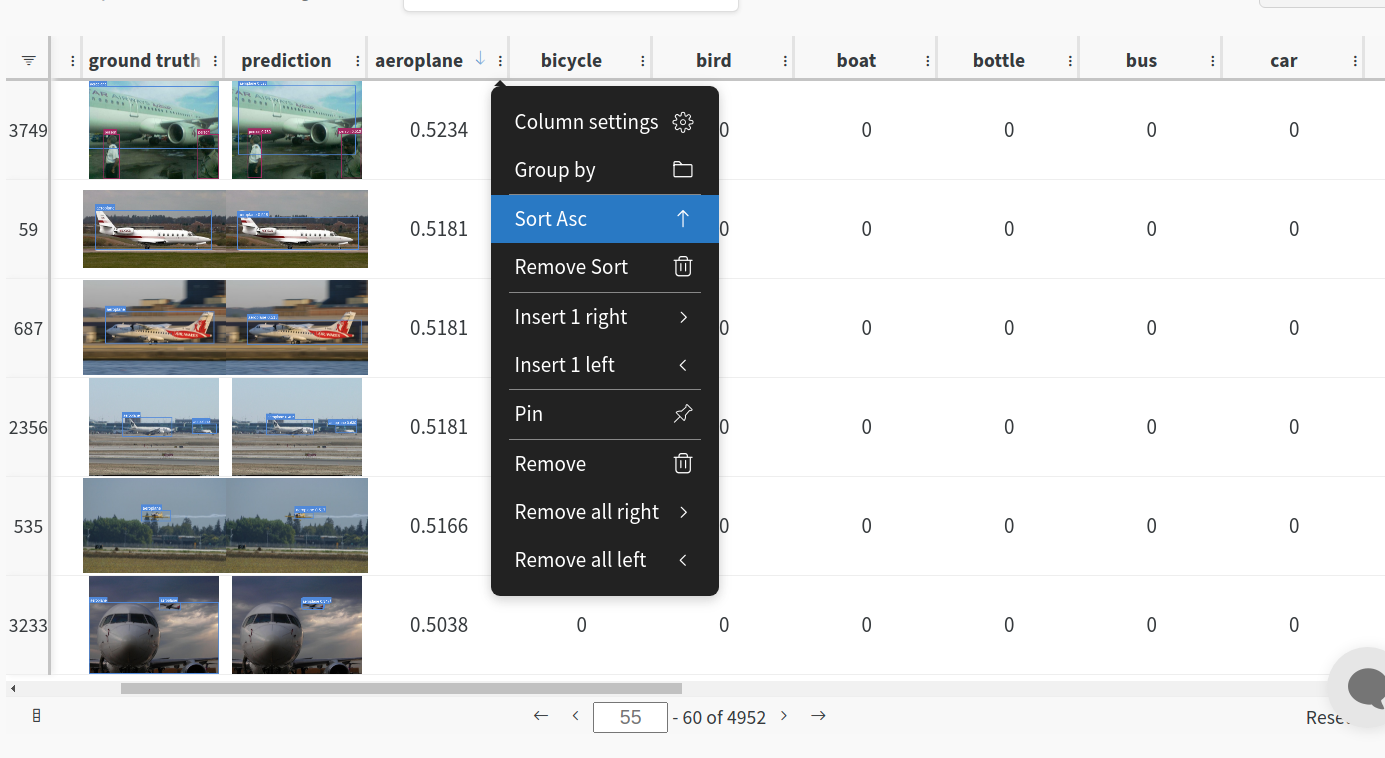
This is an extension of the previous section, but it'll also training after uploading the dataset. <b> This also evaluation Table</b>
|
||||
Evaluation table compares your predictions and ground truths across the validation set for each epoch. It uses the references to the already uploaded datasets,
|
||||
so no images will be uploaded from your system more than once.
|
||||
<details open>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --upload_data val</code>
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<h3>2. Visualize and Version Datasets</h3>
|
||||
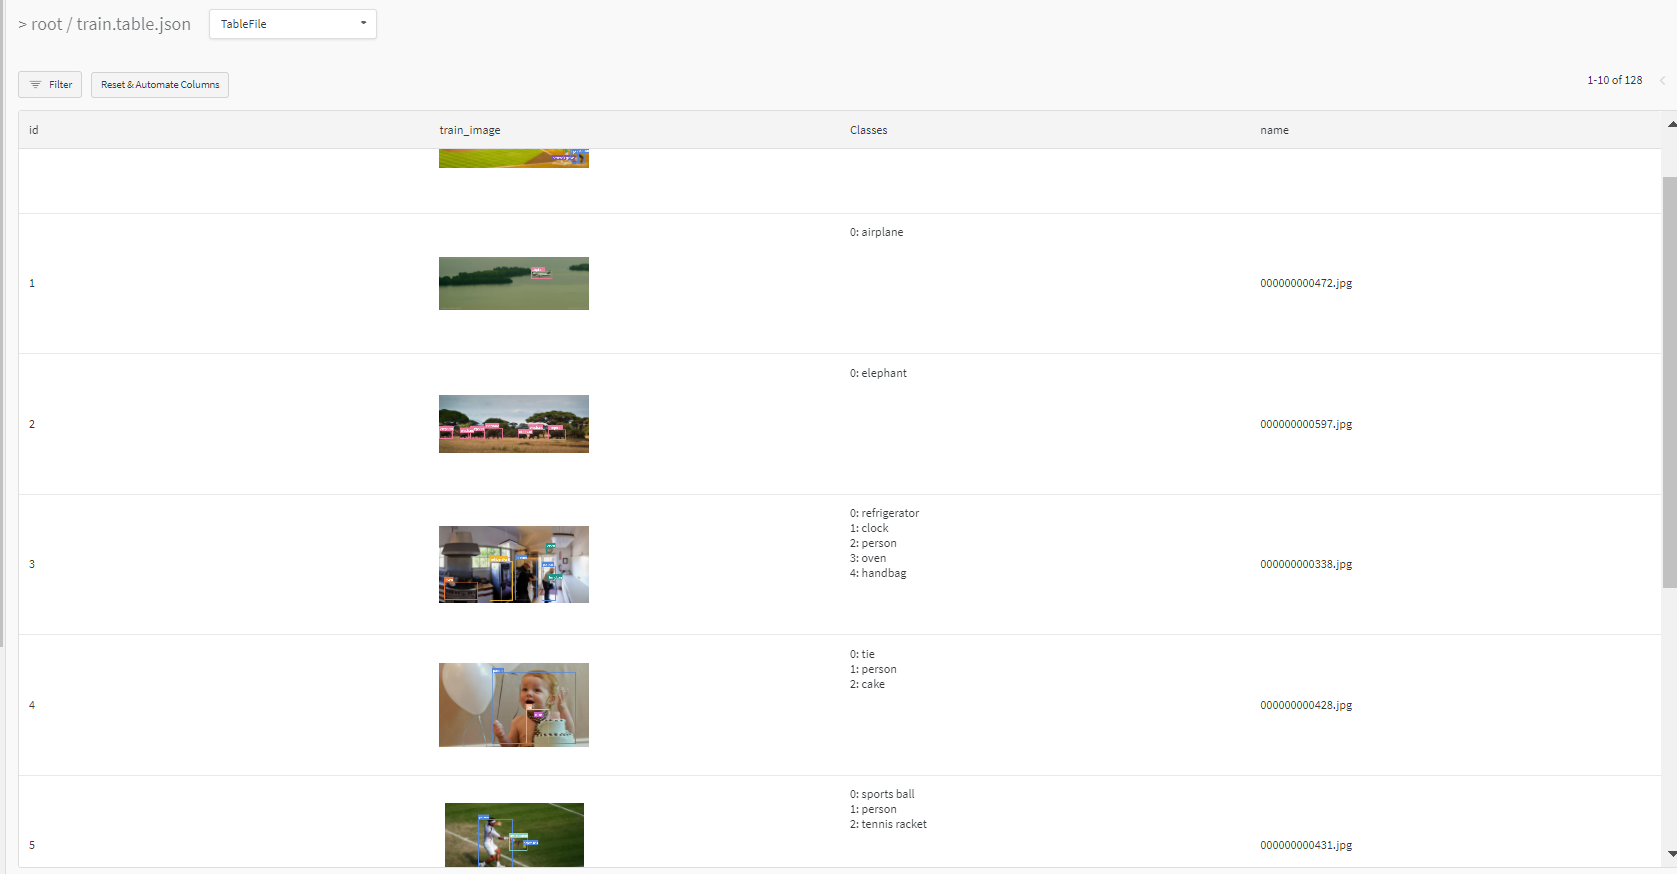
Log, visualize, dynamically query, and understand your data with <a href='https://docs.wandb.ai/guides/data-vis/tables'>W&B Tables</a>. You can use the following command to log your dataset as a W&B Table. This will generate a <code>{dataset}_wandb.yaml</code> file which can be used to train from dataset artifact.
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
@@ -65,23 +82,12 @@ You can leverage W&B artifacts and Tables integration to easily visualize and ma
|
||||
|
||||
</details>
|
||||
|
||||
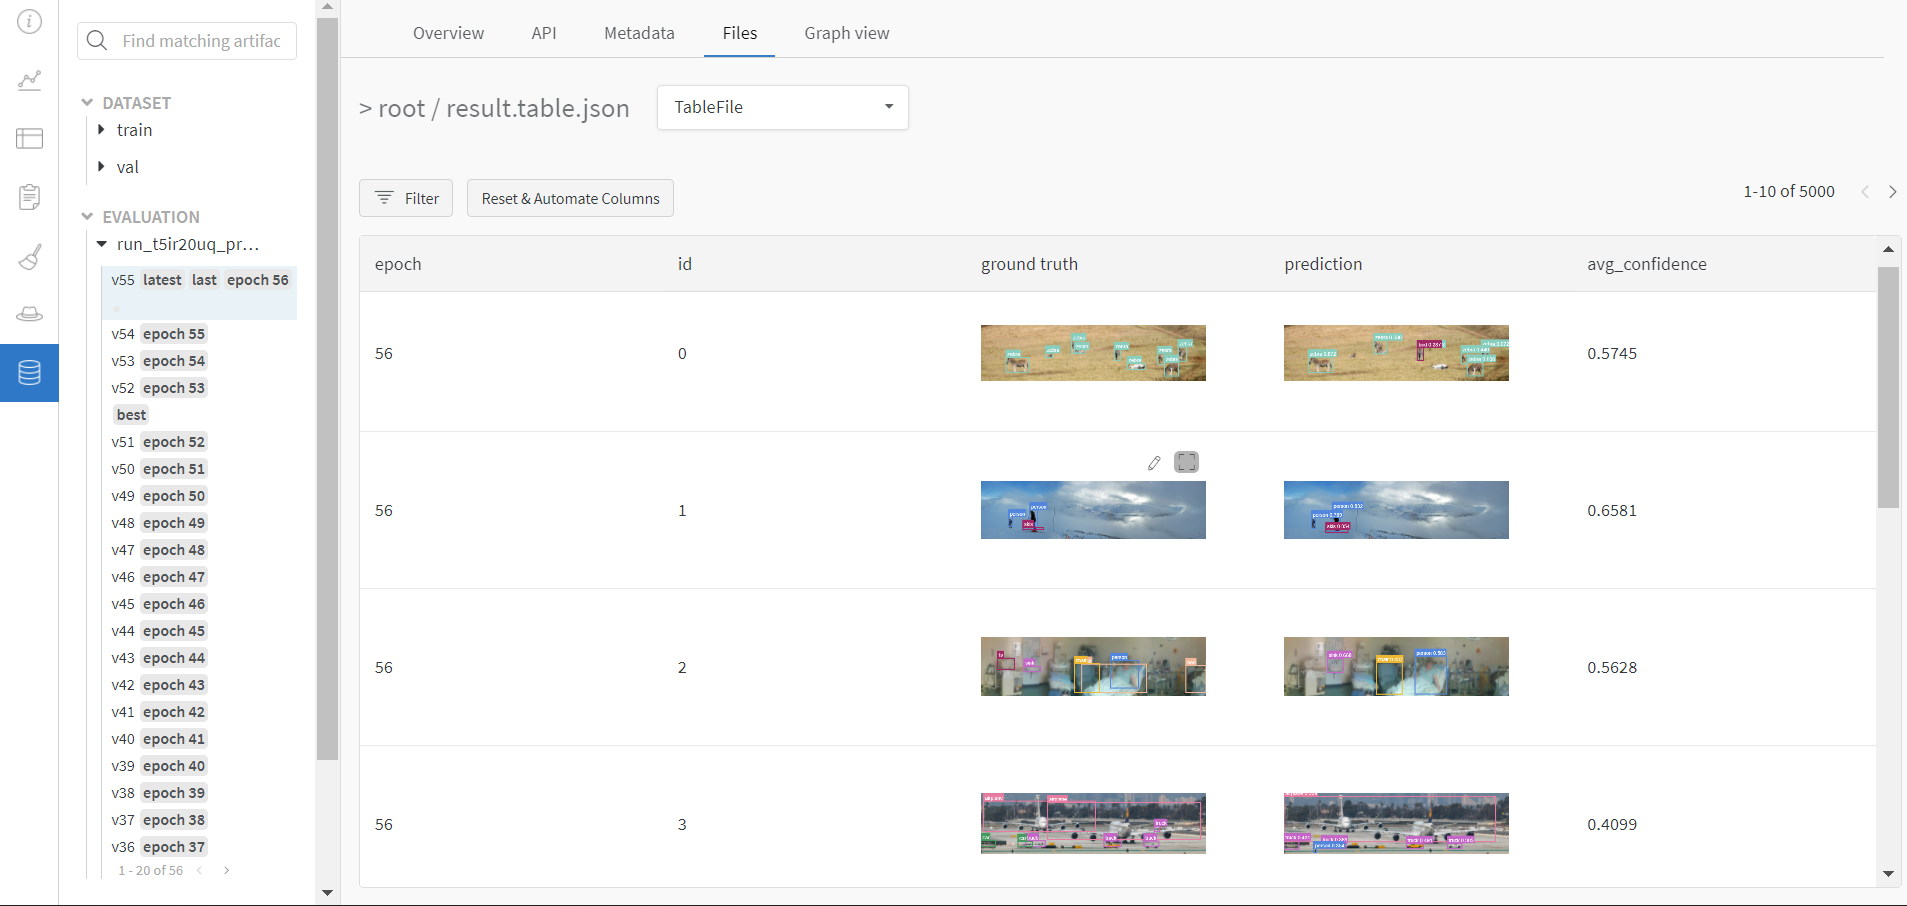
<h3> 2: Train and Log Evaluation simultaneousy </h3>
|
||||
This is an extension of the previous section, but it'll also training after uploading the dataset. <b> This also evaluation Table</b>
|
||||
Evaluation table compares your predictions and ground truths across the validation set for each epoch. It uses the references to the already uploaded datasets,
|
||||
so no images will be uploaded from your system more than once.
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --data .. --upload_data </code>
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<h3> 3: Train using dataset artifact </h3>
|
||||
When you upload a dataset as described in the first section, you get a new config file with an added `_wandb` to its name. This file contains the information that
|
||||
can be used to train a model directly from the dataset artifact. <b> This also logs evaluation </b>
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --data {data}_wandb.yaml </code>
|
||||
<b>Code</b> <code> $ python train.py --data {data}_wandb.yaml </code>
|
||||
|
||||

|
||||
</details>
|
||||
@@ -123,7 +129,6 @@ Any run can be resumed using artifacts if the <code>--resume</code> argument sta
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> Reports </h3>
|
||||
W&B Reports can be created from your saved runs for sharing online. Once a report is created you will receive a link you can use to publically share your results. Here is an example report created from the COCO128 tutorial trainings of all four YOLOv5 models ([link](https://wandb.ai/glenn-jocher/yolov5_tutorial/reports/YOLOv5-COCO128-Tutorial-Results--VmlldzozMDI5OTY)).
|
||||
|
||||
|
||||
Reference in new issue
Block a user