Add pre-commit CI actions (#4982)
* define pre-commit

* add CI code

* configure

* apply pre-commit

* fstring

* apply MD

* pre-commit

* Update torch_utils.py

* Update print strings

* notes

* Cleanup code-format.yml

* Update setup.cfg

* Update .pre-commit-config.yaml

Co-authored-by: Glenn Jocher <glenn.jocher@ultralytics.com>
This commit is contained in:
 Jirka BorovecandGlenn Jocher authored and GitHub committed
1 parent
a4fece8c14
commit
ed887b5976
30 files changed
+273
-113
No files matched your search
@@ -135,7 +135,7 @@ class Loggers():
|
||||
# Callback runs on training end
|
||||
if plots:
|
||||
plot_results(file=self.save_dir / 'results.csv') # save results.png
|
||||
files = ['results.png', 'confusion_matrix.png', *[f'{x}_curve.png' for x in ('F1', 'PR', 'P', 'R')]]
|
||||
files = ['results.png', 'confusion_matrix.png', *(f'{x}_curve.png' for x in ('F1', 'PR', 'P', 'R'))]
|
||||
files = [(self.save_dir / f) for f in files if (self.save_dir / f).exists()] # filter
|
||||
|
||||
if self.tb:
|
||||
|
||||
@@ -61,10 +61,10 @@ You can leverage W&B artifacts and Tables integration to easily visualize and ma
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
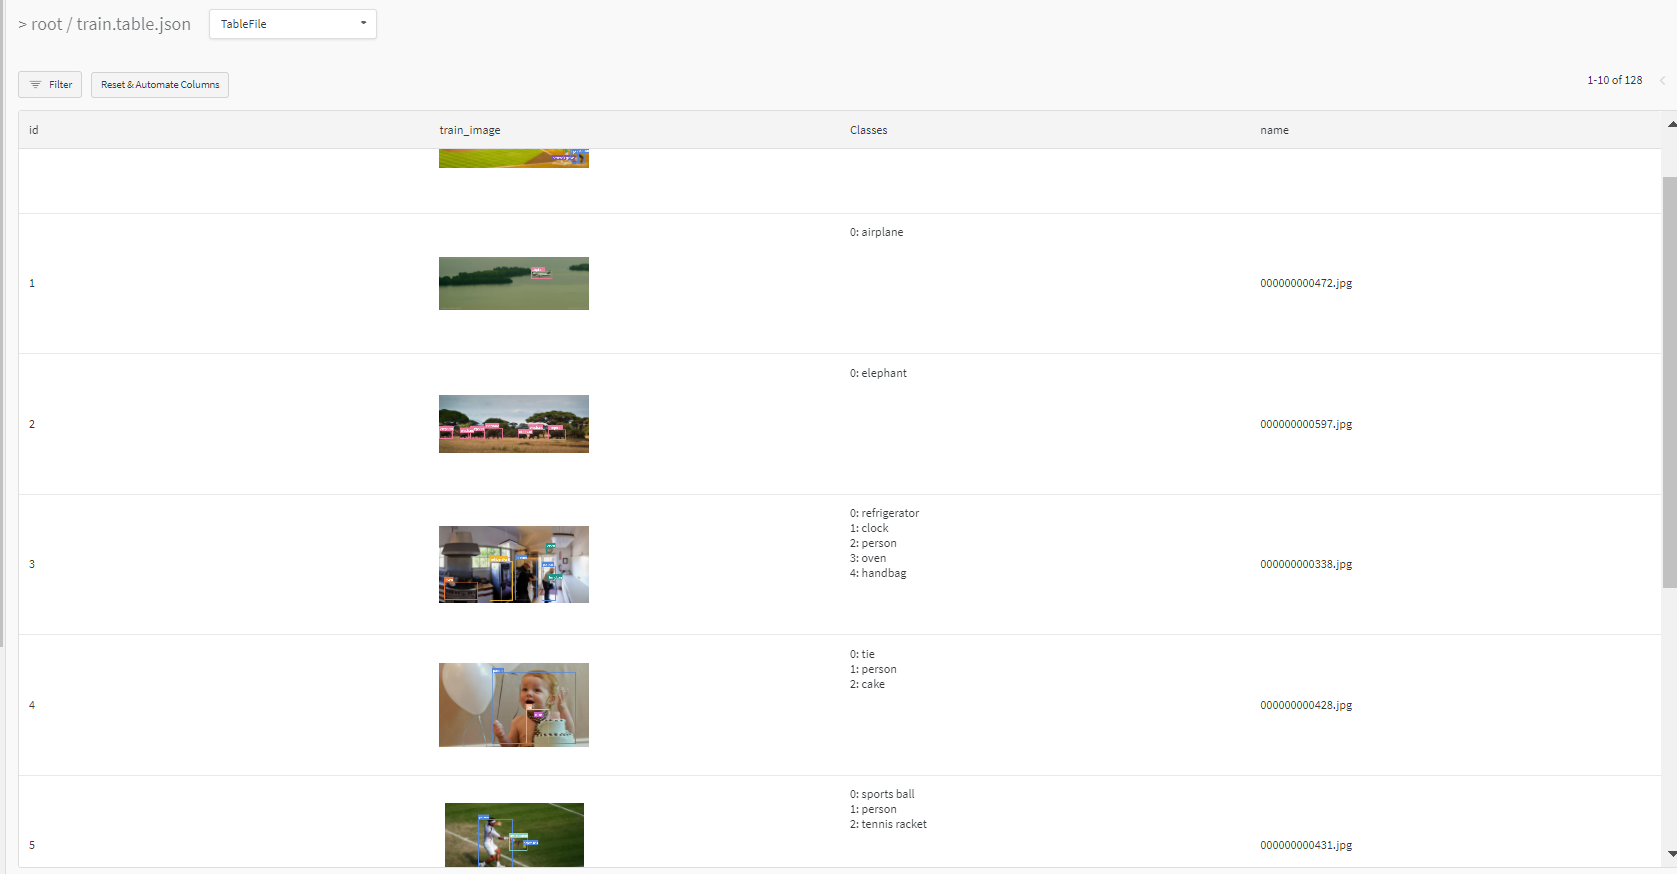
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --project ... --name ... --data .. </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> 2: Train and Log Evaluation simultaneousy </h3>
|
||||
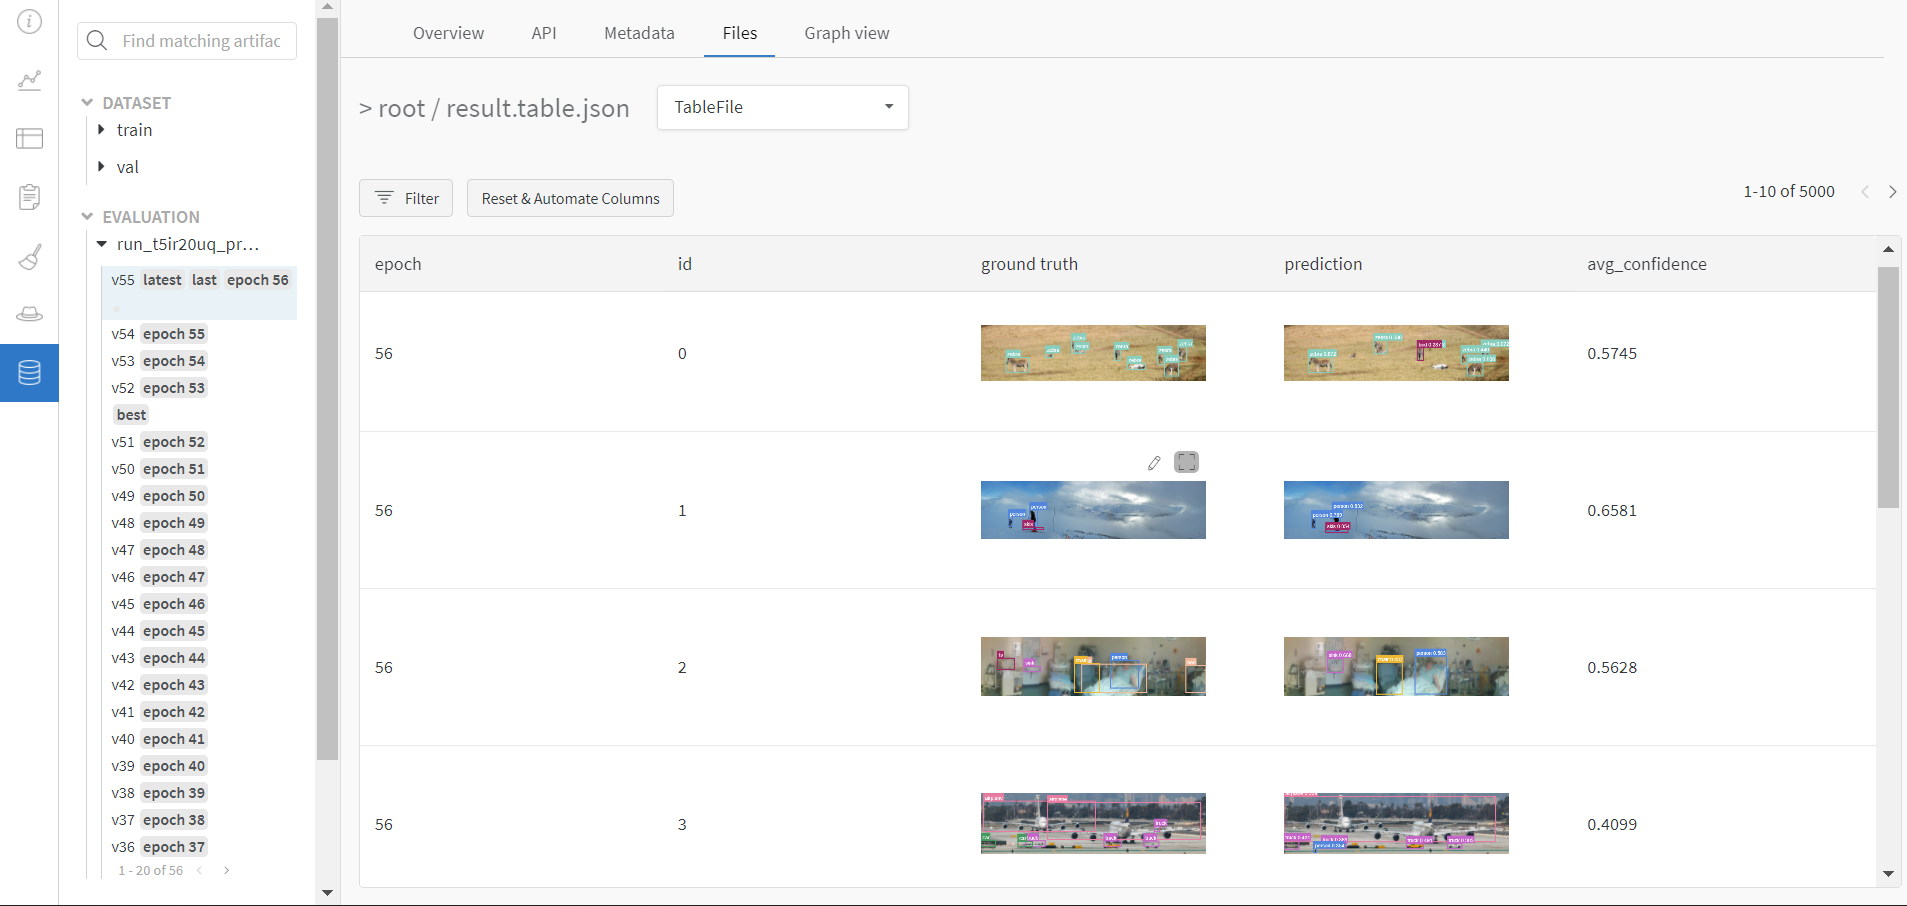
This is an extension of the previous section, but it'll also training after uploading the dataset. <b> This also evaluation Table</b>
|
||||
Evaluation table compares your predictions and ground truths across the validation set for each epoch. It uses the references to the already uploaded datasets,
|
||||
@@ -72,31 +72,31 @@ You can leverage W&B artifacts and Tables integration to easily visualize and ma
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --data .. --upload_data </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> 3: Train using dataset artifact </h3>
|
||||
When you upload a dataset as described in the first section, you get a new config file with an added `_wandb` to its name. This file contains the information that
|
||||
When you upload a dataset as described in the first section, you get a new config file with an added `_wandb` to its name. This file contains the information that
|
||||
can be used to train a model directly from the dataset artifact. <b> This also logs evaluation </b>
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python utils/logger/wandb/log_dataset.py --data {data}_wandb.yaml </code>
|
||||
|
||||
|
||||

|
||||
</details>
|
||||
|
||||
|
||||
<h3> 4: Save model checkpoints as artifacts </h3>
|
||||
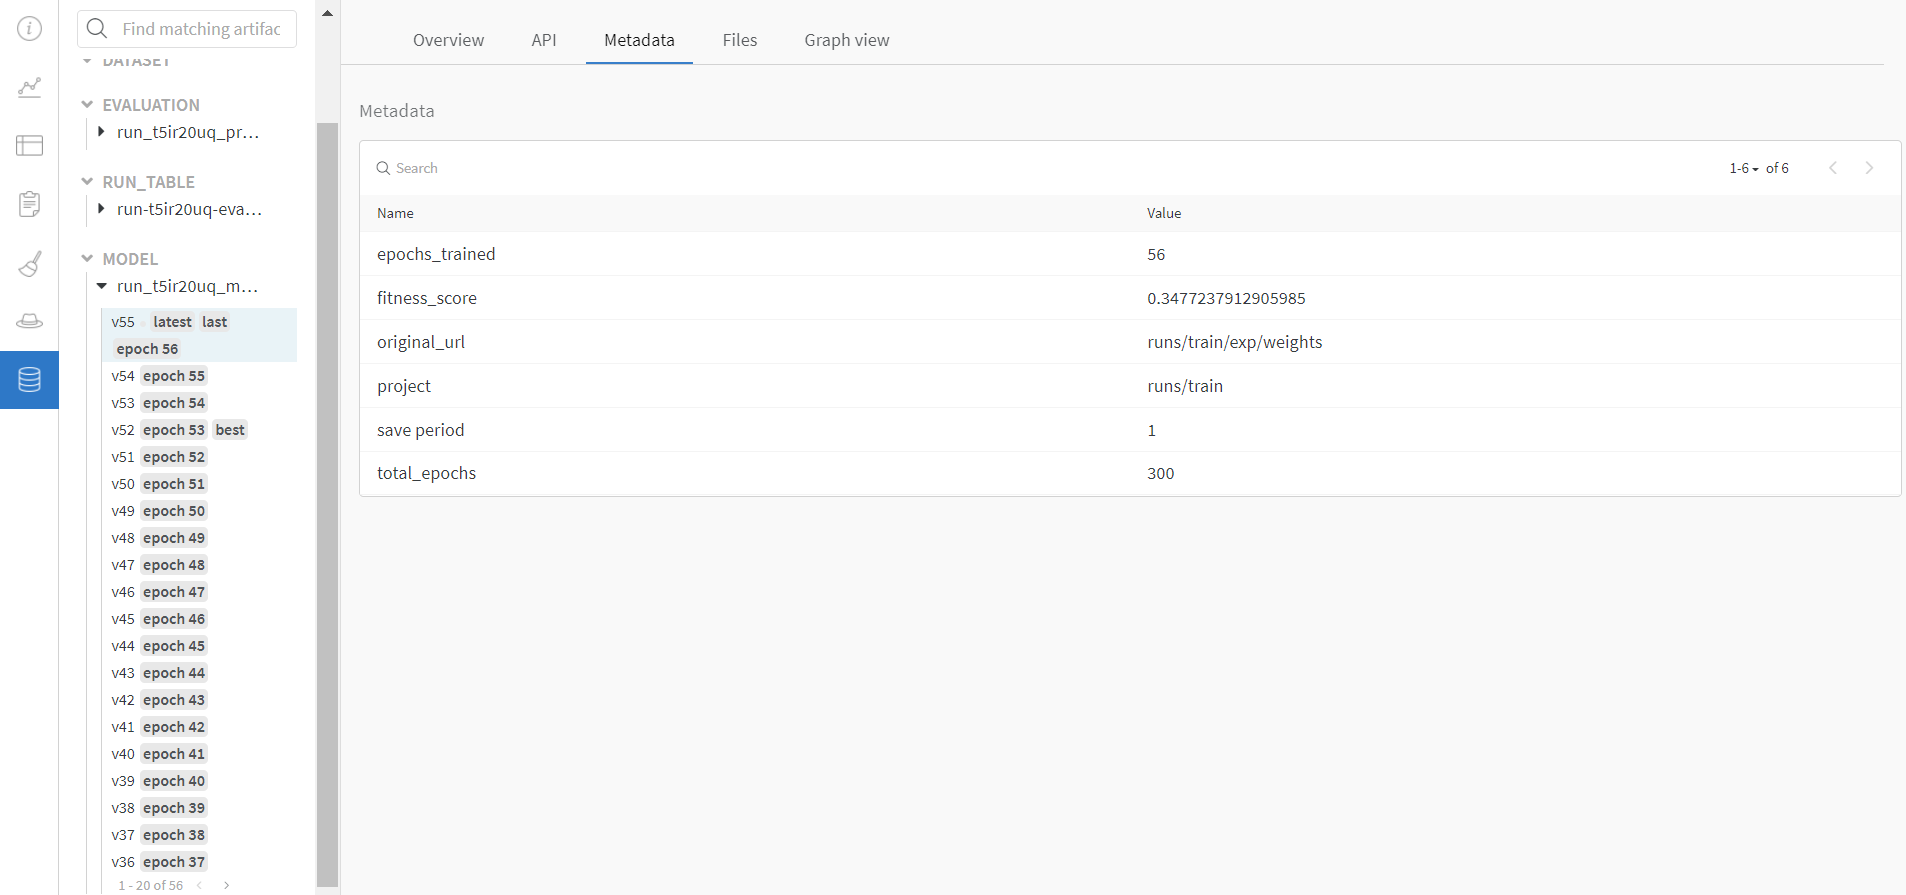
To enable saving and versioning checkpoints of your experiment, pass `--save_period n` with the base cammand, where `n` represents checkpoint interval.
|
||||
To enable saving and versioning checkpoints of your experiment, pass `--save_period n` with the base cammand, where `n` represents checkpoint interval.
|
||||
You can also log both the dataset and model checkpoints simultaneously. If not passed, only the final model will be logged
|
||||
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --save_period 1 </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
<h3> 5: Resume runs from checkpoint artifacts. </h3>
|
||||
@@ -105,28 +105,28 @@ Any run can be resumed using artifacts if the <code>--resume</code> argument sta
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
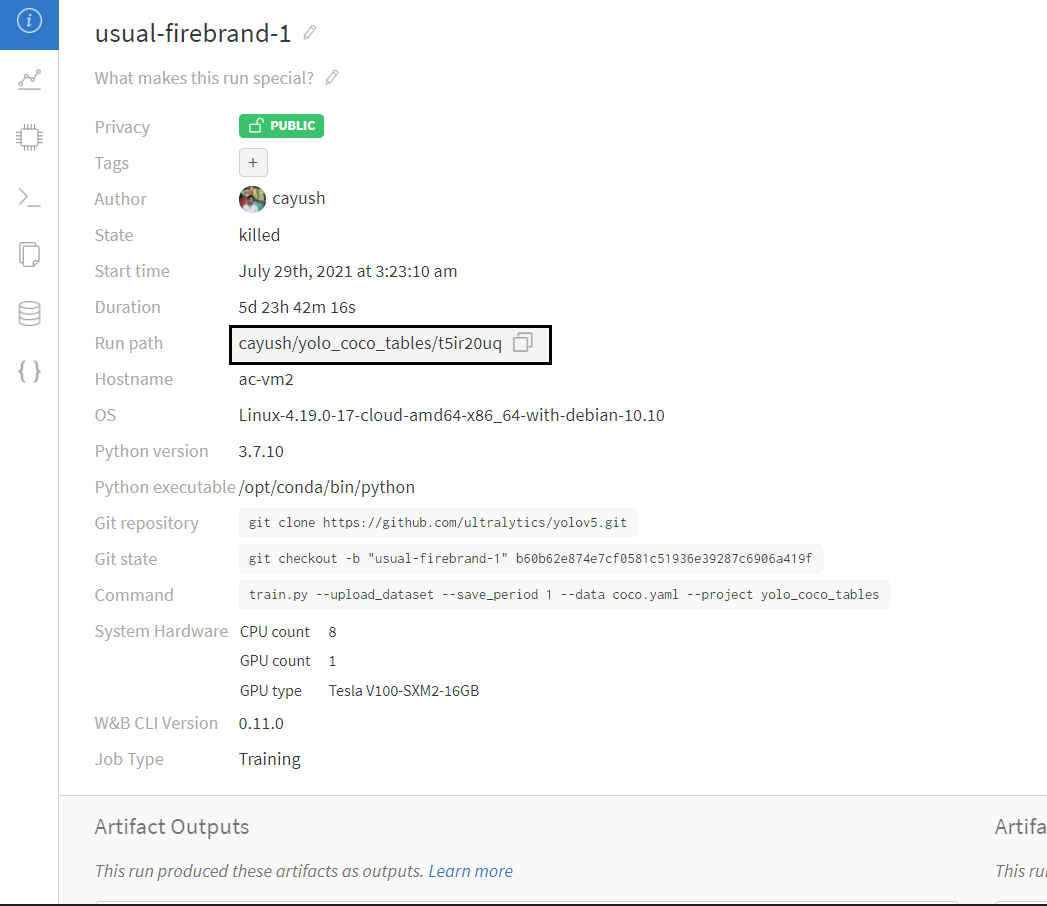
<b>Code</b> <code> $ python train.py --resume wandb-artifact://{run_path} </code>
|
||||
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> 6: Resume runs from dataset artifact & checkpoint artifacts. </h3>
|
||||
<b> Local dataset or model checkpoints are not required. This can be used to resume runs directly on a different device </b>
|
||||
The syntax is same as the previous section, but you'll need to lof both the dataset and model checkpoints as artifacts, i.e, set bot <code>--upload_dataset</code> or
|
||||
The syntax is same as the previous section, but you'll need to lof both the dataset and model checkpoints as artifacts, i.e, set bot <code>--upload_dataset</code> or
|
||||
train from <code>_wandb.yaml</code> file and set <code>--save_period</code>
|
||||
|
||||
<details>
|
||||
<summary> <b>Usage</b> </summary>
|
||||
<b>Code</b> <code> $ python train.py --resume wandb-artifact://{run_path} </code>
|
||||
|
||||
|
||||

|
||||
</details>
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
<h3> Reports </h3>
|
||||
W&B Reports can be created from your saved runs for sharing online. Once a report is created you will receive a link you can use to publically share your results. Here is an example report created from the COCO128 tutorial trainings of all four YOLOv5 models ([link](https://wandb.ai/glenn-jocher/yolov5_tutorial/reports/YOLOv5-COCO128-Tutorial-Results--VmlldzozMDI5OTY)).
|
||||
|
||||
|
||||
<img width="900" alt="Weights & Biases Reports" src="https://user-images.githubusercontent.com/26833433/135394029-a17eaf86-c6c1-4b1d-bb80-b90e83aaffa7.png">
|
||||
|
||||
|
||||
|
||||
@@ -1,17 +1,17 @@
|
||||
# Hyperparameters for training
|
||||
# To set range-
|
||||
# To set range-
|
||||
# Provide min and max values as:
|
||||
# parameter:
|
||||
#
|
||||
#
|
||||
# min: scalar
|
||||
# max: scalar
|
||||
# OR
|
||||
#
|
||||
# Set a specific list of search space-
|
||||
# parameter:
|
||||
# parameter:
|
||||
# values: [scalar1, scalar2, scalar3...]
|
||||
#
|
||||
# You can use grid, bayesian and hyperopt search strategy
|
||||
#
|
||||
# You can use grid, bayesian and hyperopt search strategy
|
||||
# For more info on configuring sweeps visit - https://docs.wandb.ai/guides/sweeps/configuration
|
||||
|
||||
program: utils/loggers/wandb/sweep.py
|
||||
|
||||
@@ -5,6 +5,7 @@ import os
|
||||
import sys
|
||||
from contextlib import contextmanager
|
||||
from pathlib import Path
|
||||
from typing import Dict
|
||||
|
||||
import pkg_resources as pkg
|
||||
import yaml
|
||||
@@ -25,7 +26,7 @@ try:
|
||||
assert hasattr(wandb, '__version__') # verify package import not local dir
|
||||
except (ImportError, AssertionError):
|
||||
wandb = None
|
||||
|
||||
|
||||
RANK = int(os.getenv('RANK', -1))
|
||||
WANDB_ARTIFACT_PREFIX = 'wandb-artifact://'
|
||||
|
||||
@@ -127,7 +128,7 @@ class WandbLogger():
|
||||
arguments:
|
||||
opt (namespace) -- Commandline arguments for this run
|
||||
run_id (str) -- Run ID of W&B run to be resumed
|
||||
job_type (str) -- To set the job_type for this run
|
||||
job_type (str) -- To set the job_type for this run
|
||||
|
||||
"""
|
||||
# Pre-training routine --
|
||||
@@ -142,7 +143,8 @@ class WandbLogger():
|
||||
self.max_imgs_to_log = 16
|
||||
self.wandb_artifact_data_dict = None
|
||||
self.data_dict = None
|
||||
# It's more elegant to stick to 1 wandb.init call, but useful config data is overwritten in the WandbLogger's wandb.init call
|
||||
# It's more elegant to stick to 1 wandb.init call,
|
||||
# but useful config data is overwritten in the WandbLogger's wandb.init call
|
||||
if isinstance(opt.resume, str): # checks resume from artifact
|
||||
if opt.resume.startswith(WANDB_ARTIFACT_PREFIX):
|
||||
entity, project, run_id, model_artifact_name = get_run_info(opt.resume)
|
||||
@@ -212,7 +214,7 @@ class WandbLogger():
|
||||
Setup the necessary processes for training YOLO models:
|
||||
- Attempt to download model checkpoint and dataset artifacts if opt.resume stats with WANDB_ARTIFACT_PREFIX
|
||||
- Update data_dict, to contain info of previous run if resumed and the paths of dataset artifact if downloaded
|
||||
- Setup log_dict, initialize bbox_interval
|
||||
- Setup log_dict, initialize bbox_interval
|
||||
|
||||
arguments:
|
||||
opt (namespace) -- commandline arguments for this run
|
||||
@@ -301,7 +303,7 @@ class WandbLogger():
|
||||
path (Path) -- Path of directory containing the checkpoints
|
||||
opt (namespace) -- Command line arguments for this run
|
||||
epoch (int) -- Current epoch number
|
||||
fitness_score (float) -- fitness score for current epoch
|
||||
fitness_score (float) -- fitness score for current epoch
|
||||
best_model (boolean) -- Boolean representing if the current checkpoint is the best yet.
|
||||
"""
|
||||
model_artifact = wandb.Artifact('run_' + wandb.run.id + '_model', type='model', metadata={
|
||||
@@ -325,7 +327,7 @@ class WandbLogger():
|
||||
data_file (str) -- the .yaml file with information about the dataset like - path, classes etc.
|
||||
single_class (boolean) -- train multi-class data as single-class
|
||||
project (str) -- project name. Used to construct the artifact path
|
||||
overwrite_config (boolean) -- overwrites the data.yaml file if set to true otherwise creates a new
|
||||
overwrite_config (boolean) -- overwrites the data.yaml file if set to true otherwise creates a new
|
||||
file with _wandb postfix. Eg -> data_wandb.yaml
|
||||
|
||||
returns:
|
||||
@@ -371,14 +373,14 @@ class WandbLogger():
|
||||
for i, data in enumerate(tqdm(self.val_table.data)):
|
||||
self.val_table_path_map[data[3]] = data[0]
|
||||
|
||||
def create_dataset_table(self, dataset, class_to_id, name='dataset'):
|
||||
def create_dataset_table(self, dataset: LoadImagesAndLabels, class_to_id: Dict[int,str], name: str = 'dataset'):
|
||||
"""
|
||||
Create and return W&B artifact containing W&B Table of the dataset.
|
||||
|
||||
arguments:
|
||||
dataset (LoadImagesAndLabels) -- instance of LoadImagesAndLabels class used to iterate over the data to build Table
|
||||
class_to_id (dict(int, str)) -- hash map that maps class ids to labels
|
||||
name (str) -- name of the artifact
|
||||
dataset -- instance of LoadImagesAndLabels class used to iterate over the data to build Table
|
||||
class_to_id -- hash map that maps class ids to labels
|
||||
name -- name of the artifact
|
||||
|
||||
returns:
|
||||
dataset artifact to be logged or used
|
||||
@@ -419,7 +421,7 @@ class WandbLogger():
|
||||
|
||||
arguments:
|
||||
predn (list): list of predictions in the native space in the format - [xmin, ymin, xmax, ymax, confidence, class]
|
||||
path (str): local path of the current evaluation image
|
||||
path (str): local path of the current evaluation image
|
||||
names (dict(int, str)): hash map that maps class ids to labels
|
||||
"""
|
||||
class_set = wandb.Classes([{'id': id, 'name': name} for id, name in names.items()])
|
||||
@@ -430,7 +432,7 @@ class WandbLogger():
|
||||
box_data.append(
|
||||
{"position": {"minX": xyxy[0], "minY": xyxy[1], "maxX": xyxy[2], "maxY": xyxy[3]},
|
||||
"class_id": int(cls),
|
||||
"box_caption": "%s %.3f" % (names[cls], conf),
|
||||
"box_caption": f"{names[cls]} {conf:.3f}",
|
||||
"scores": {"class_score": conf},
|
||||
"domain": "pixel"})
|
||||
total_conf += conf
|
||||
@@ -450,7 +452,7 @@ class WandbLogger():
|
||||
arguments:
|
||||
pred (list): list of scaled predictions in the format - [xmin, ymin, xmax, ymax, confidence, class]
|
||||
predn (list): list of predictions in the native space - [xmin, ymin, xmax, ymax, confidence, class]
|
||||
path (str): local path of the current evaluation image
|
||||
path (str): local path of the current evaluation image
|
||||
"""
|
||||
if self.val_table and self.result_table: # Log Table if Val dataset is uploaded as artifact
|
||||
self.log_training_progress(predn, path, names)
|
||||
@@ -459,7 +461,7 @@ class WandbLogger():
|
||||
if self.current_epoch % self.bbox_interval == 0:
|
||||
box_data = [{"position": {"minX": xyxy[0], "minY": xyxy[1], "maxX": xyxy[2], "maxY": xyxy[3]},
|
||||
"class_id": int(cls),
|
||||
"box_caption": "%s %.3f" % (names[cls], conf),
|
||||
"box_caption": f"{names[cls]} {conf:.3f}",
|
||||
"scores": {"class_score": conf},
|
||||
"domain": "pixel"} for *xyxy, conf, cls in pred.tolist()]
|
||||
boxes = {"predictions": {"box_data": box_data, "class_labels": names}} # inference-space
|
||||
|
||||
Reference in new issue
Block a user